梯度消失與爆炸

Intermediate Deep Learning with PyTorch

Michal Oleszak

Machine Learning Engineer

梯度消失
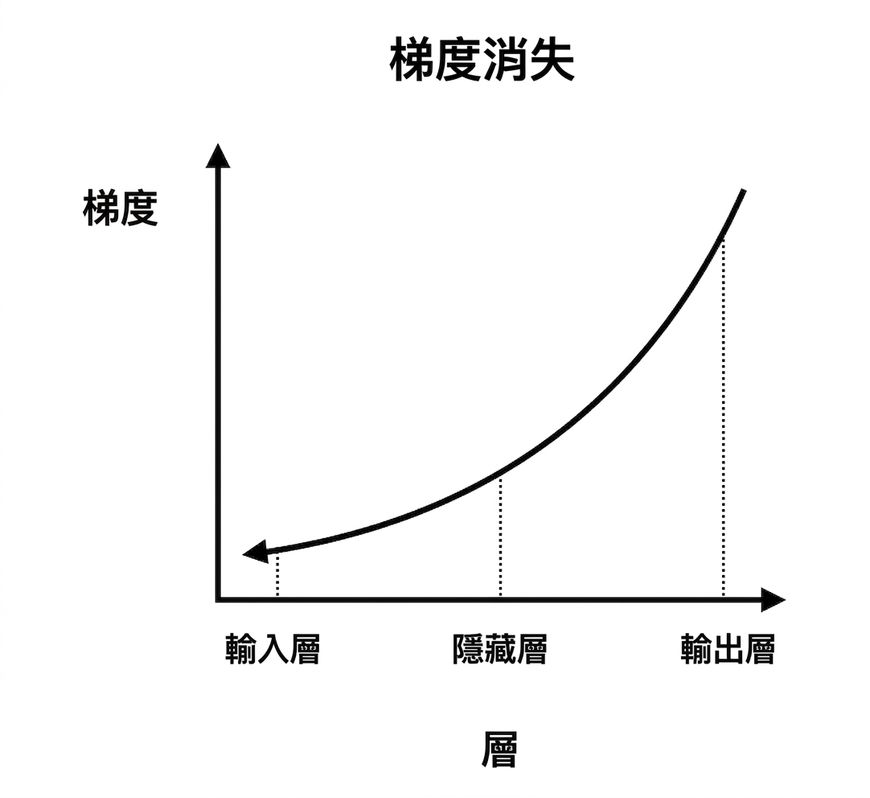
  • 反向傳播時梯度越來越小
  • 前面層的參數更新很小
  • 模型學不動

顯示梯度大小與層索引的圖:較早的層梯度較小

Intermediate Deep Learning with PyTorch

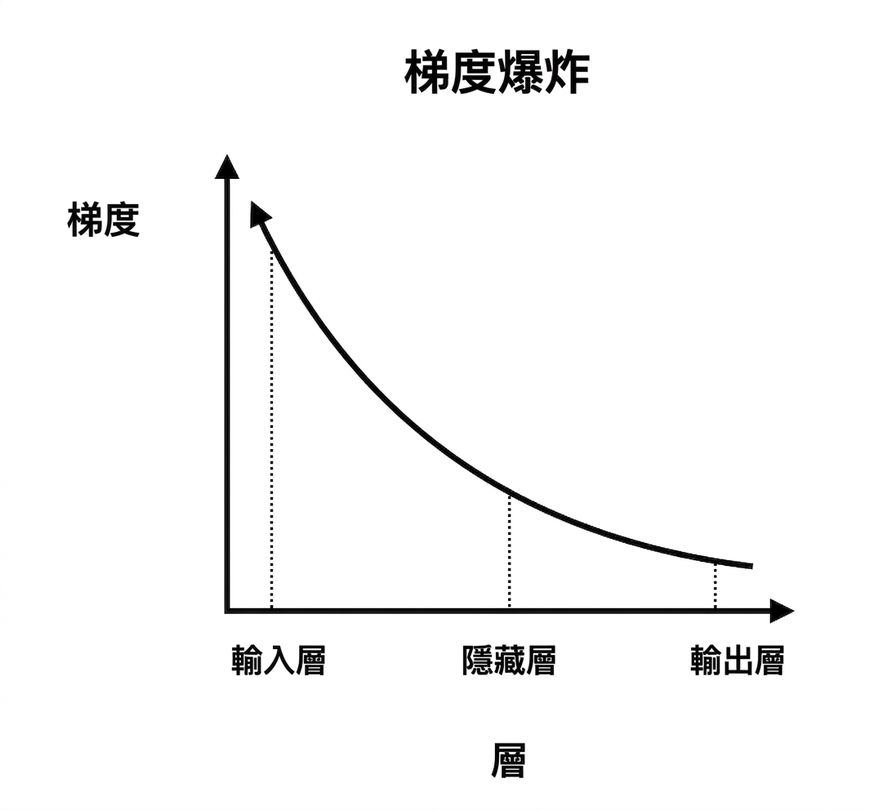
梯度爆炸

  • 梯度越來越大
  • 參數更新過大
  • 訓練發散

顯示梯度大小與層索引的圖:較早的層梯度較大

Intermediate Deep Learning with PyTorch

穩定梯度的解方

  1. 合適的權重初始化
  2. 良好的啟用函式
  3. 批次正規化


三個步驟

Intermediate Deep Learning with PyTorch

權重初始化

layer = nn.Linear(8, 1)
print(layer.weight)
Parameter containing:
tensor([[-0.0195,  0.0992,  0.0391,  0.0212,
         -0.3386, -0.1892, -0.3170,  0.2148]])
Intermediate Deep Learning with PyTorch

權重初始化

良好初始化可確保:

  • 層輸入的變異數 = 層輸出的變異數
  • 層前後的梯度變異數相同


如何達成取決於啟用函式:

  • 對 ReLU 與相近者,可用 He/Kaiming 初始化
Intermediate Deep Learning with PyTorch

權重初始化

import torch.nn.init as init

init.kaiming_uniform_(layer.weight)
print(layer.weight)
Parameter containing:
tensor([[-0.3063, -0.2410,  0.0588,  0.2664,
          0.0502, -0.0136,  0.2274,  0.0901]])
Intermediate Deep Learning with PyTorch

He/Kaiming 初始化

init.kaiming_uniform_(self.fc1.weight)
init.kaiming_uniform_(self.fc2.weight)
init.kaiming_uniform_(
  self.fc3.weight,
  nonlinearity="sigmoid",
)
Intermediate Deep Learning with PyTorch

He/Kaiming 初始化

import torch.nn as nn
import torch.nn.init as init

class Net(nn.Module):
    def __init__(self):
        super().__init__()
        self.fc1 = nn.Linear(9, 16)
        self.fc2 = nn.Linear(16, 8)
        self.fc3 = nn.Linear(8, 1)


init.kaiming_uniform_(self.fc1.weight) init.kaiming_uniform_(self.fc2.weight) init.kaiming_uniform_( self.fc3.weight, nonlinearity="sigmoid", )


    def forward(self, x):
        x = nn.functional.relu(self.fc1(x))
        x = nn.functional.relu(self.fc2(x))
        x = nn.functional.sigmoid(self.fc3(x))
        return x


Intermediate Deep Learning with PyTorch

啟用函式

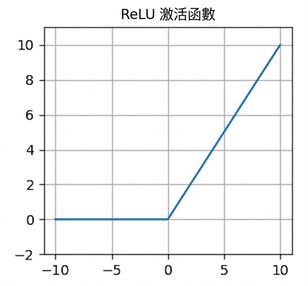
ReLU 函式示意圖:小於 0 為 0 的水平線;大於 0 為正斜率直線

  • 常作為預設啟用函式
  • nn.functional.relu()
  • 負輸入為 0,可能出現神經元死亡

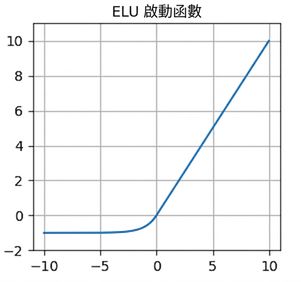
ELU 函式示意圖:類似 ReLU,但負值區域平滑過渡至正區域

  • nn.functional.elu()
  • 負值也有非零梯度,有助減少神經元死亡
  • 輸出均值約為 0,有助緩解梯度消失
Intermediate Deep Learning with PyTorch

批次正規化(Batch Normalization)

經過一層後:

  1. 將該層輸出正規化:

    • 減去平均值
    • 除以標準差
  2. 用可學參數縮放與平移正規化後的輸出

模型為每層學到最佳輸入分佈:

  • 損失下降更快
  • 有助穩定梯度
Intermediate Deep Learning with PyTorch

批次正規化(Batch Normalization)

class Net(nn.Module):
    def __init__(self):
        super().__init__()
        self.fc1 = nn.Linear(9, 16)
        self.bn1 = nn.BatchNorm1d(16)

        ...


def forward(self, x): x = self.fc1(x) x = self.bn1(x) x = nn.functional.elu(x) ...
Intermediate Deep Learning with PyTorch

一起來練習吧!

Intermediate Deep Learning with PyTorch

Preparing Video For Download...