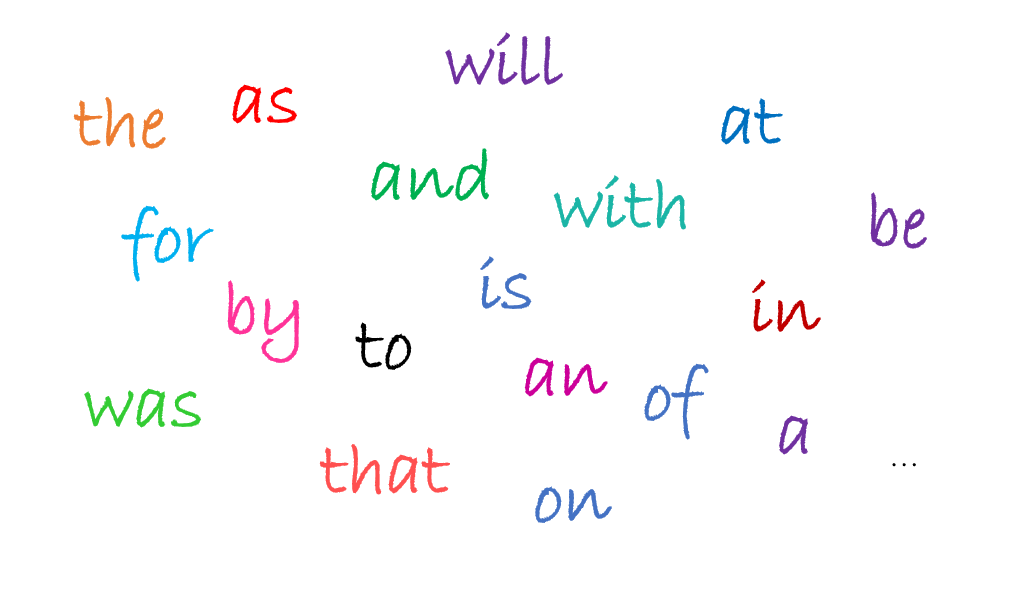停用詞與標點處理

Python 的 Natural Language Processing(NLP)

Fouad Trad

Machine Learning Engineer

停用詞(Stop words)

  • 常見但對機器理解語境幫助不大
  • 在許多 NLP 任務中價值不高
  • 移除可讓模型聚焦重要詞彙

影像顯示多個停用詞,如 a、an、the、in、of、that、for、by 等

Python 的 Natural Language Processing(NLP)

移除停用詞

適用於

掌握文本主題

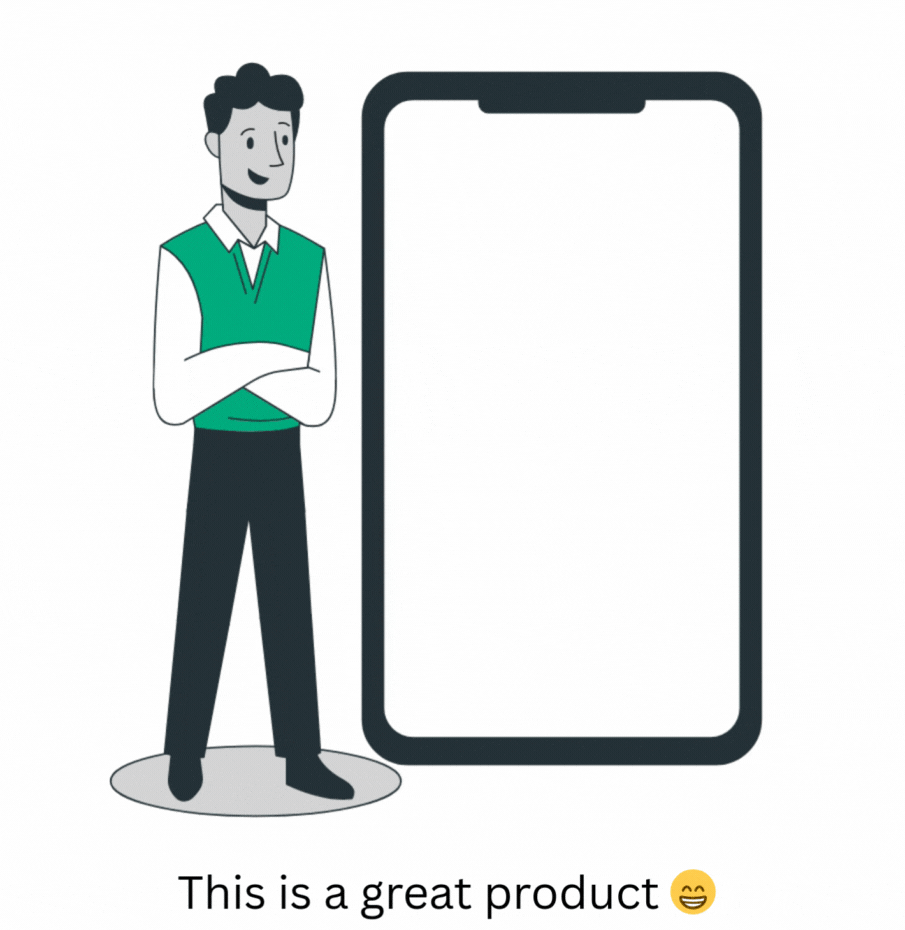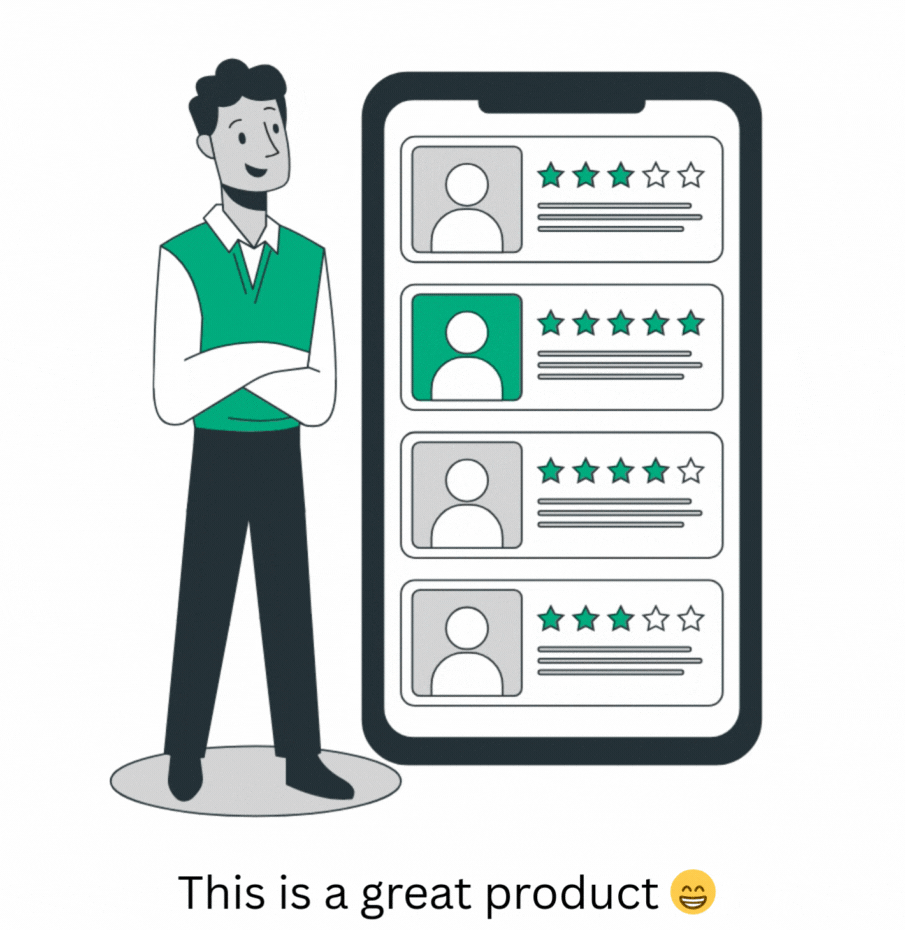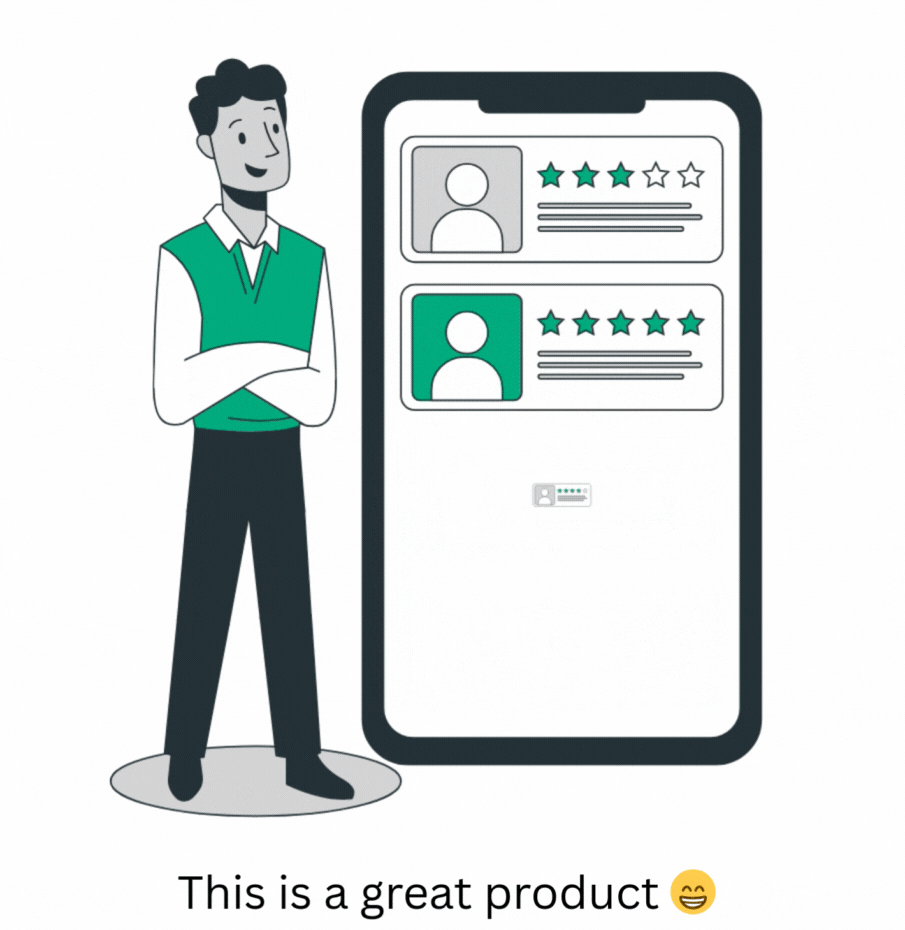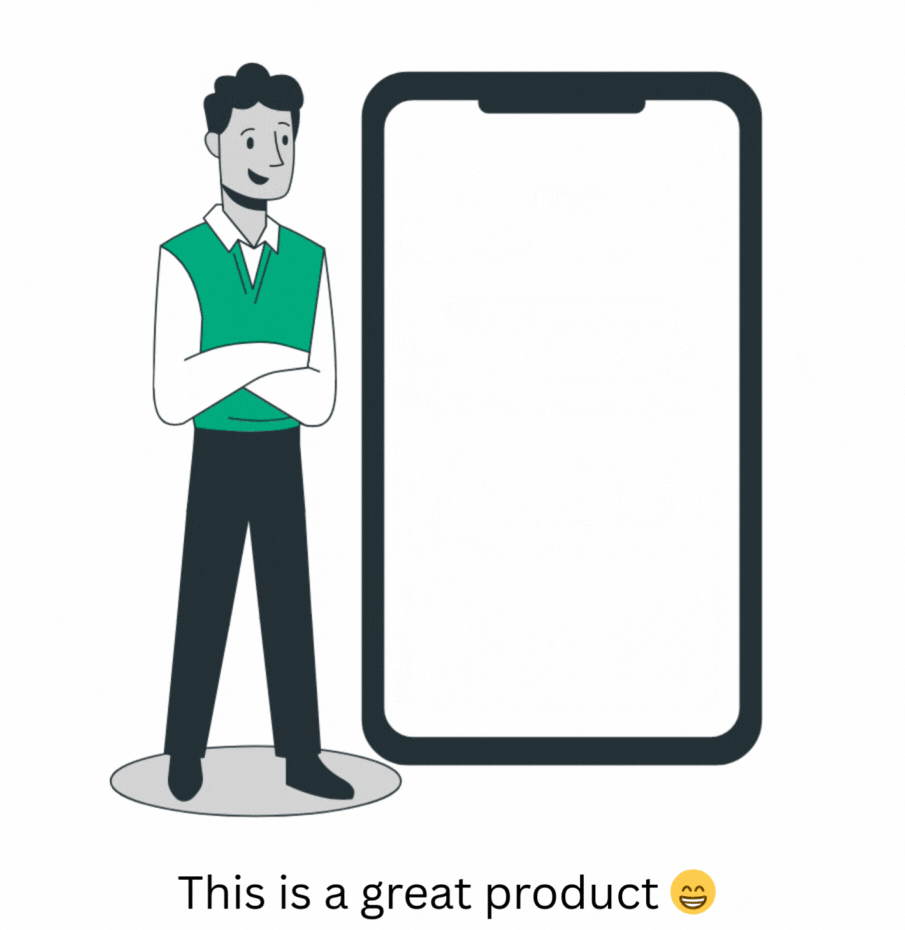
影像顯示行動應用程式中的產品評論

Python 的 Natural Language Processing(NLP)

移除停用詞

適用於

掌握文本主題

影像顯示行動應用程式中的產品評論

不適用於

需要保留每個詞的任務

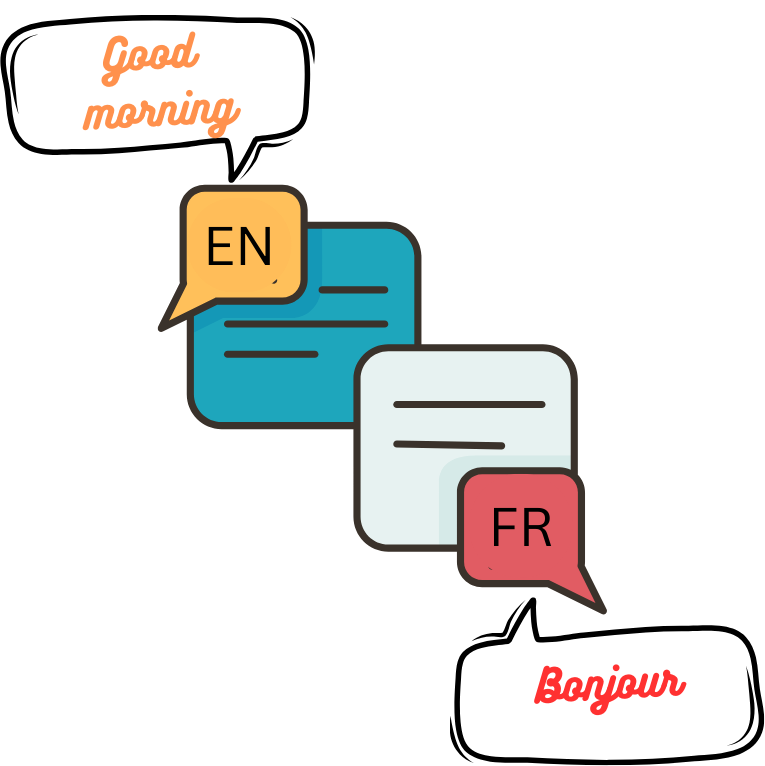
影像顯示將英文(Good morning)翻譯成法文(Bonjour)

Python 的 Natural Language Processing(NLP)

取得停用詞

NLTK 提供多種語言的停用詞清單

from nltk.corpus import stopwords
nltk.download('stopwords')

stop_words = stopwords.words('english')
print(stop_words[:10])
['a', 'about', 'above', 'after', 'again', 'against', 'ain', 'all', 'am', 'an']
Python 的 Natural Language Processing(NLP)

移除停用詞

from nltk.tokenize import word_tokenize

text = "This is an example to demonstrate removing stop words."
tokens = word_tokenize(text)
# The .lower() method helps with case sensitivity filtered_tokens = [word for word in tokens if word.lower() not in stop_words]
print(filtered_tokens)
['example', 'demonstrate', 'removing', 'stop', 'words', '.']
Python 的 Natural Language Processing(NLP)

標點符號

  • 為人類組織語言
  • 在許多 NLP 任務中缺乏資訊性

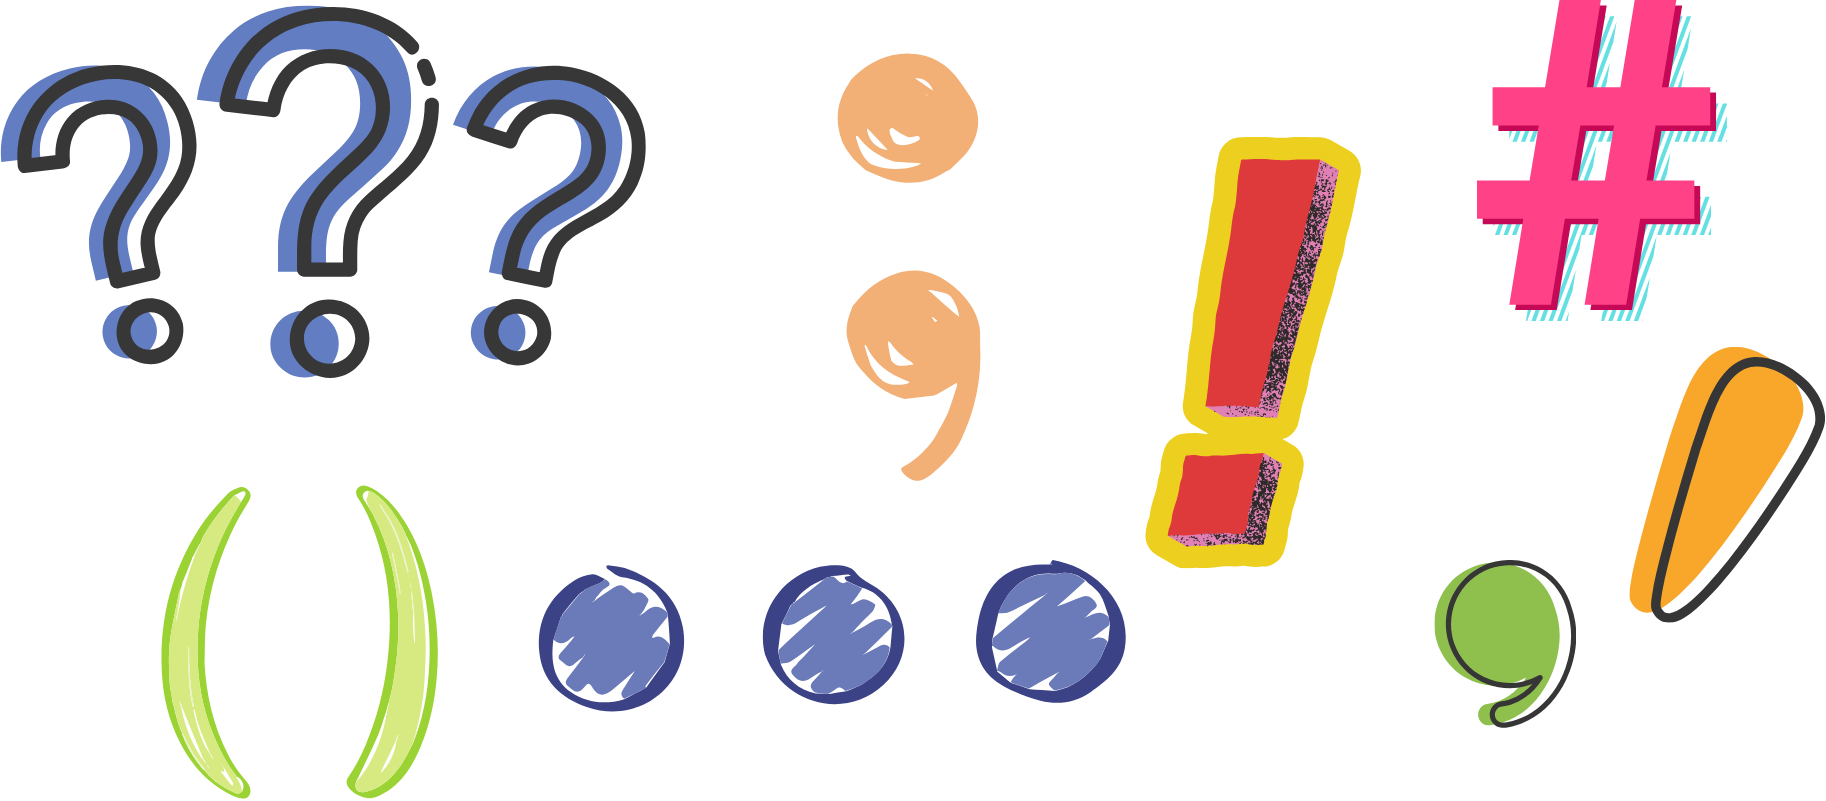
影像顯示標點符號與特殊字元

Python 的 Natural Language Processing(NLP)

移除標點

適用於

需要找出文件中常見或重要詞的任務

影像顯示需處理的多個檔案與文件

Python 的 Natural Language Processing(NLP)

移除標點

適用於

需要找出文件中常見或重要詞的任務

影像顯示需處理的多個檔案與文件

不適用於

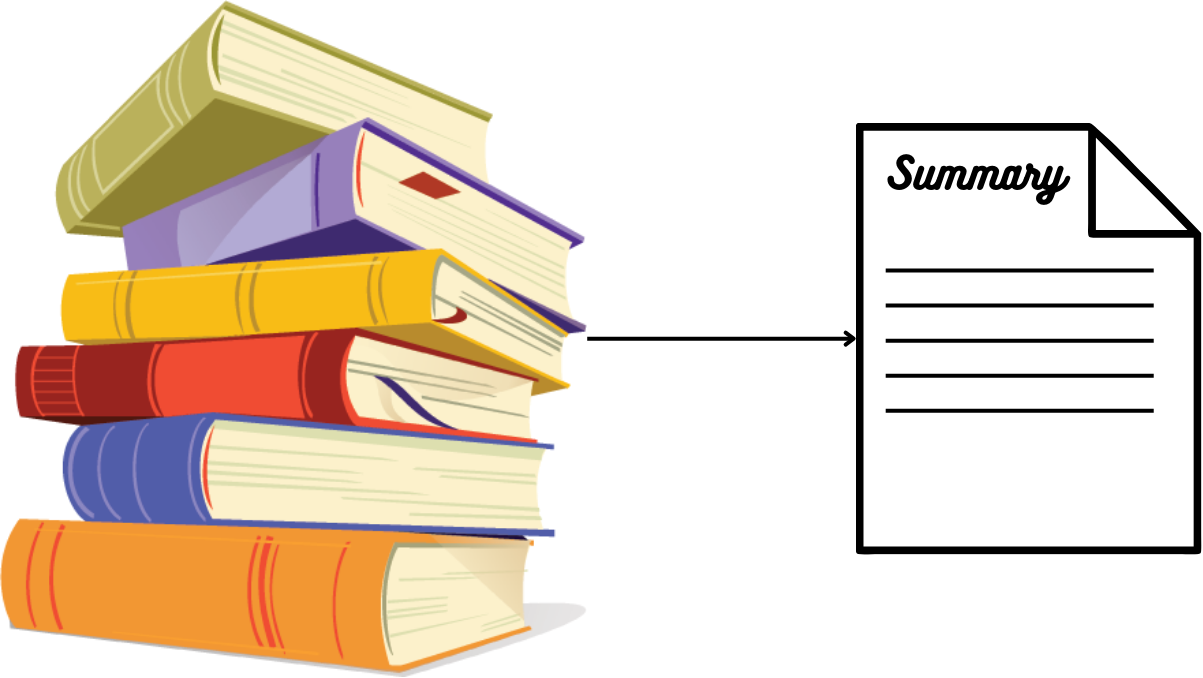
需要保留句子結構以維持清晰度的任務

影像顯示一疊書與其產生的摘要文件

Python 的 Natural Language Processing(NLP)

取得並移除標點

import string
print(string.punctuation)
!"#$%&'()*+,-./:;<=>?@[\]^_`{|}~
text = "This is an example to demonstrate removing stop words."
tokens = word_tokenize(text)
filtered_tokens = [word for word in tokens if word.lower() not in stop_words]

clean_tokens = [word for word in filtered_tokens if word not in string.punctuation]
print(clean_tokens)
['example', 'demonstrate', 'removing', 'stop', 'words']
Python 的 Natural Language Processing(NLP)

一起來練習吧!

Python 的 Natural Language Processing(NLP)

Preparing Video For Download...