實作範例
Python 測試入門

Alexander Levin
Data Scientist
資料與流程
資料:資料科學薪資。
每列包含一位資料科學從業者的薪資、職稱與其他屬性。
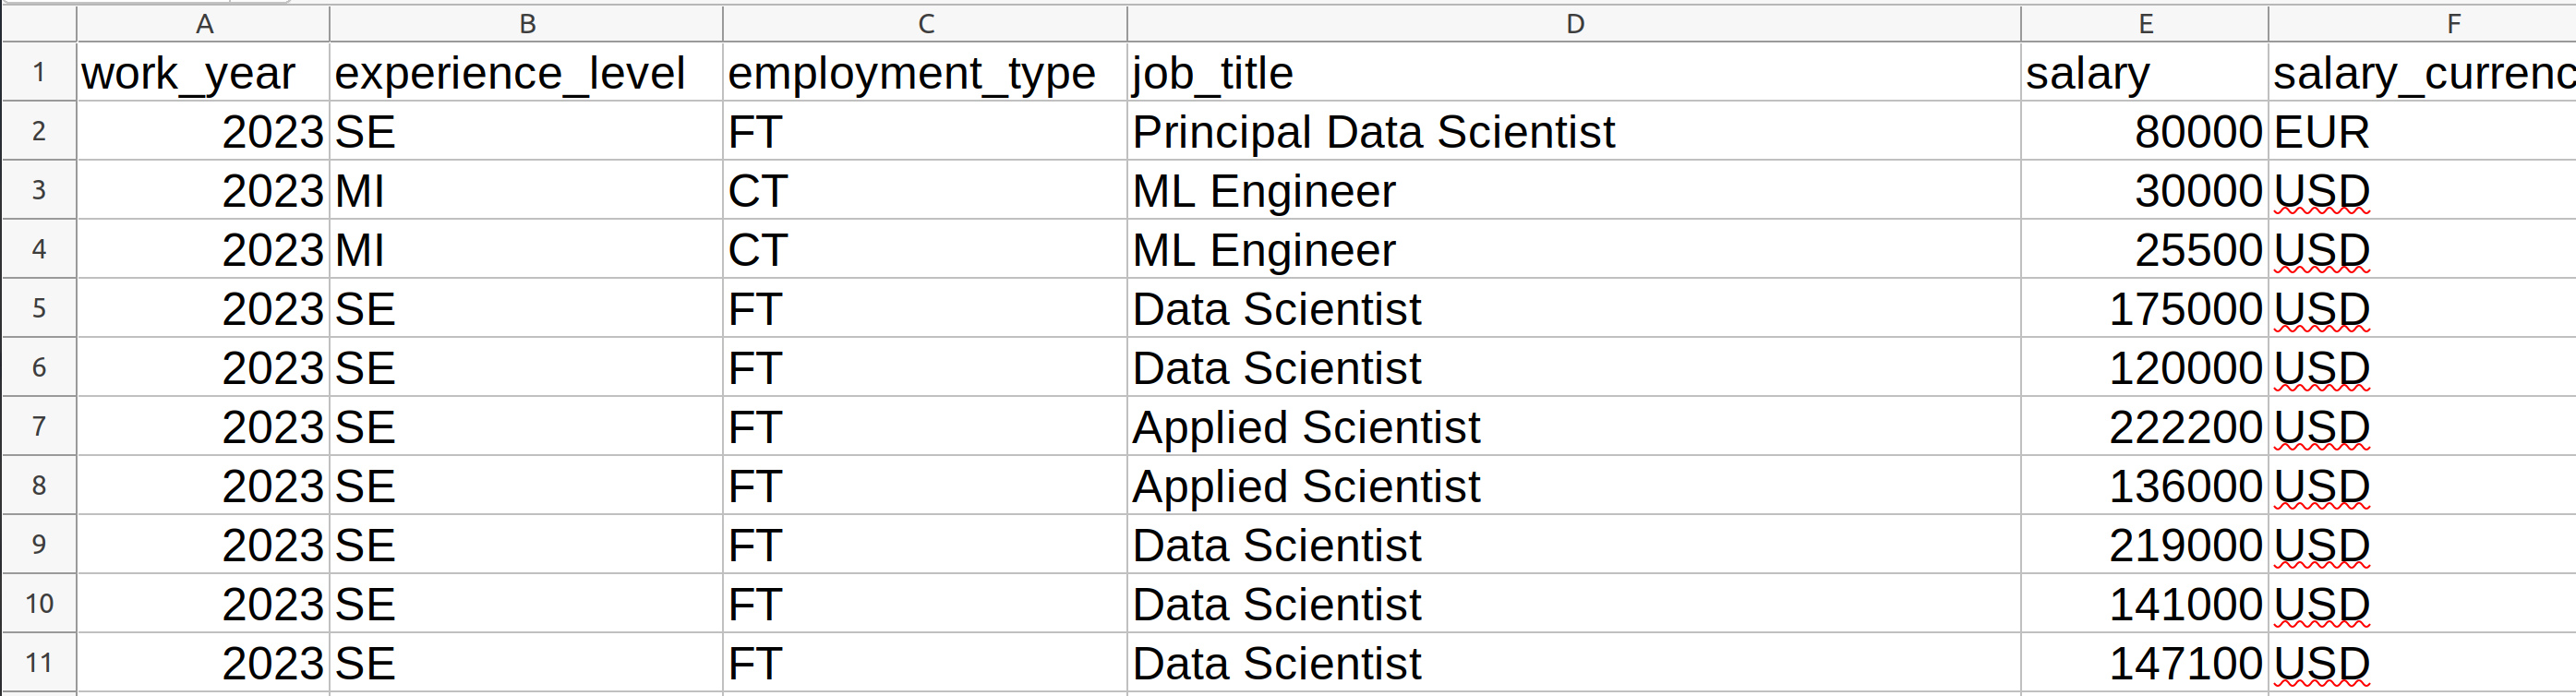
流程:計算平均薪資:
- 讀取資料
- 依雇用型態篩選
- 計算平均薪資
- 儲存結果
流程程式碼
import pandas as pd

# Fixture to get the data
@pytest.fixture
def read_df():
    return pd.read_csv('ds_salaries.csv')
# Function to filter the data
def filter_df(df):
    return df[df['employment_type'] == 'FT']
# Function to get the mean
def get_mean(df):
    return df['salary_in_usd'].mean()
整合測試
測試案例:
- 讀取資料
- 寫入檔案
程式碼:
def test_read_df(read_df):
    # Check the type of the dataframe
    assert isinstance(read_df, pd.DataFrame)
    # Check that df contains rows
    assert read_df.shape[0] > 0
整合測試
檢查 Python 能建立檔案的範例。
def test_write():
    # Opening a file in writing mode
    with open('temp.txt', 'w') as wfile:
        # Writing the text to the file
        wfile.write('Testing stuff is awesome')
    # Checking the file exists
    assert os.path.exists('temp.txt')
    # Don't forget to clean after yourself
    os.remove('temp.txt')
單元測試
測試案例:
- 篩選後的資料集僅包含「FT」雇用型態
get_mean()函式回傳數值
程式碼:
def test_units(read_df):
    filtered = filter_df(read_df)
    assert filtered['employment_type'].unique() == ['FT']
    assert isinstance(get_mean(filtered), float)
功能測試
測試案例:
- 平均值大於 0
- 平均值不大於資料集中的最大薪資
程式碼:
def test_feature(read_df):
    # Filtering the data
    filtered = filter_df(read_df)
    # Test case: mean is greater than zero
    assert get_mean(filtered) > 0
    # Test case: mean is not bigger than the maximum
    assert get_mean(filtered) <= read_df['salary_in_usd'].max()
效能測試
測試案例:
- 流程從開始到結束的執行時間
程式碼:
def test_performance(benchmark, read_df):
    # Benchmark decorator
    @benchmark
    # Function to measure
    def get_result():
        filtered = filter_df(read_df)
        return get_mean(filtered)
最終測試套件
import pytest

## Integration Tests
def test_read_df(read_df):
      # Check the type of the dataframe
    assert isinstance(read_df, pd.DataFrame)
    # Check that df contains rows
    assert read_df.shape[0] > 0
def test_write():
    with open('temp.txt', 'w') as wfile:
        wfile.write('12345')
    assert os.path.exists('temp.txt')
    os.remove('temp.txt')

## Unit Tests
def test_units(read_df):
    filtered = filter_df(read_df)
    assert filtered['employment_type'].unique() == ['FT']
    assert isinstance(get_mean(filtered), float)
## Feature Tests
def test_feature(read_df):
    # Filtering the data
    filtered = filter_df(read_df)
    # Test case: mean is greater than zero
    assert get_mean(filtered) > 0
    # Test case: mean is not bigger than the maximum
    assert get_mean(filtered) <= read_df['salary_in_usd'].max()

## Performance Tests
def test_performance(benchmark, read_df):
    # Benchmark decorator
    @benchmark
    # Function to measure
    def pipeline():
        filtered = filter_df(read_df)
        return get_mean(filtered)
一起來練習吧!
Python 測試入門

