Databricks Lakehouse 入門
Gang Wang
Senior Data Scientist
$$
# Default language: Python
df = spark.table("silver_taxi_trips")
display(df)
%sql
SELECT COUNT(*) AS total_trips
FROM silver_taxi_trips
%md
## Analysis notes
Revenue is **highest** in the Northeast region.
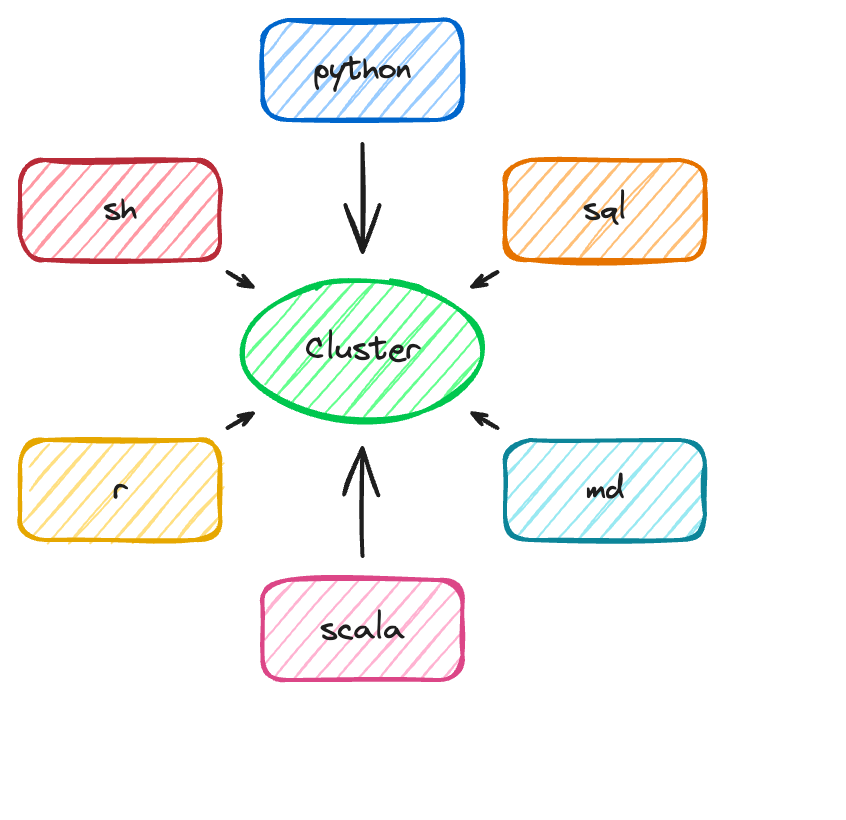
%python
%sql
%scala
%r
%md
%sh
%run
# 載入共用輔助函式
%run /Shared/utils/data_helpers
# 現在可使用 data_helpers 中
# 定義的函式
clean_df = clean_nulls(raw_df)