拆解 Transformer

Transformer Models with PyTorch

James Chapman

Curriculum Manager, DataCamp

改變一切的論文…


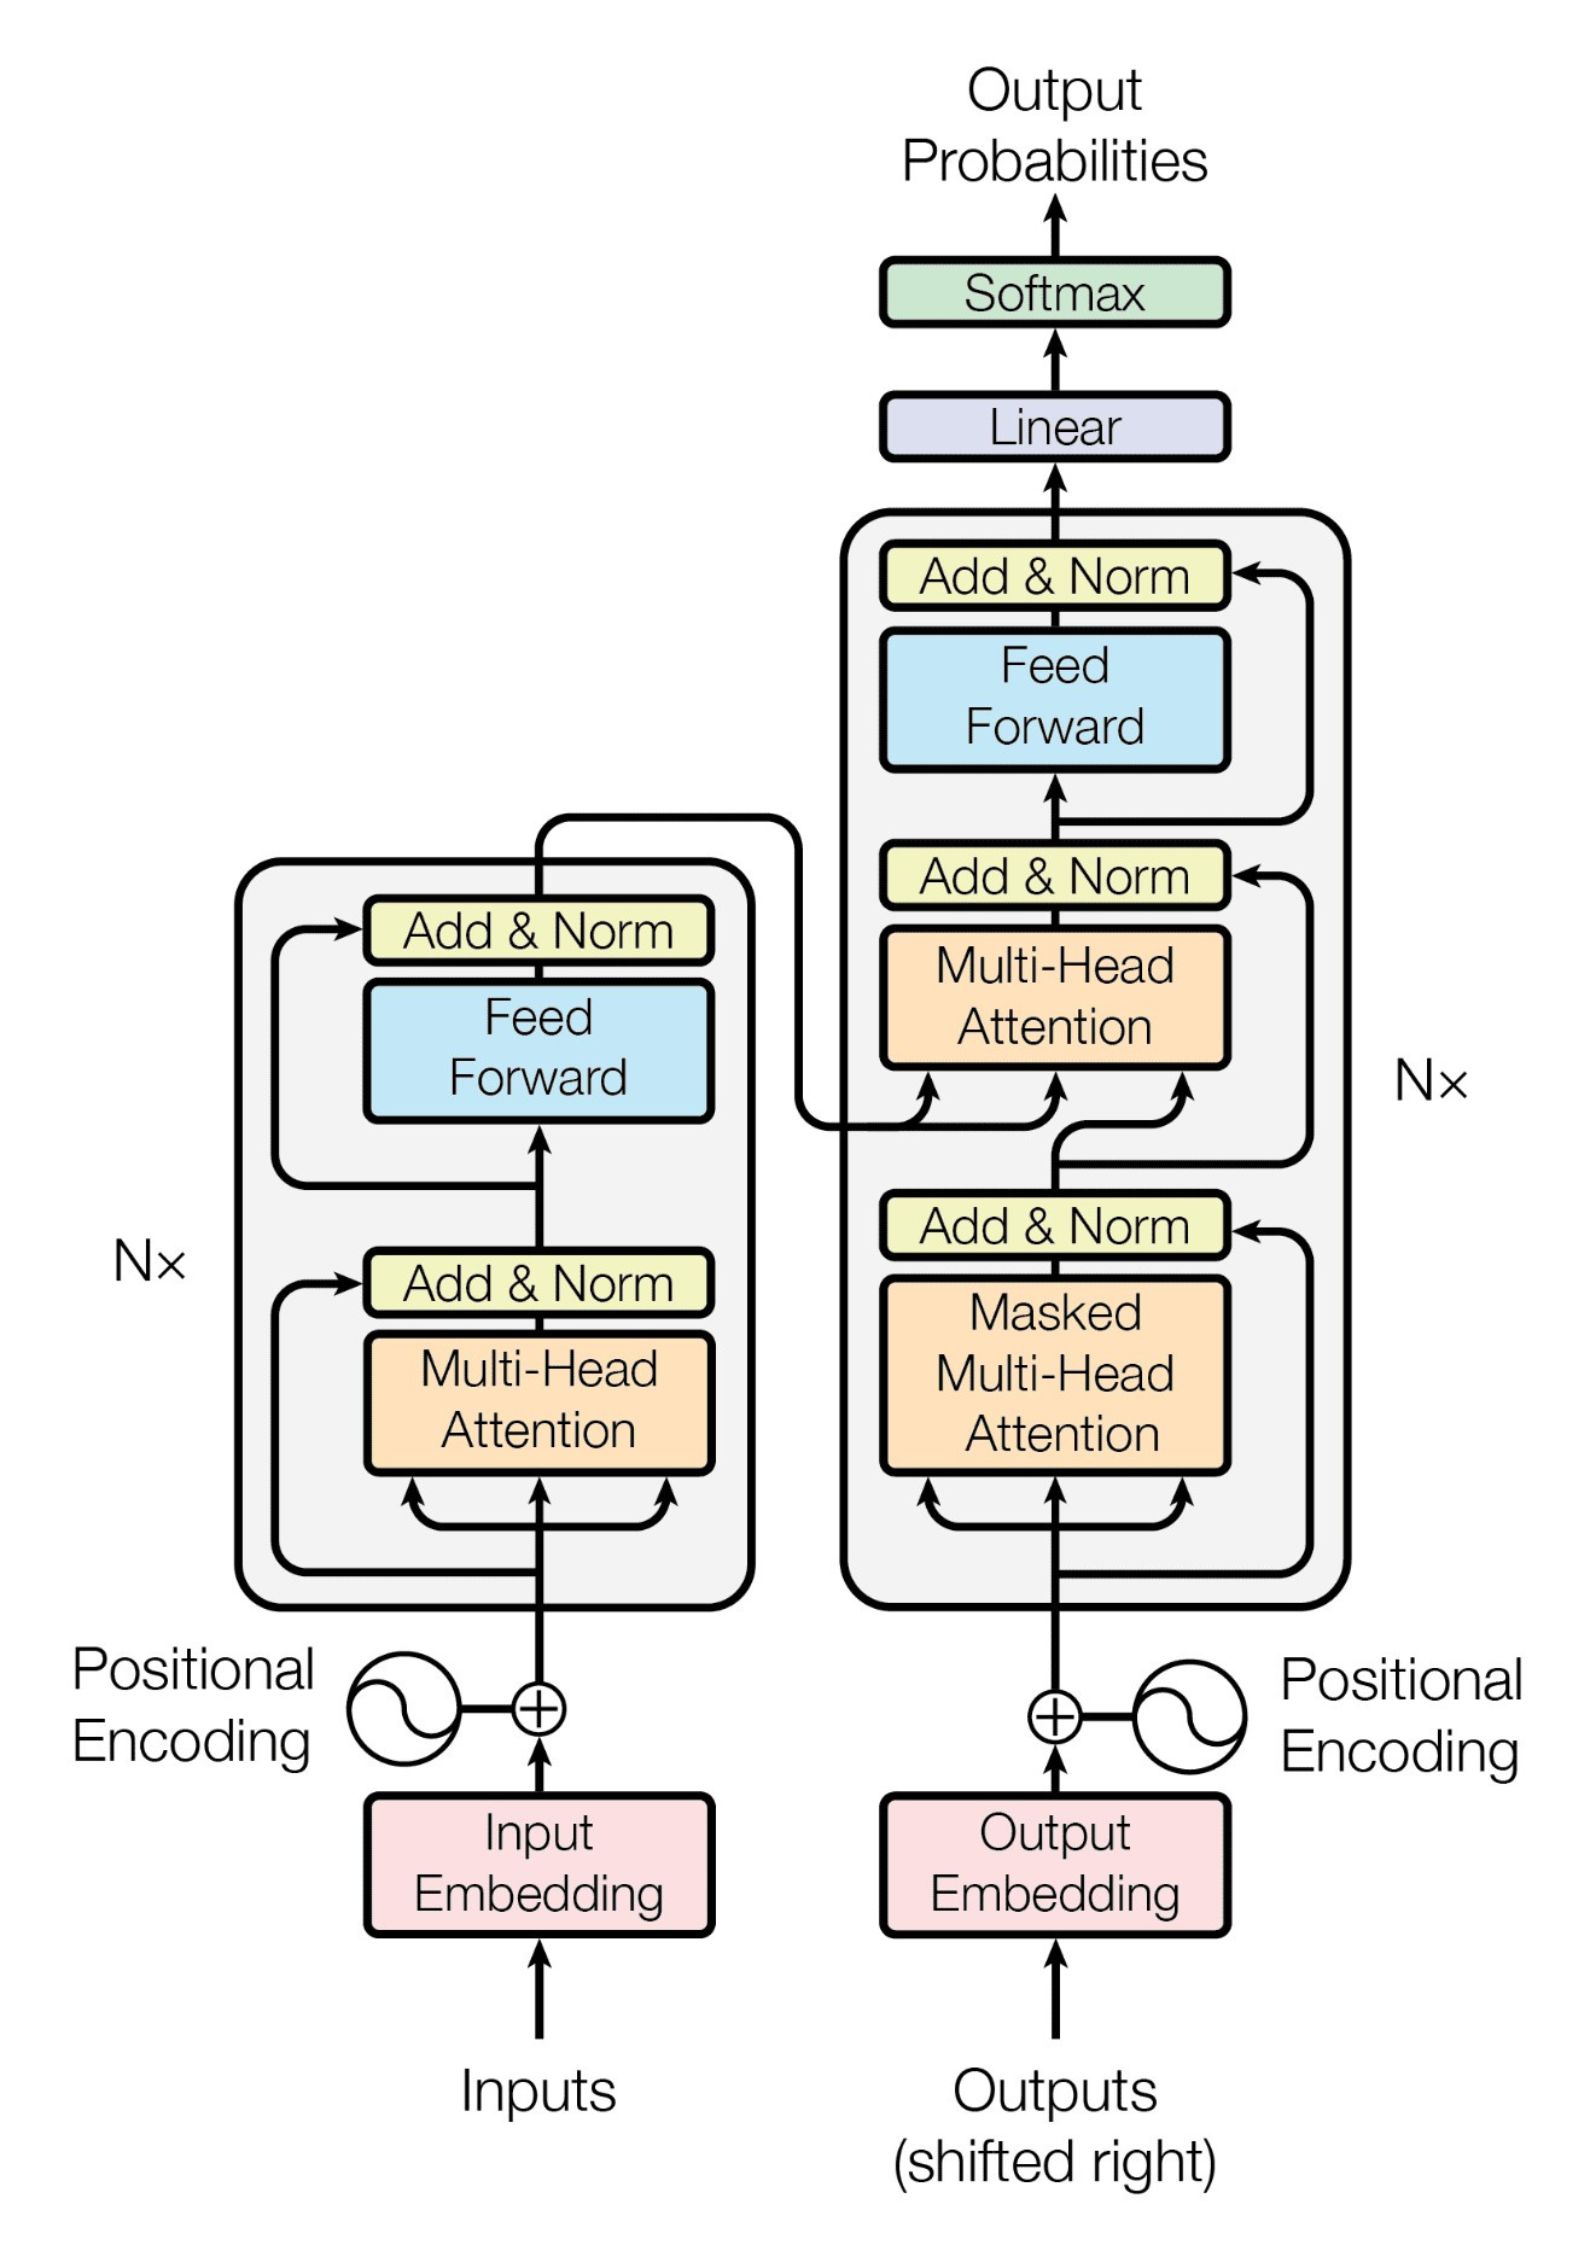
  • Ashish Vaswani 等人所著的 Attention Is All You Need(arXiv:1706.03762)
    • 注意力機制
    • 為文字建模最佳化
    • 應用於 大型語言模型(LLMs)

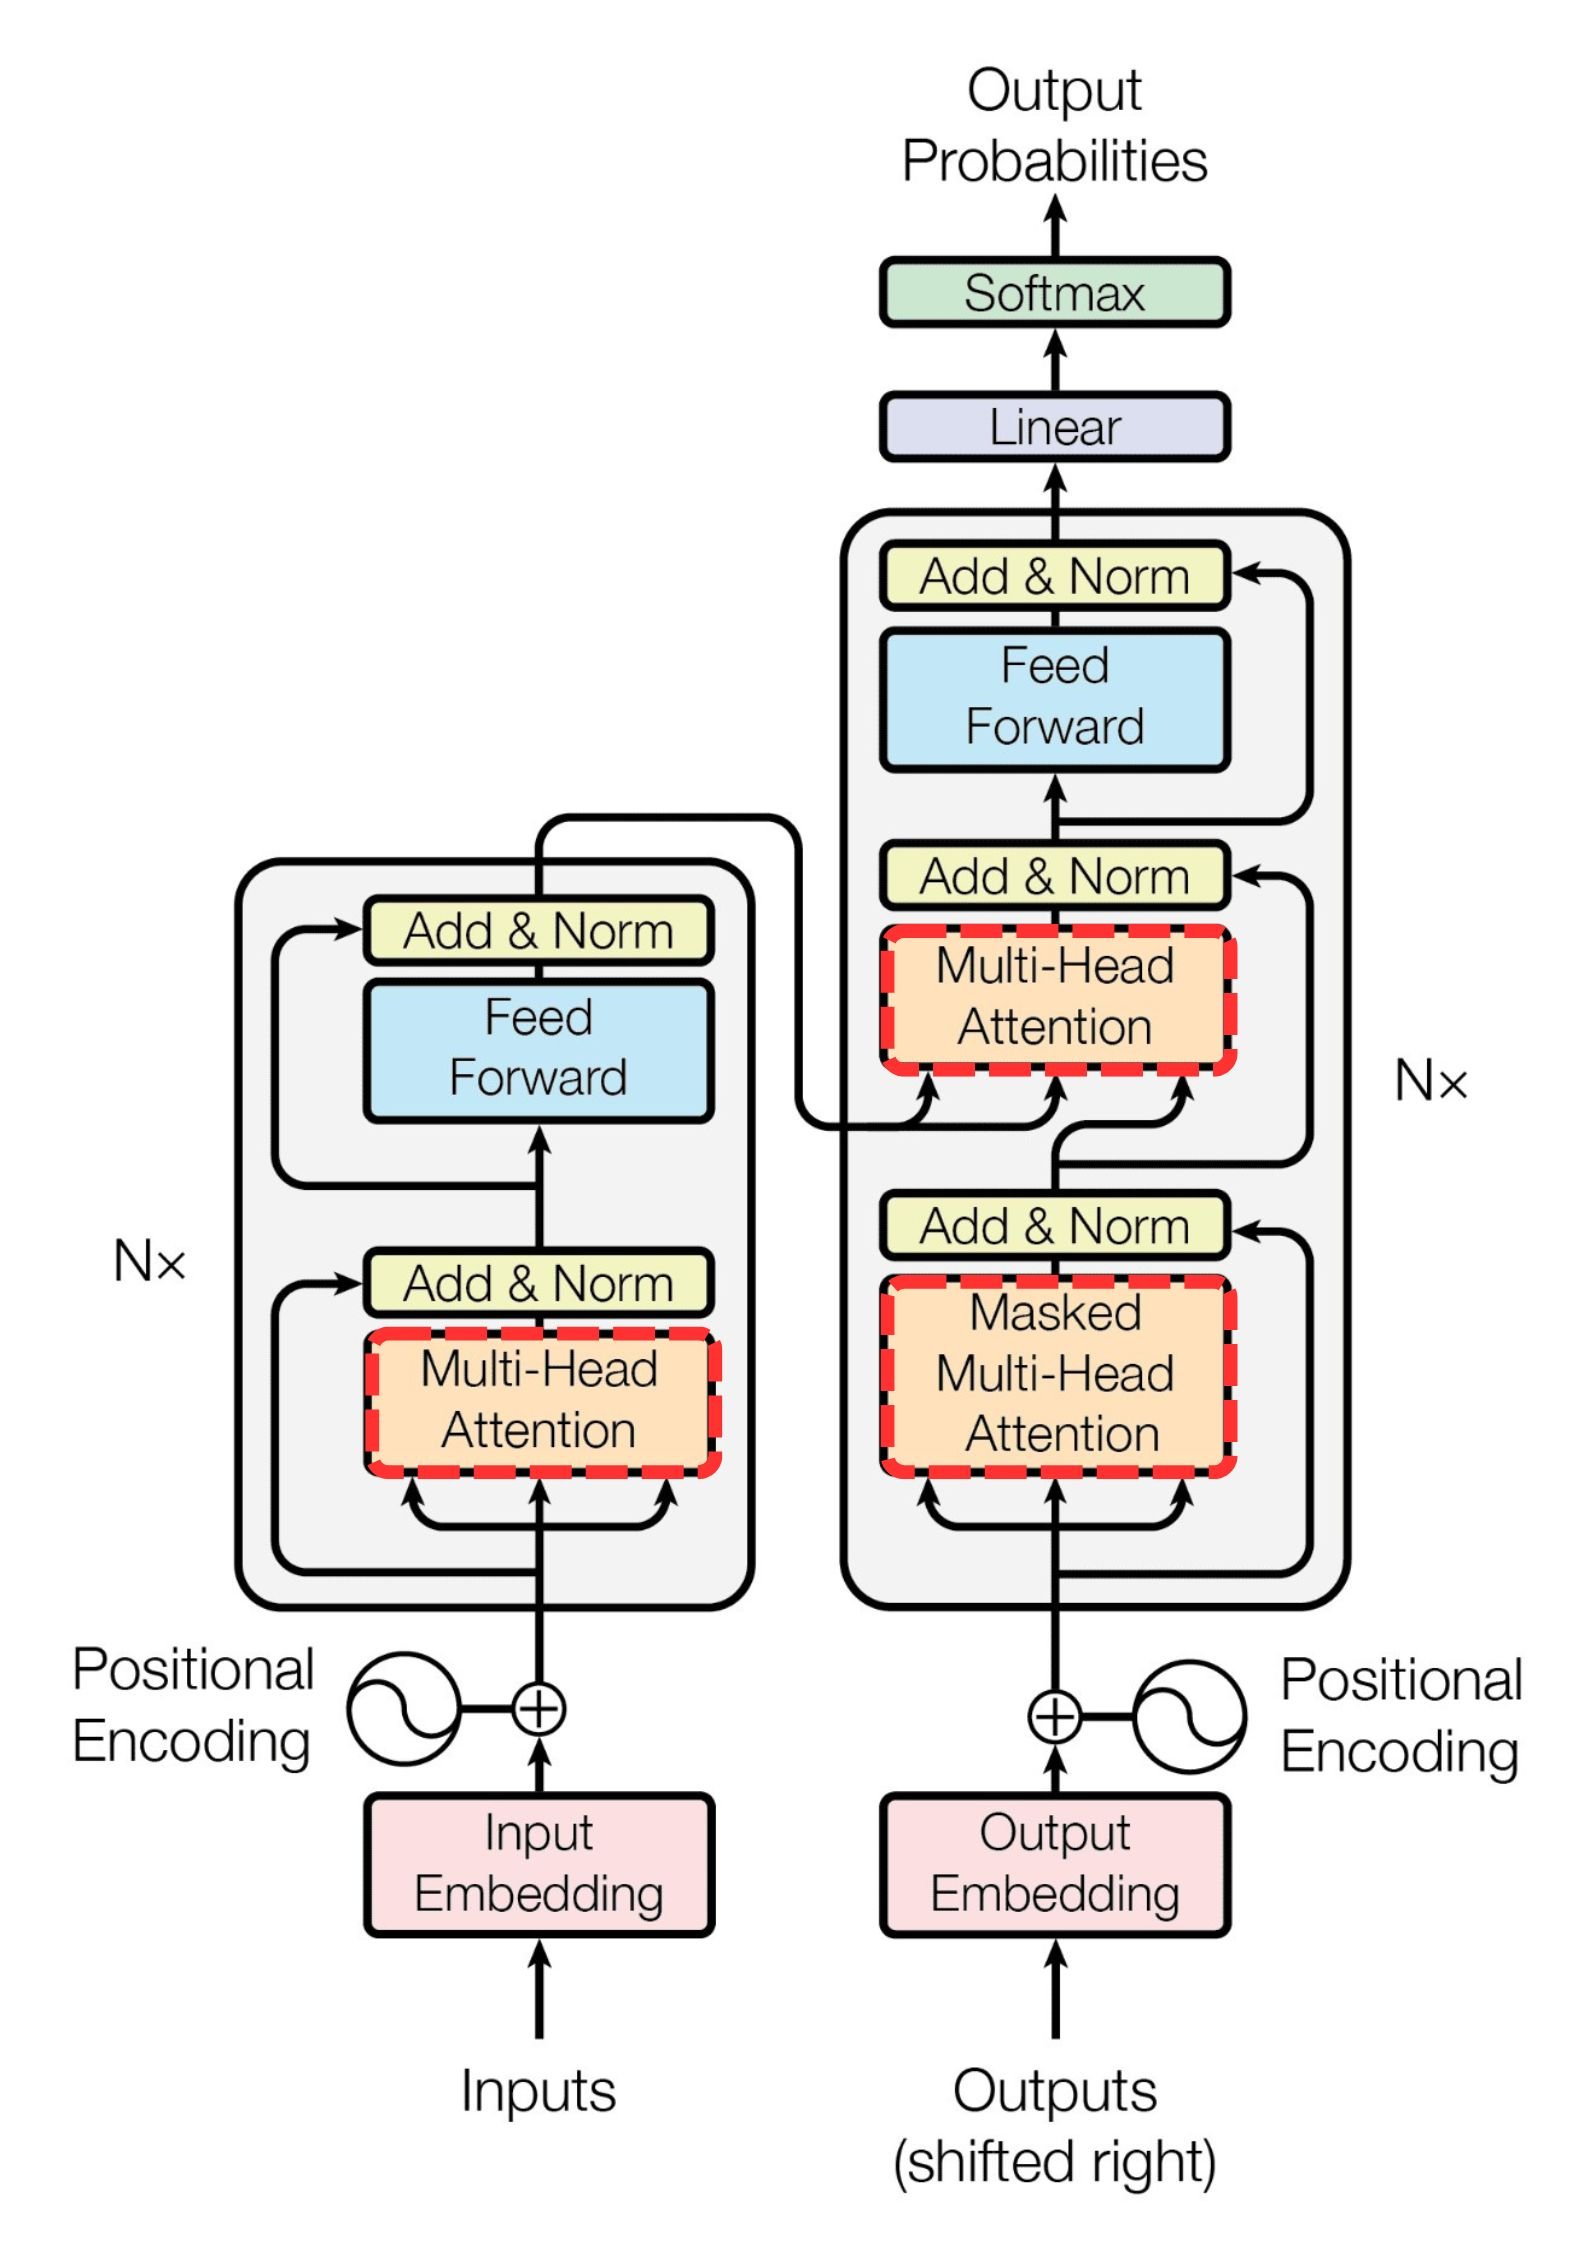
學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

改變一切的論文…


  • Ashish Vaswani 等人所著的 Attention Is All You Need
    • 注意力機制
    • 為文字建模最佳化
    • 應用於 大型語言模型(LLMs)

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

改變一切的論文…


  • Ashish Vaswani 等人所著的 Attention Is All You Need
    • 注意力機制
    • 為文字建模最佳化
    • 應用於 大型語言模型(LLMs)

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…


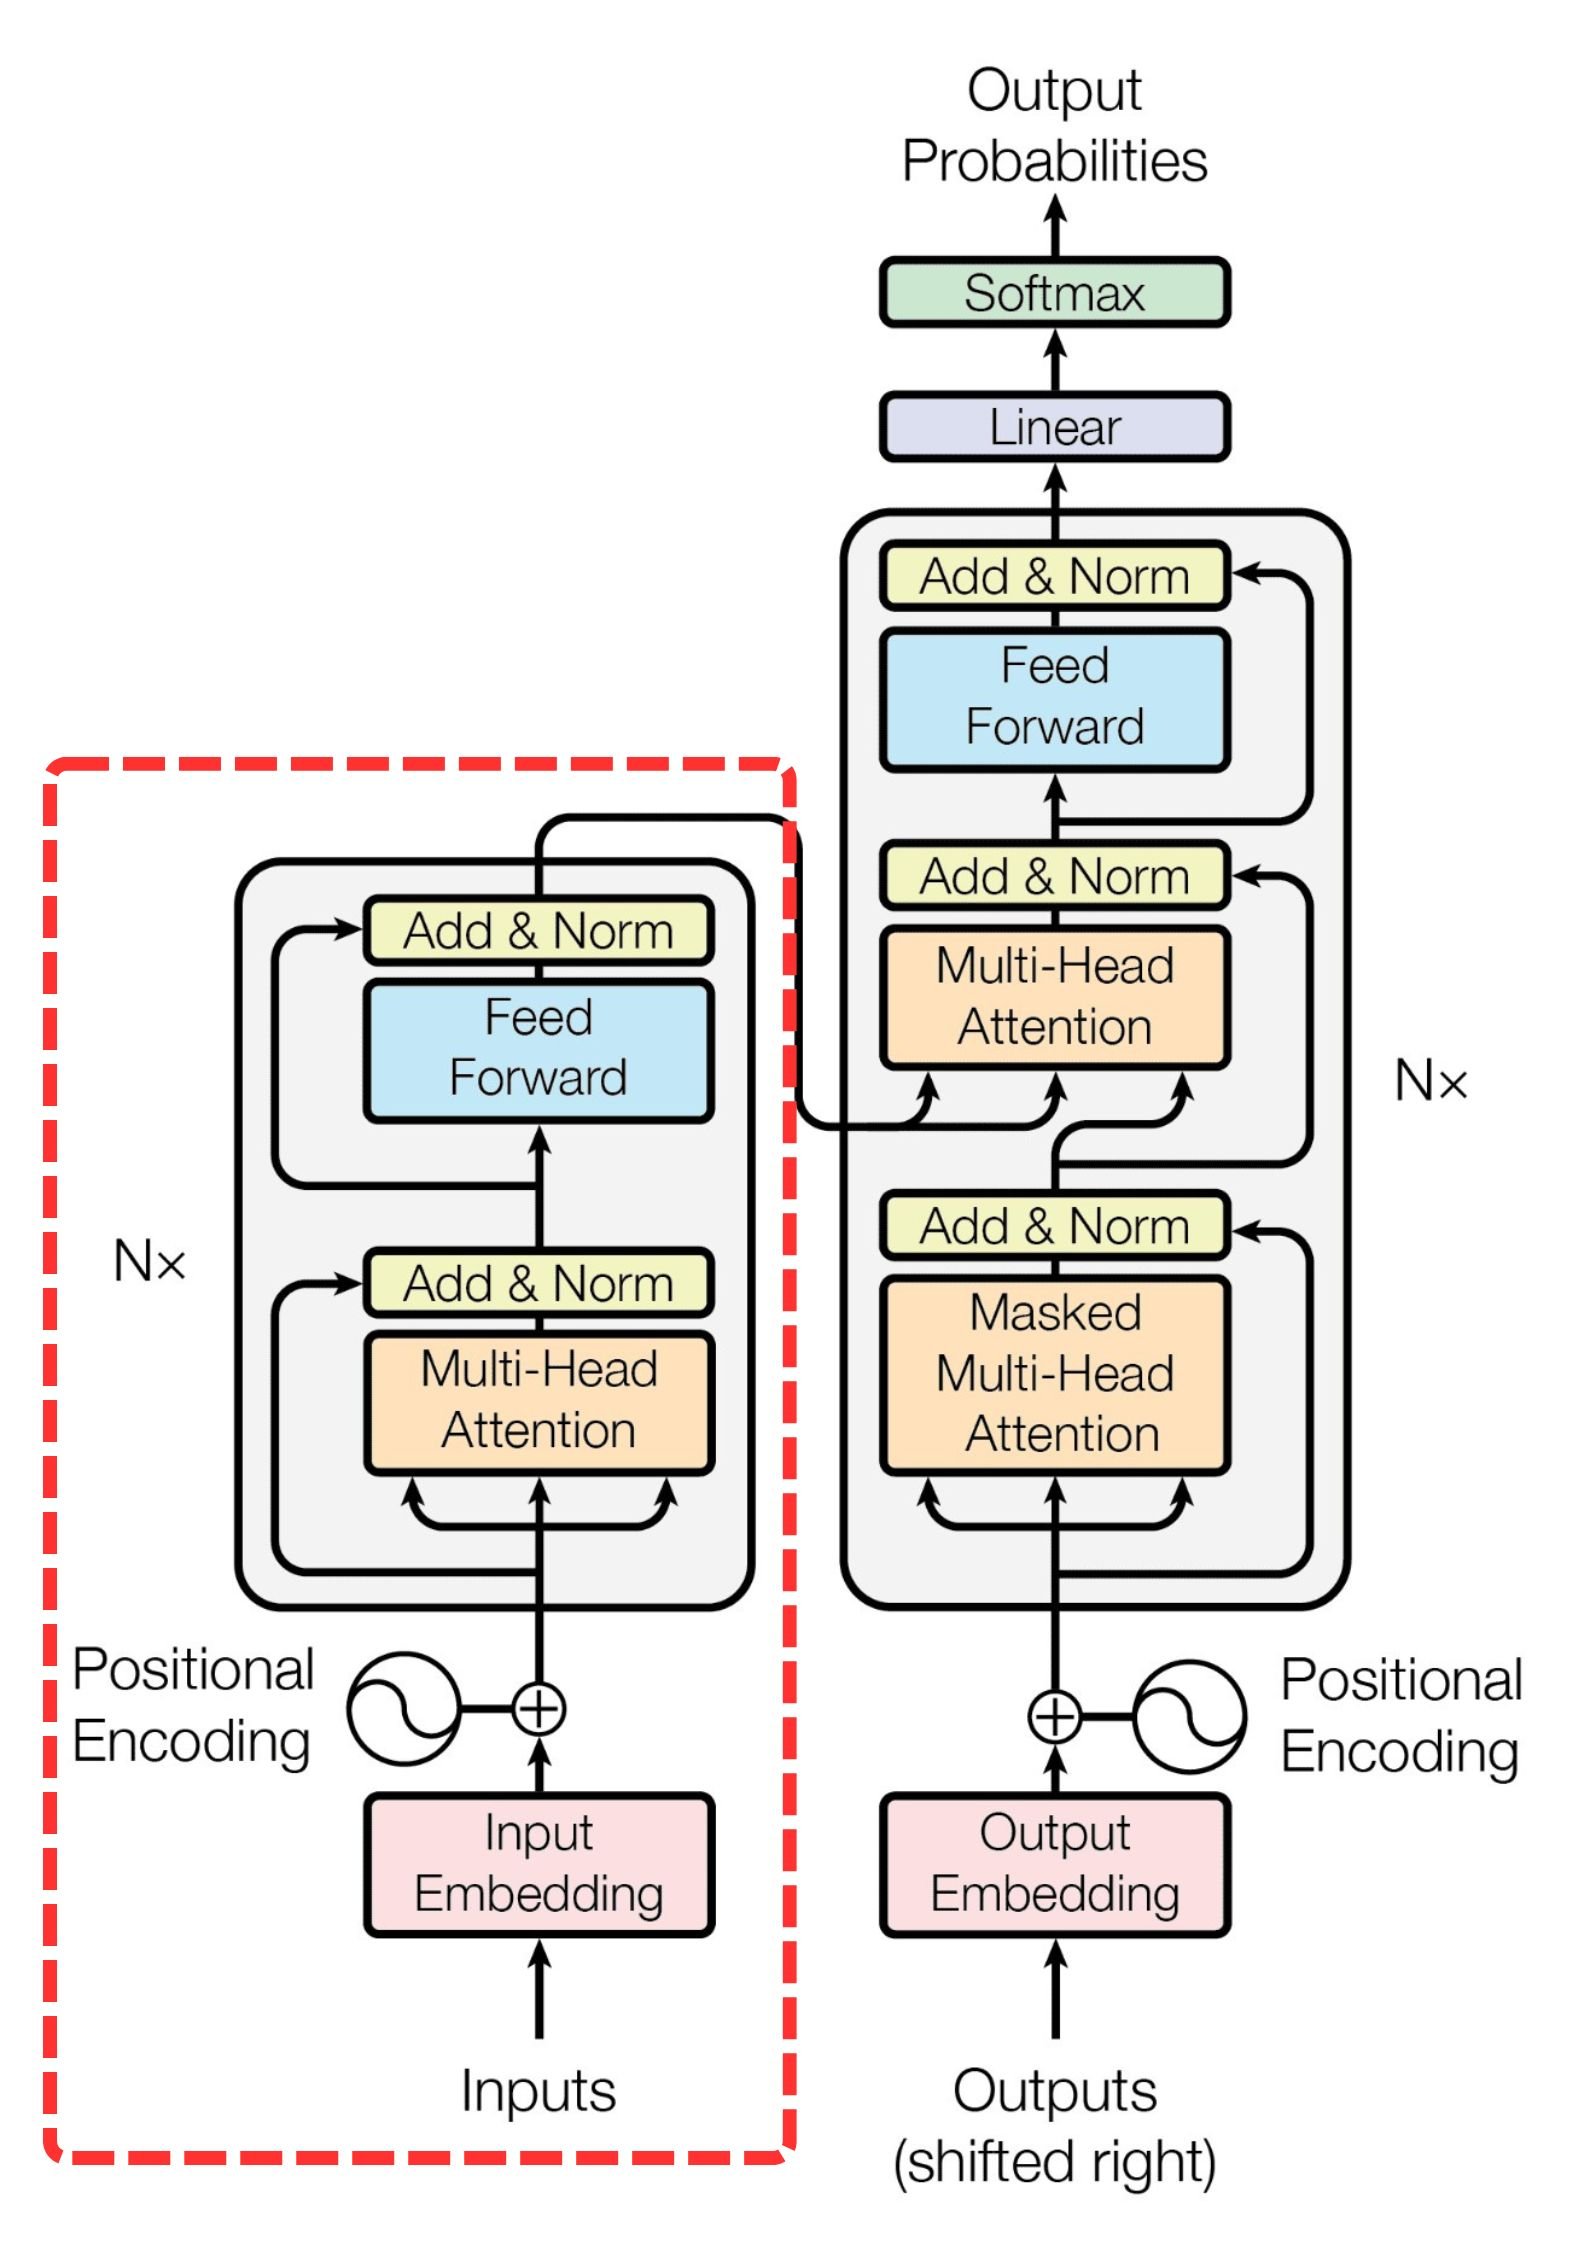
編碼器區塊
  • 多個相同層
  • 讀取處理輸入序列
  • 產生具脈絡的數值表示
  • 使用 self-attentionfeed-forward networks

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…


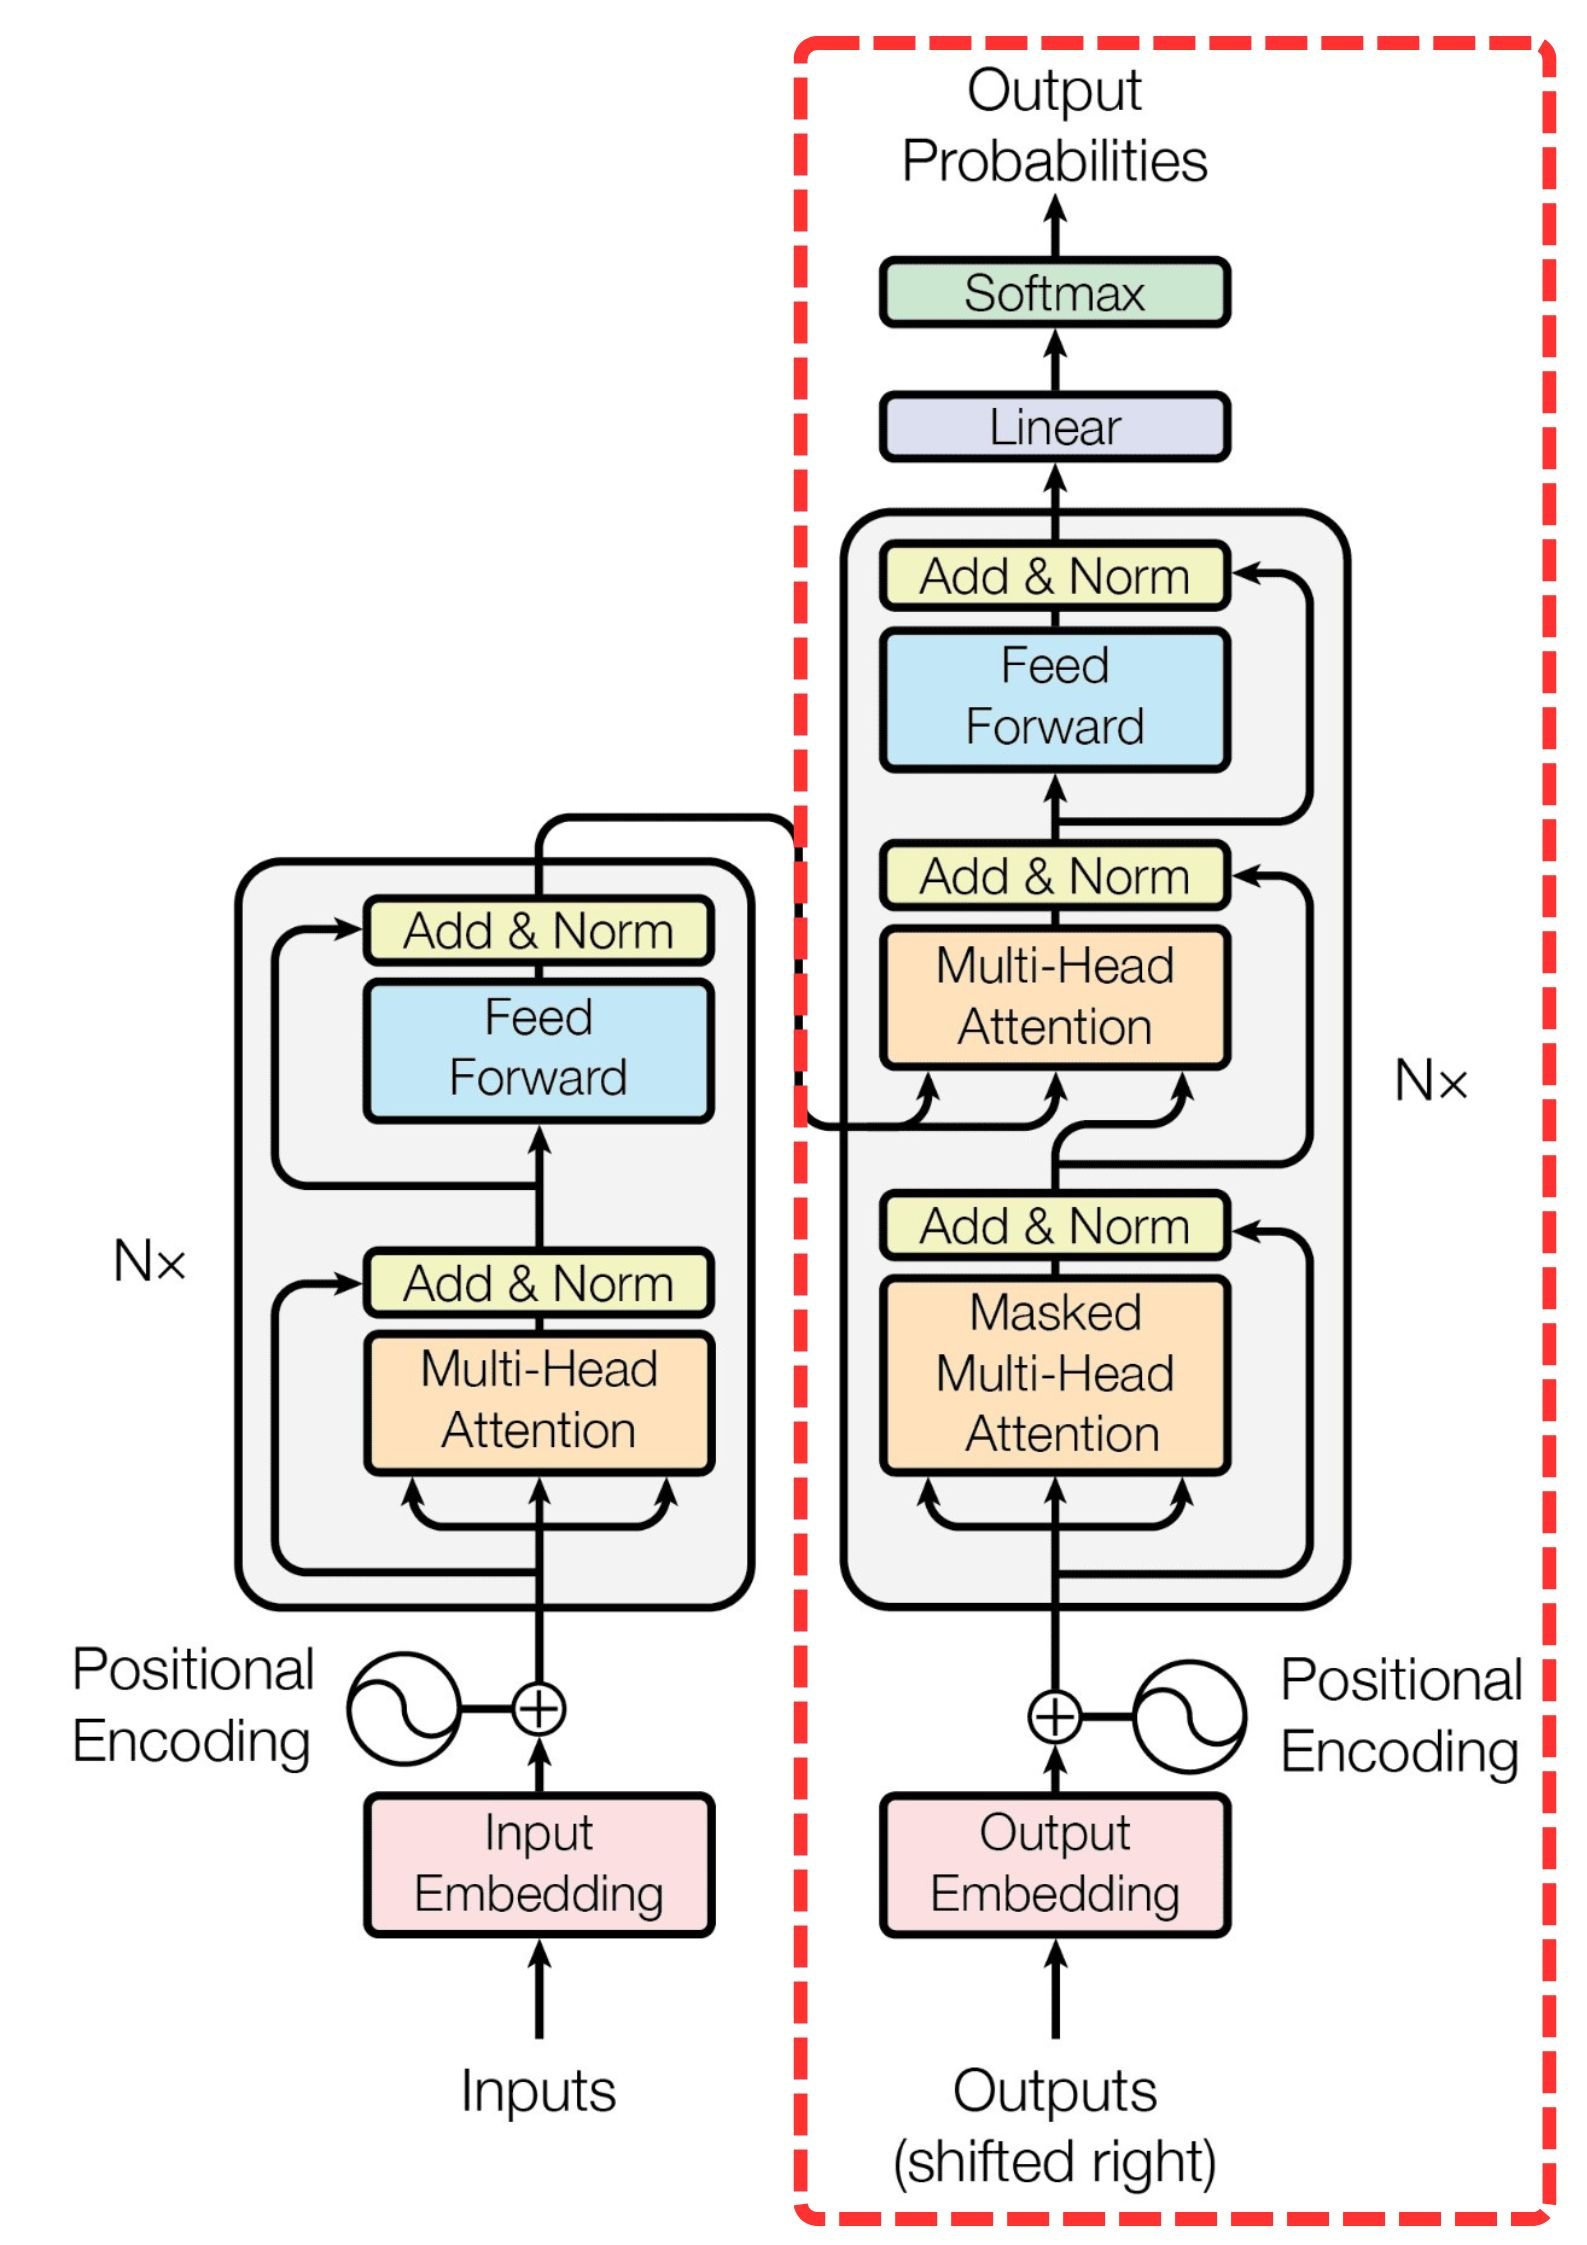
解碼器區塊
  • 將已編碼的輸入序列 → 輸出序列

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…


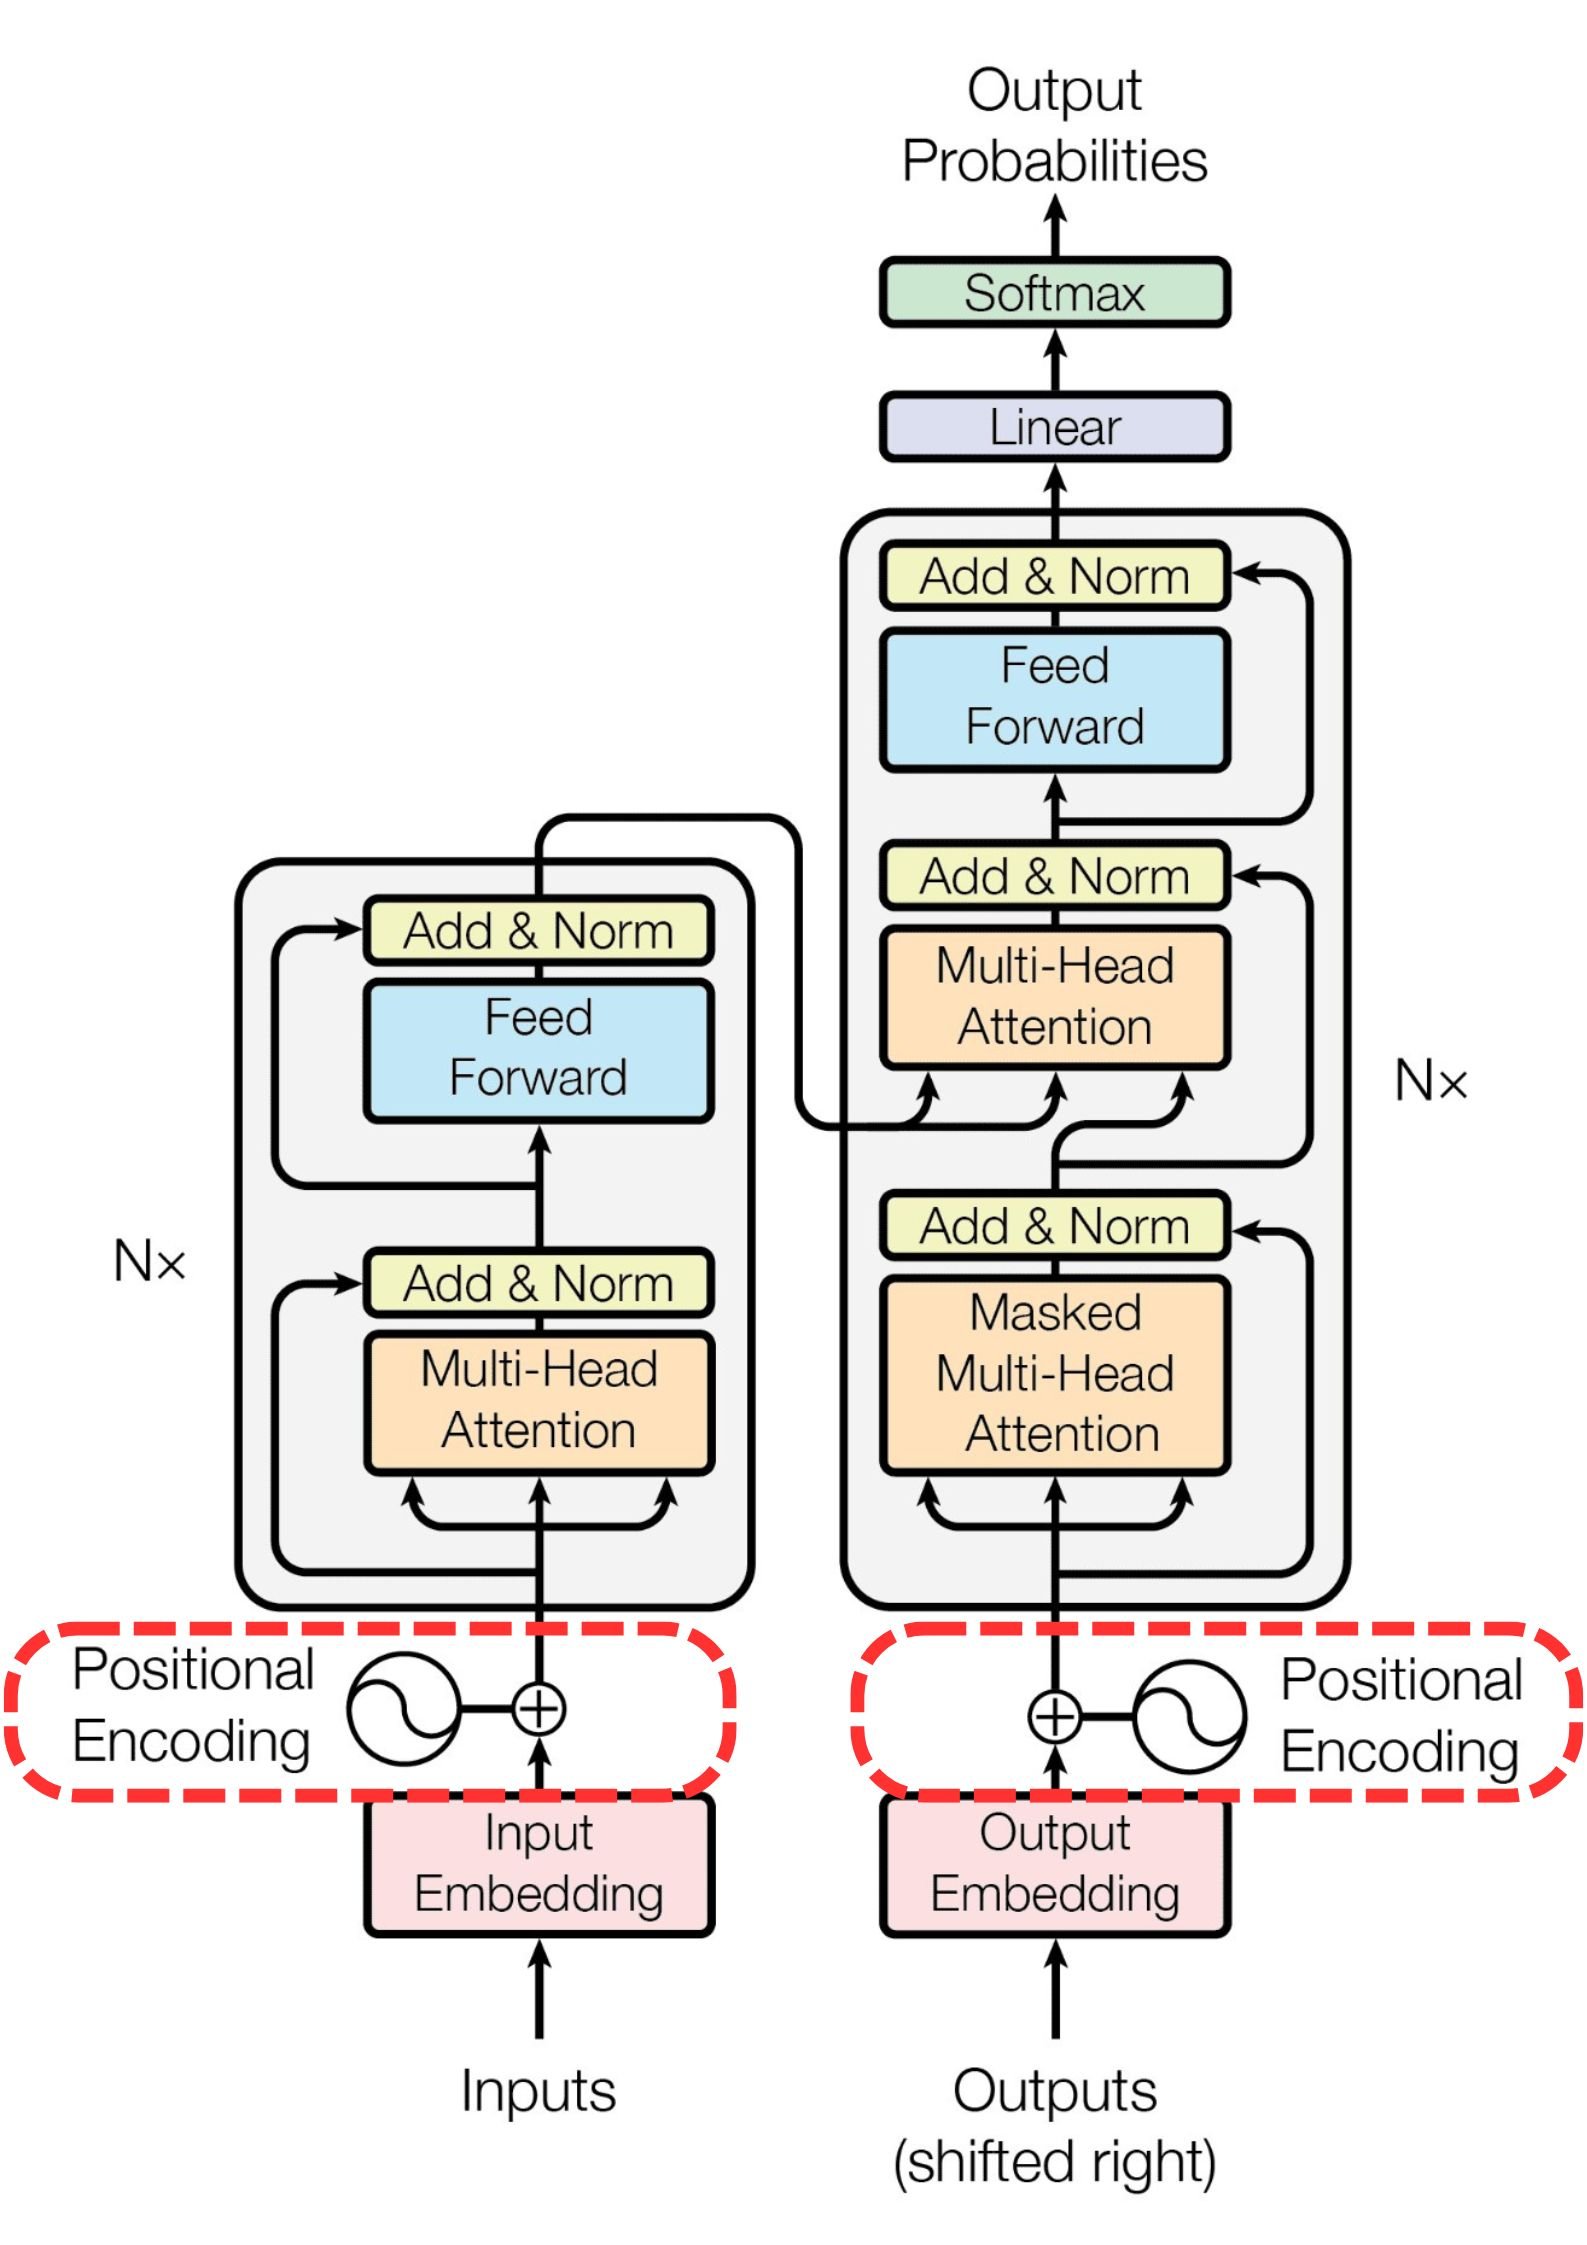
位置編碼(Positional encoding)
  • 為序列中每個 token 編碼其「位置」
  • 序順對序列建模至關重要

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…

注意力機制
  • 聚焦關鍵 token 及其關係
  • 提升文字生成

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…

注意力機制
  • 聚焦關鍵 token 及其關係
  • 提升文字生成
自注意力(Self-attention)
  • 為 token 重要性加上「權重」
  • 擷取長距依存關係

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…

注意力機制
  • 聚焦關鍵 token 及其關係
  • 提升文字生成
自注意力(Self-attention)
  • 為 token 重要性加上權重
  • 擷取長距依存關係
多頭注意力(Multi-head attention)
  • 將輸入切成多個 head
  • 不同 head 擷取不同模式,表示更豐富

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

逐步拆解 Transformer…


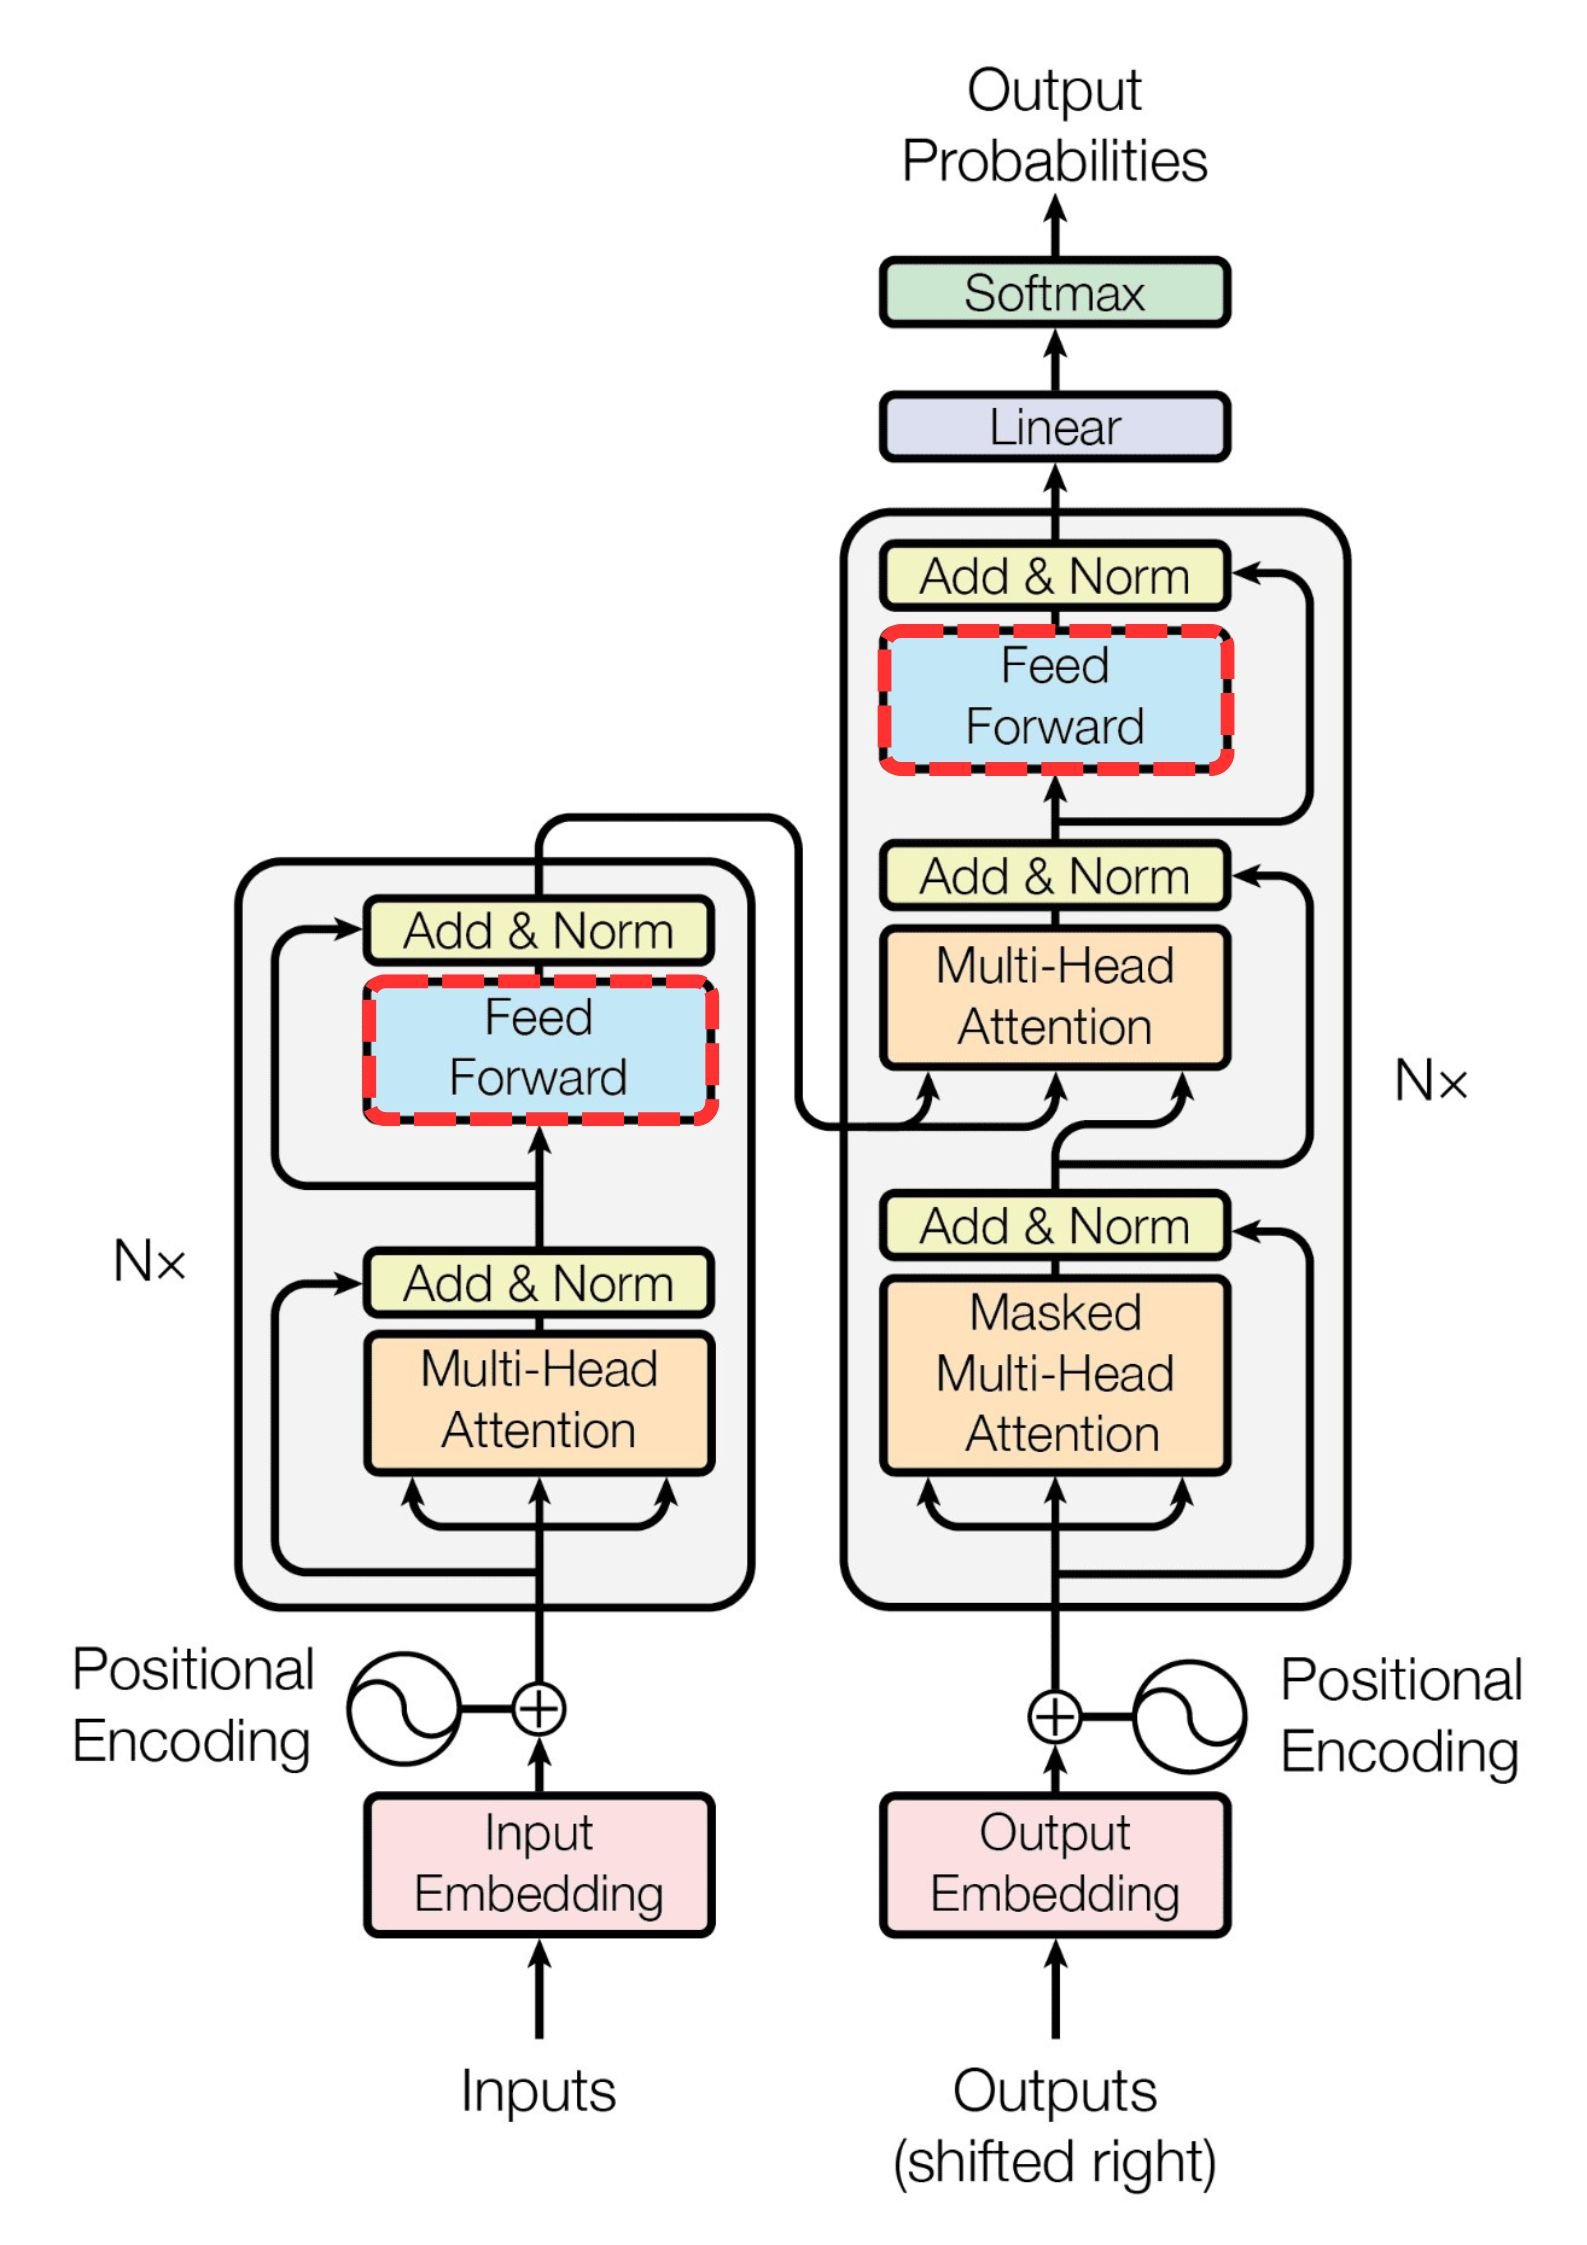
逐位置前饋網路(Position-wise FFN)
  • 簡單的類神經網路,套用轉換
  • 各 token 彼此「獨立」轉換
  • 與位置無關/「逐位置」

學術論文「Attention Is All You Need」中的 Transformer 架構示意。

Transformer Models with PyTorch

PyTorch 中的 Transformer


  • d_model:模型輸入的維度
  • nheads:注意力 head 數
  • num_encoder_layers:編碼器層數
  • num_decoder_layers:解碼器層數
import torch.nn as nn


model = nn.Transformer(
d_model=512,
nhead=8,
num_encoder_layers=6,
num_decoder_layers=6
)
print(model)
Transformer Models with PyTorch
Transformer(
  (encoder): TransformerEncoder(
    (layers): ModuleList(
      (0-5): 6 x TransformerEncoderLayer(
        (self_attn): MultiheadAttention(
          (out_proj): NonDynamicallyQuantizableLinear(in_features=512, out_features=512, bias=True)
        )
        (linear1): Linear(in_features=512, out_features=2048, bias=True)
        (dropout): Dropout(p=0.1, inplace=False)
        (linear2): Linear(in_features=2048, out_features=512, bias=True)
        (norm1): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
        (norm2): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
        (dropout1): Dropout(p=0.1, inplace=False)
        (dropout2): Dropout(p=0.1, inplace=False)
      )
    )
    (norm): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
  )
  ...
Transformer Models with PyTorch
  (decoder): TransformerDecoder(
    (layers): ModuleList(
      (0-5): 6 x TransformerDecoderLayer(
        (self_attn): MultiheadAttention(
          (out_proj): NonDynamicallyQuantizableLinear(in_features=512, out_features=512, bias=True)
        )
        (multihead_attn): MultiheadAttention(
          (out_proj): NonDynamicallyQuantizableLinear(in_features=512, out_features=512, bias=True)
        )
        (linear1): Linear(in_features=512, out_features=2048, bias=True)
        (dropout): Dropout(p=0.1, inplace=False)
        (linear2): Linear(in_features=2048, out_features=512, bias=True)
        (norm1): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
        (norm2): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
        (norm3): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
        (dropout1): Dropout(p=0.1, inplace=False)
        (dropout2): Dropout(p=0.1, inplace=False)
        (dropout3): Dropout(p=0.1, inplace=False)
      )
    )
    (norm): LayerNorm((512,), eps=1e-05, elementwise_affine=True)
  )
)
Transformer Models with PyTorch

一起來練習吧!

Transformer Models with PyTorch

Preparing Video For Download...