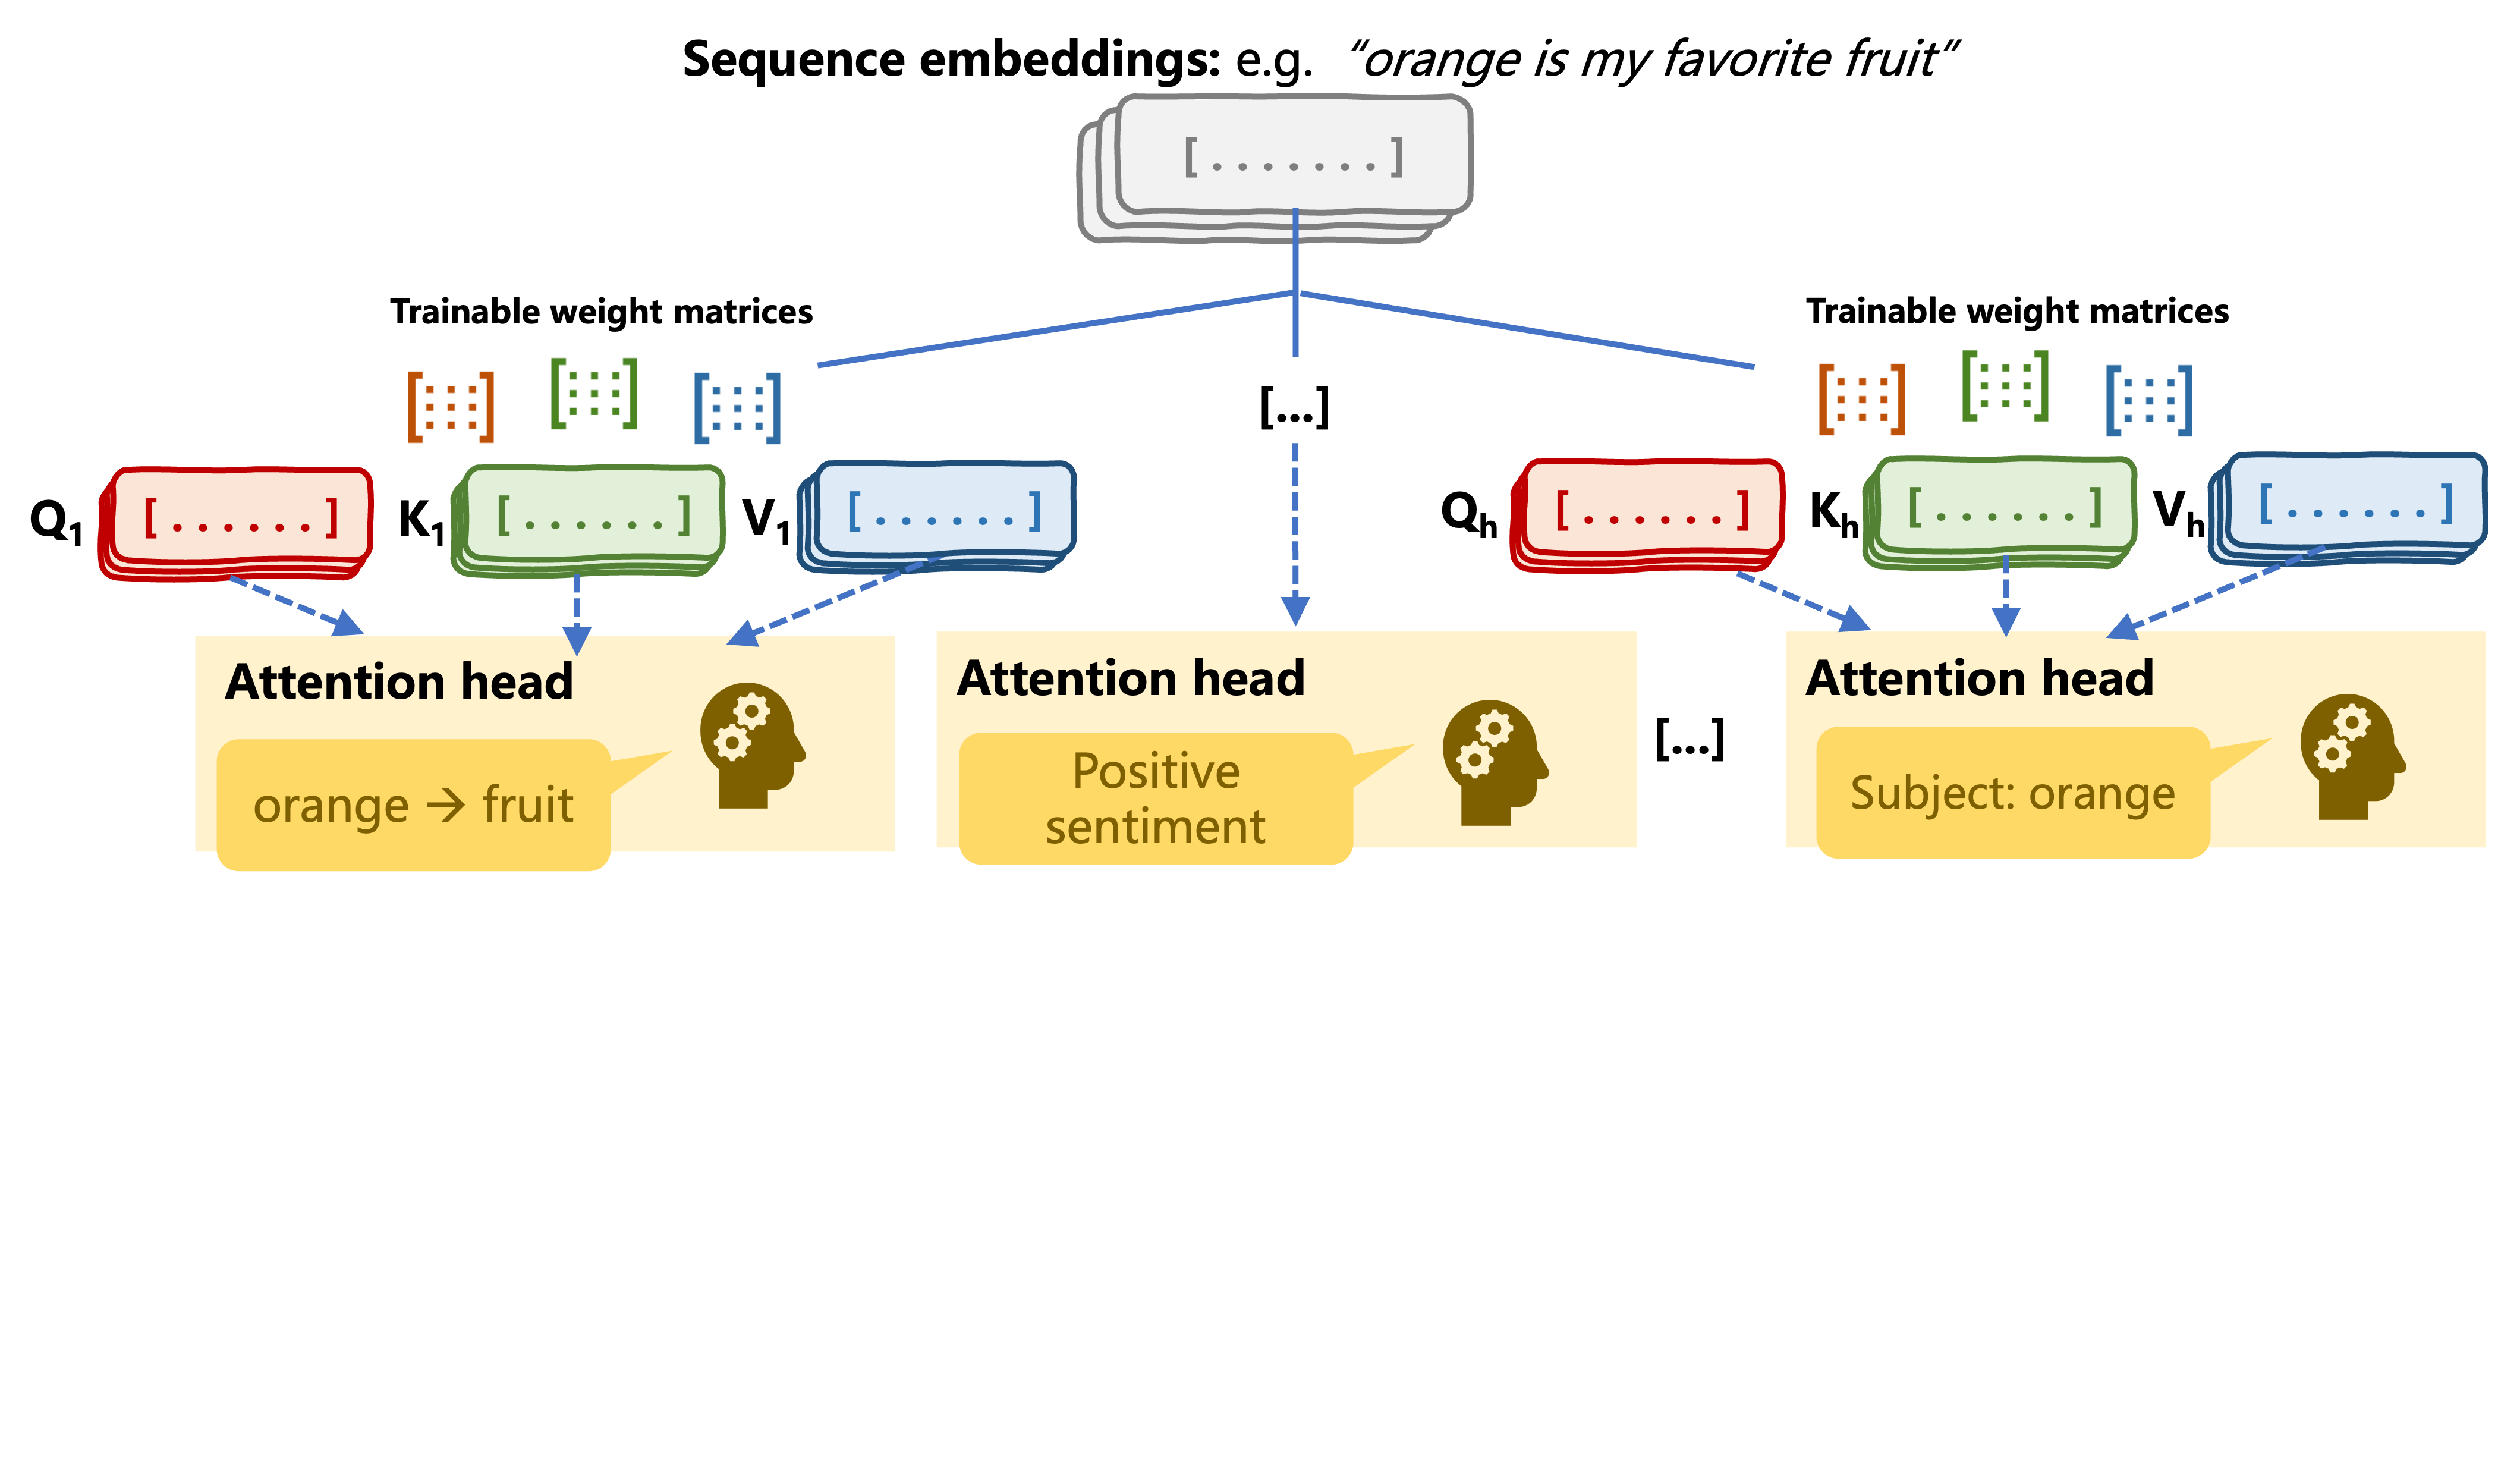
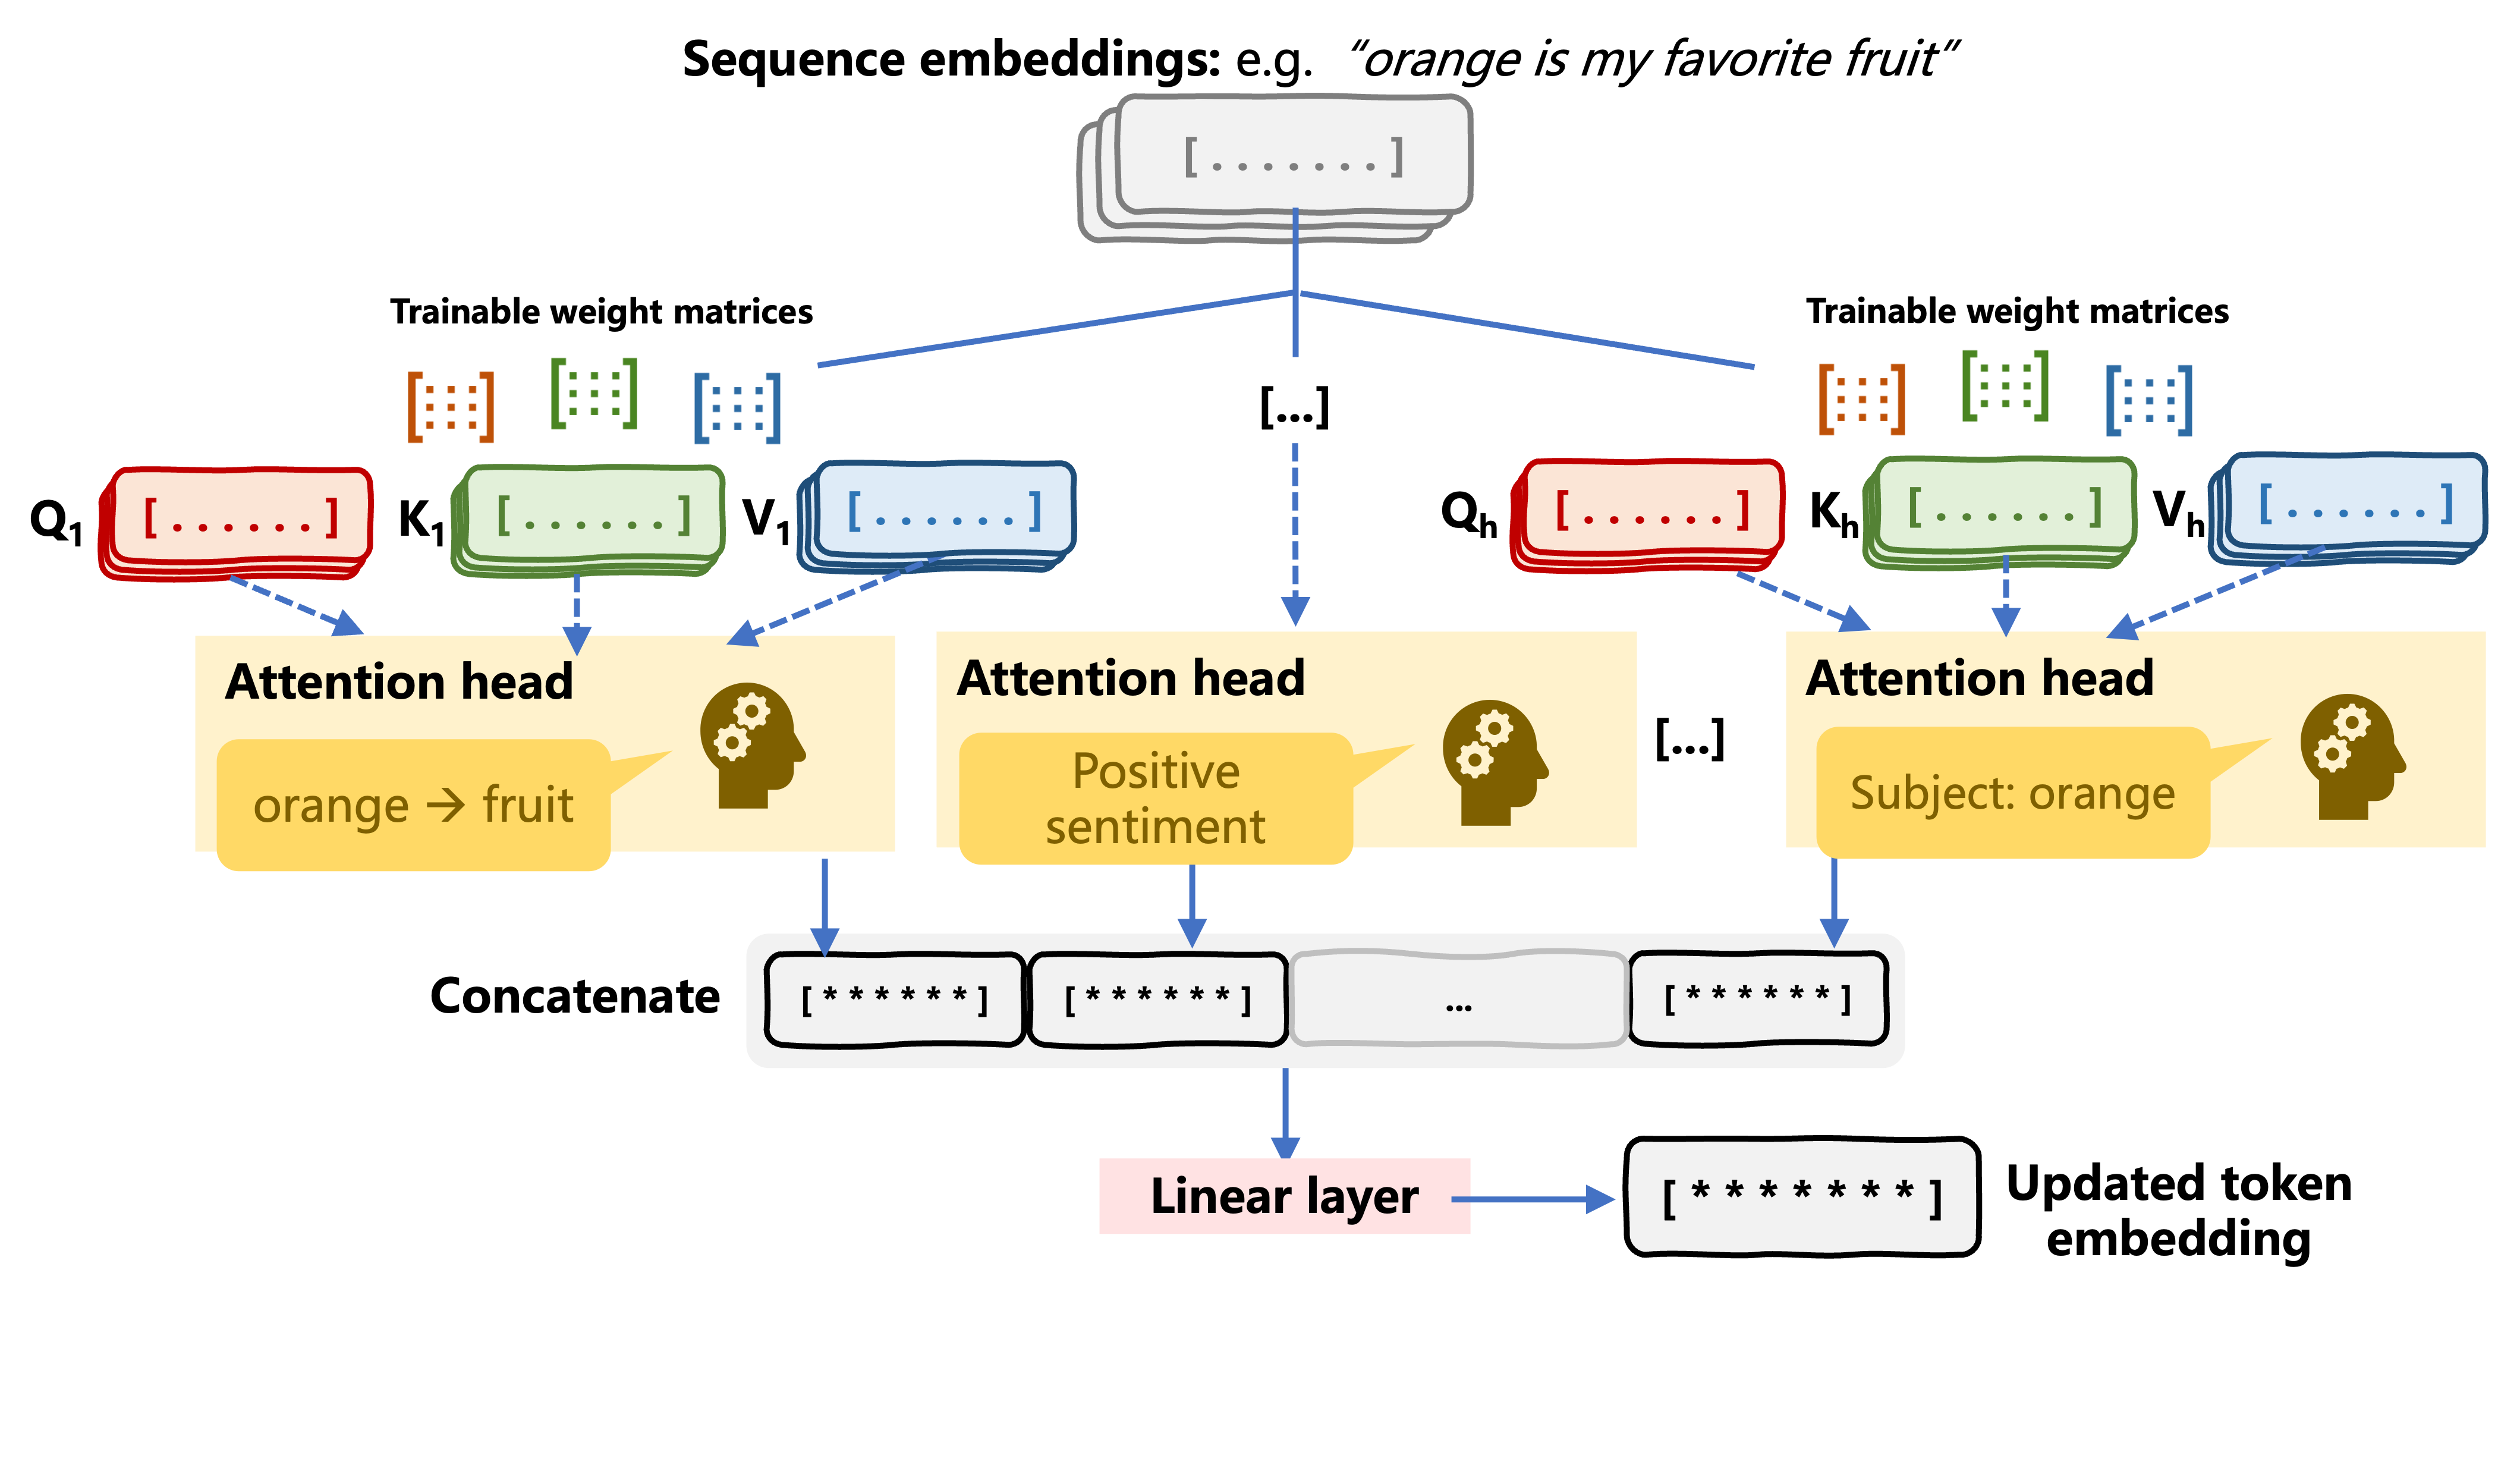
多頭自注意力

Transformer Models with PyTorch

James Chapman

Curriculum Manager, DataCamp

Transformer 的多頭注意力

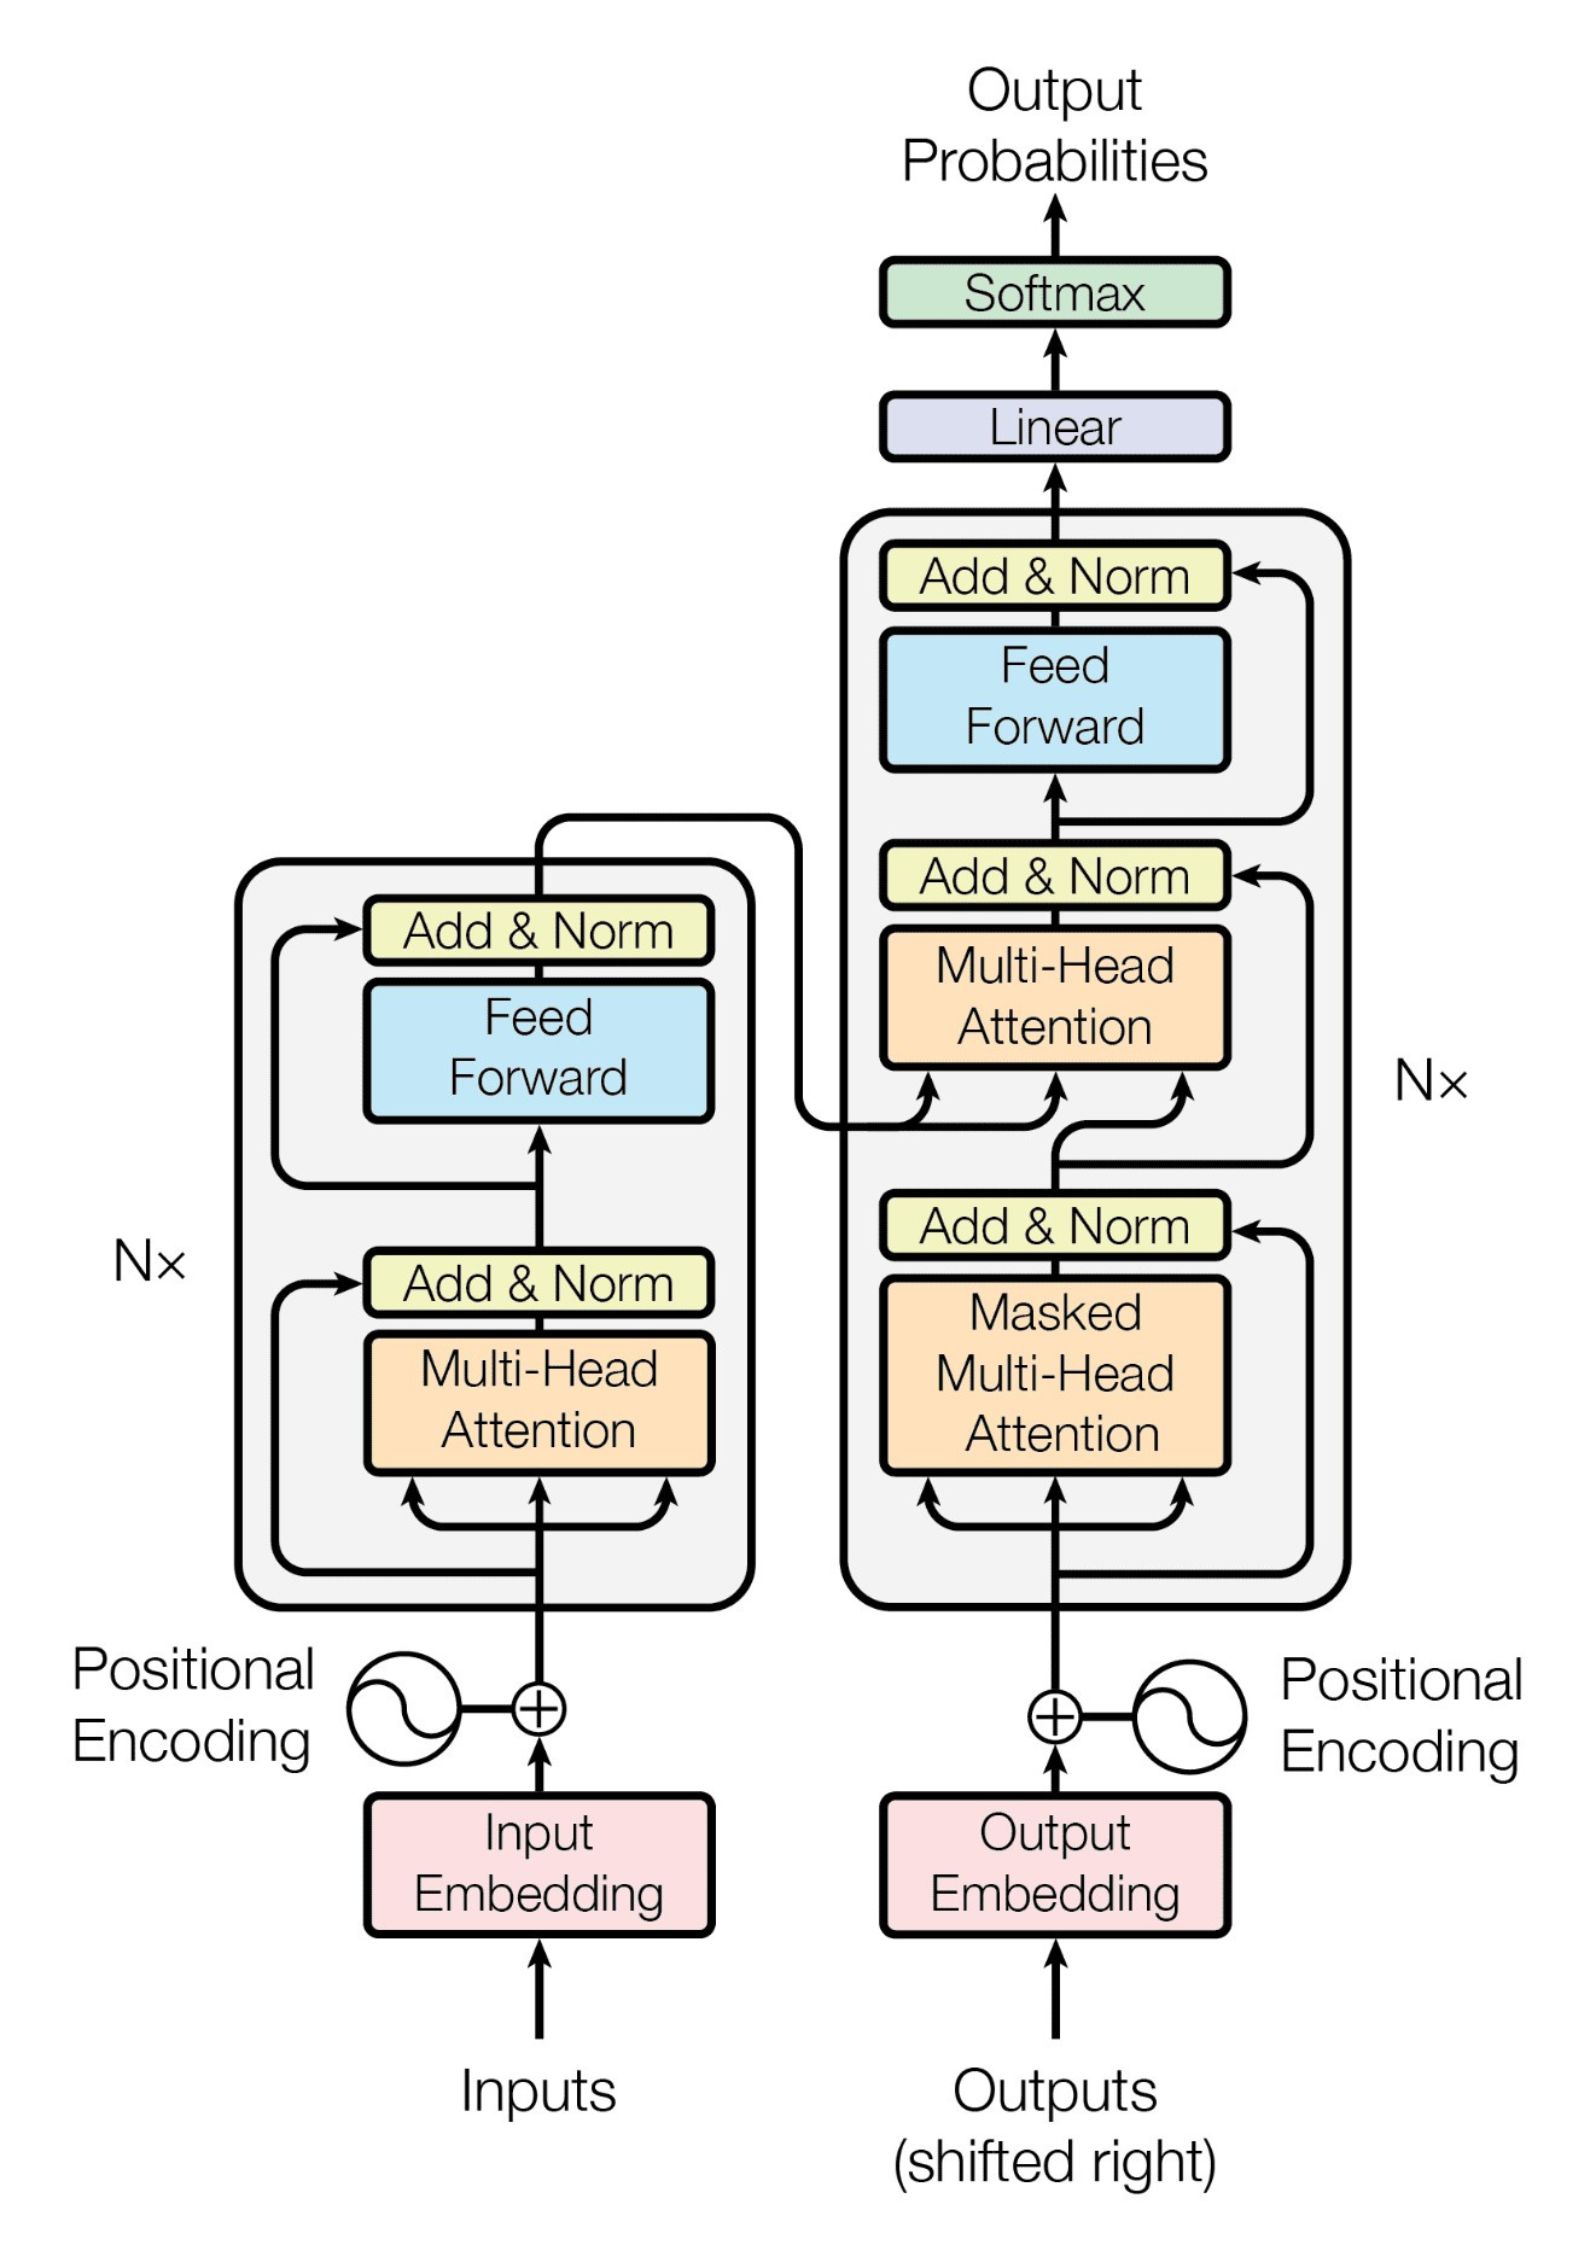
論文「Attention Is All You Need」中的 transformer 架構。

Transformer Models with PyTorch

自注意力機制

自注意力機制剖析

Transformer Models with PyTorch

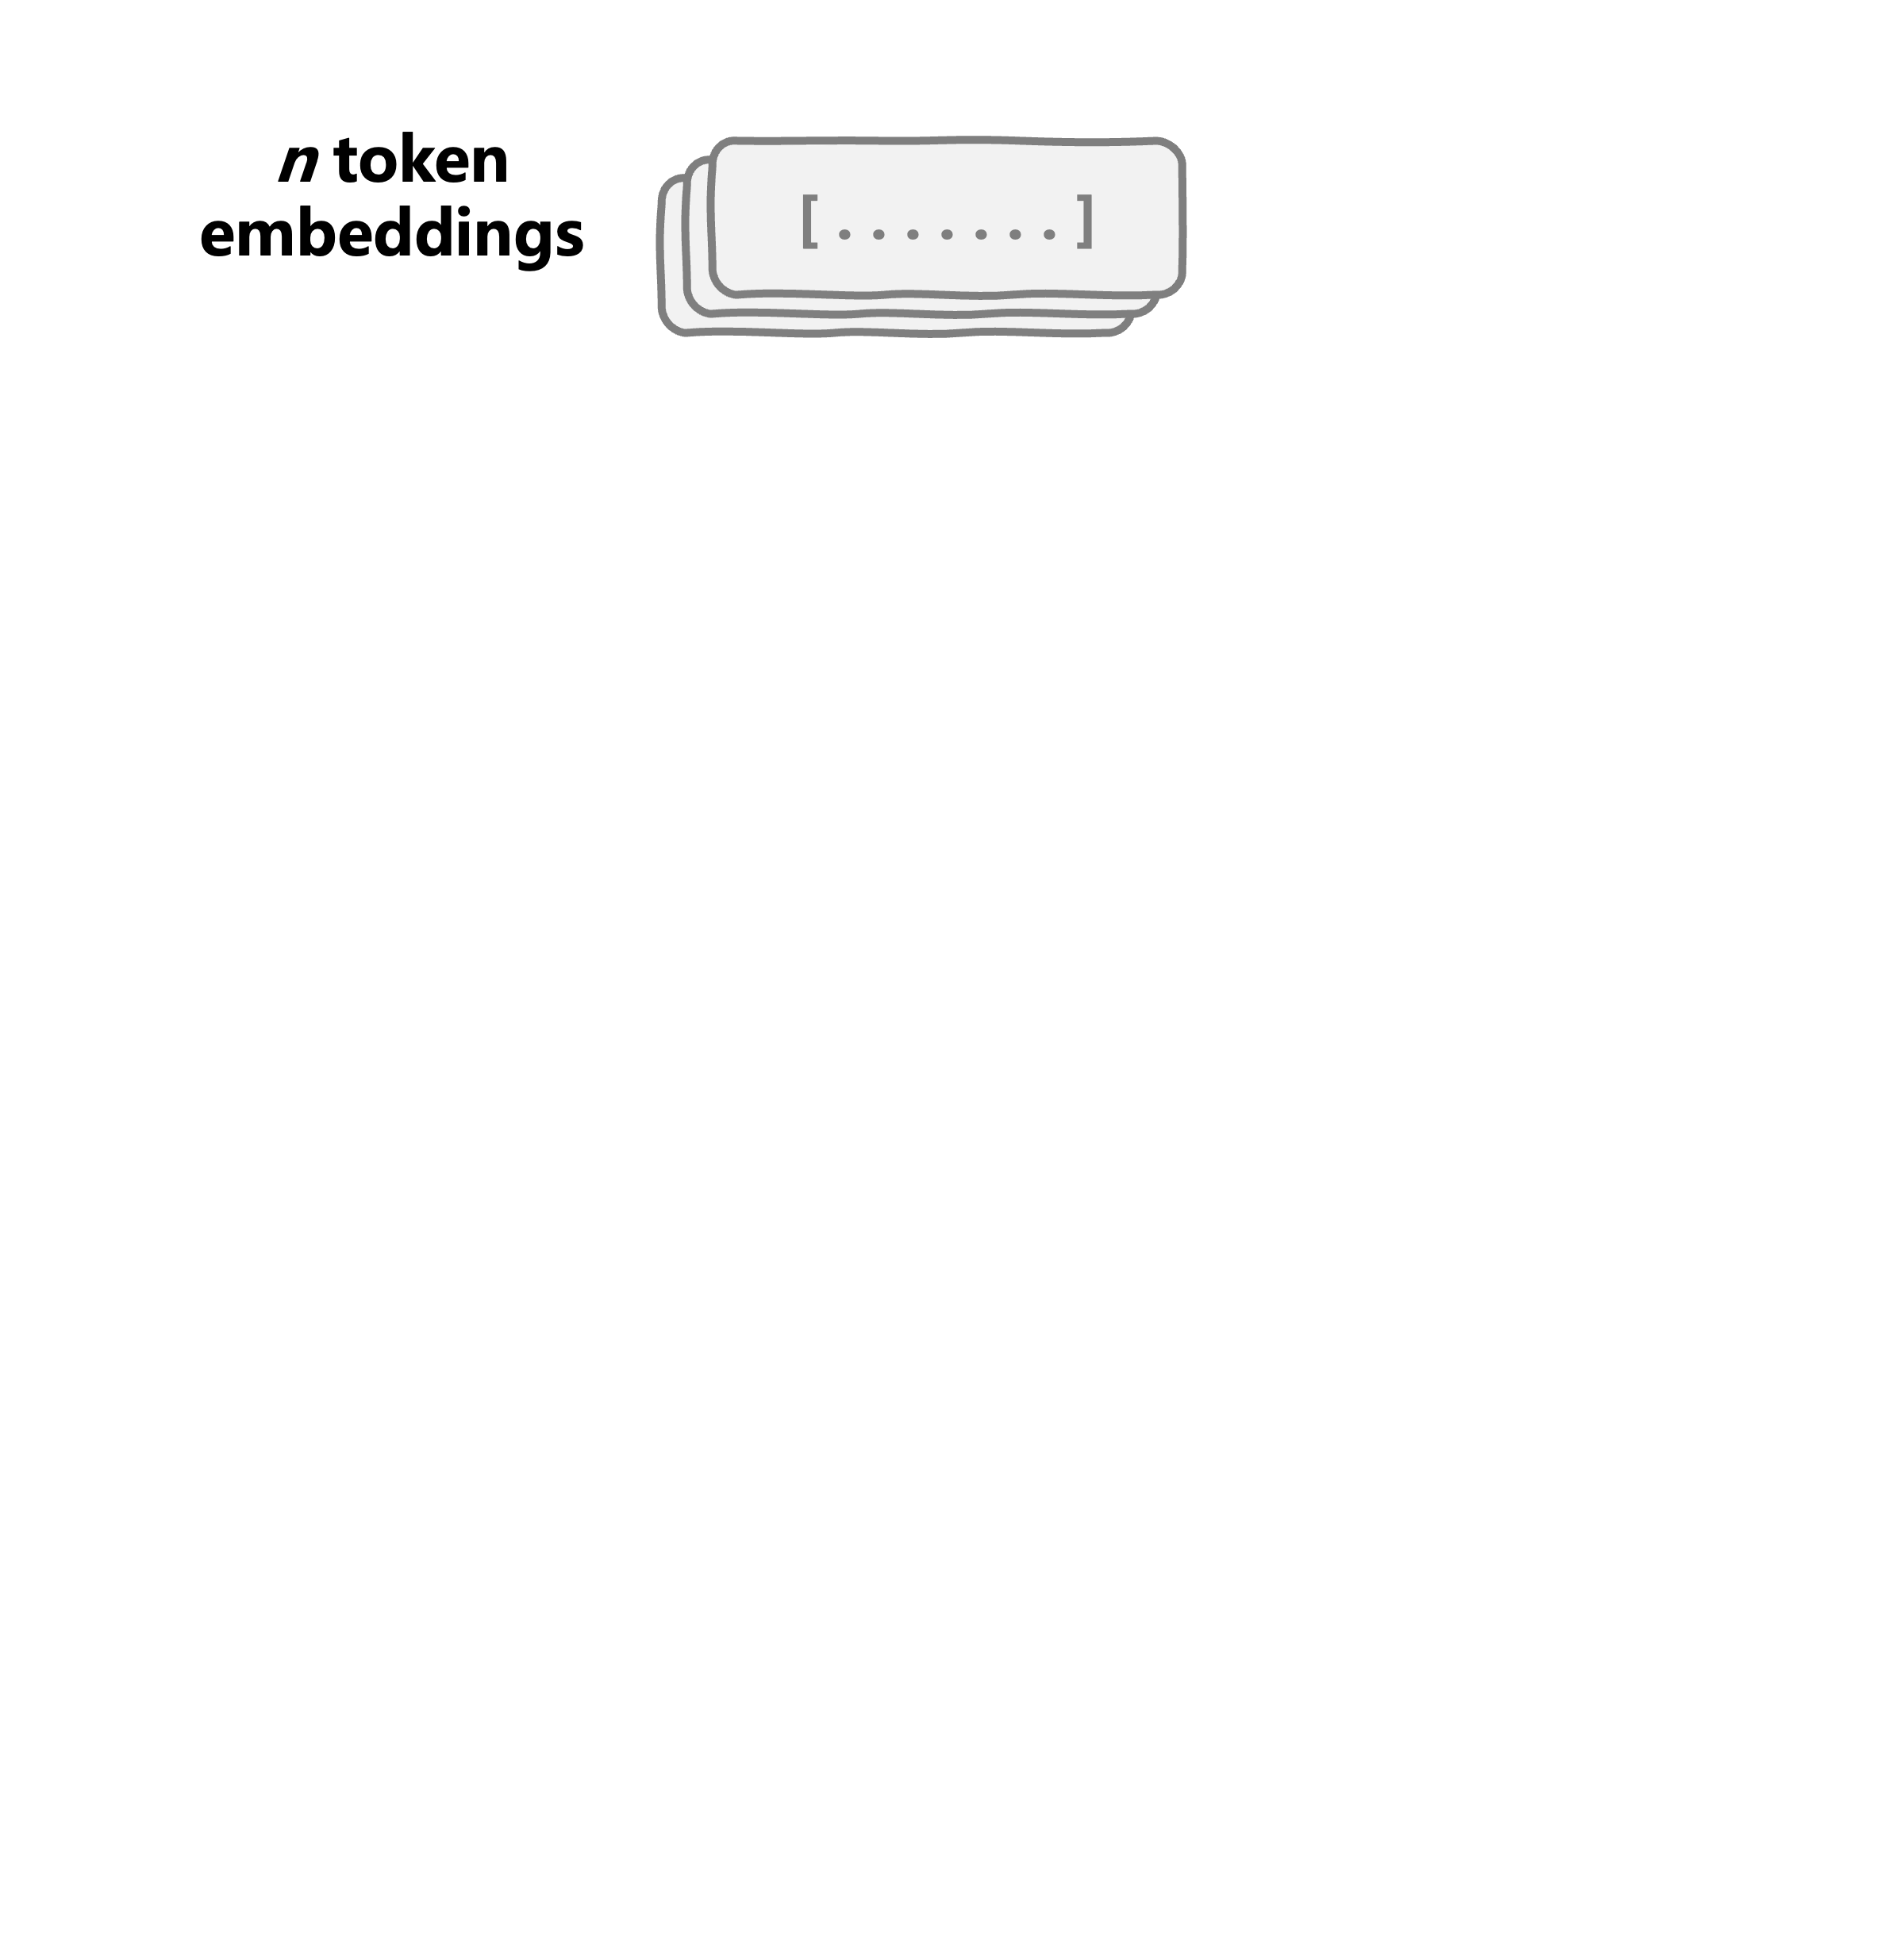
自注意力機制

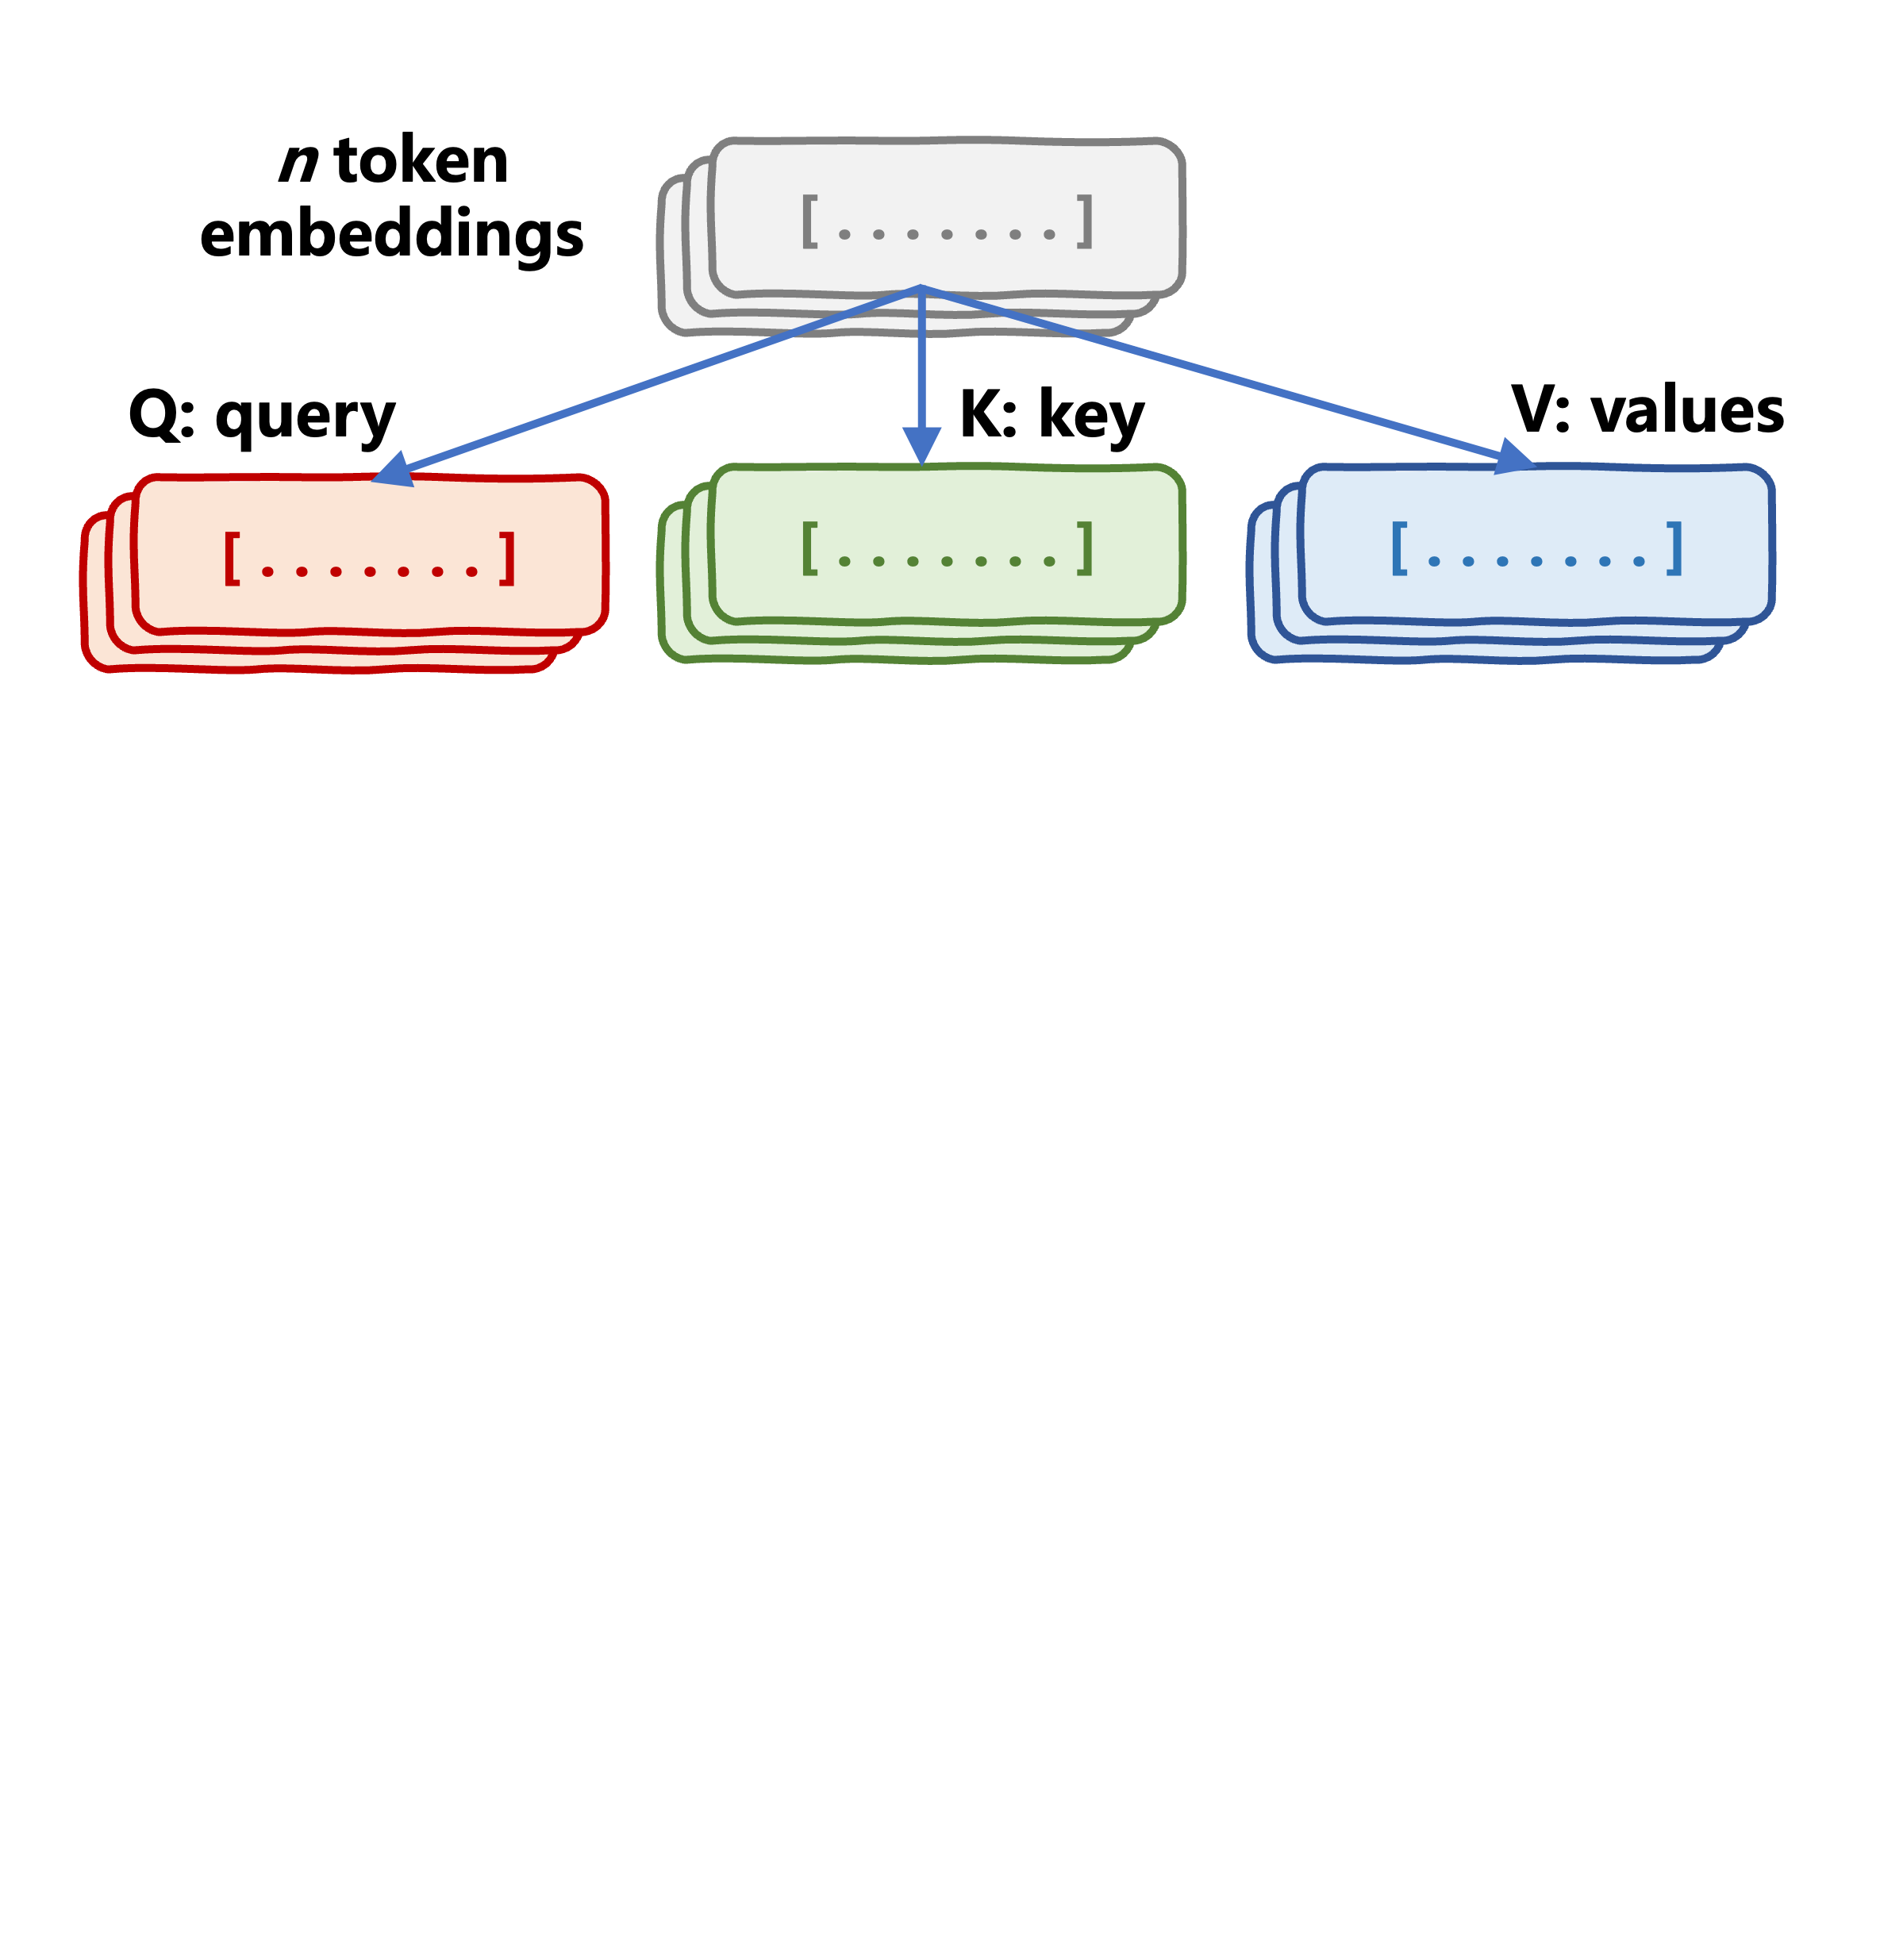
自注意力機制剖析

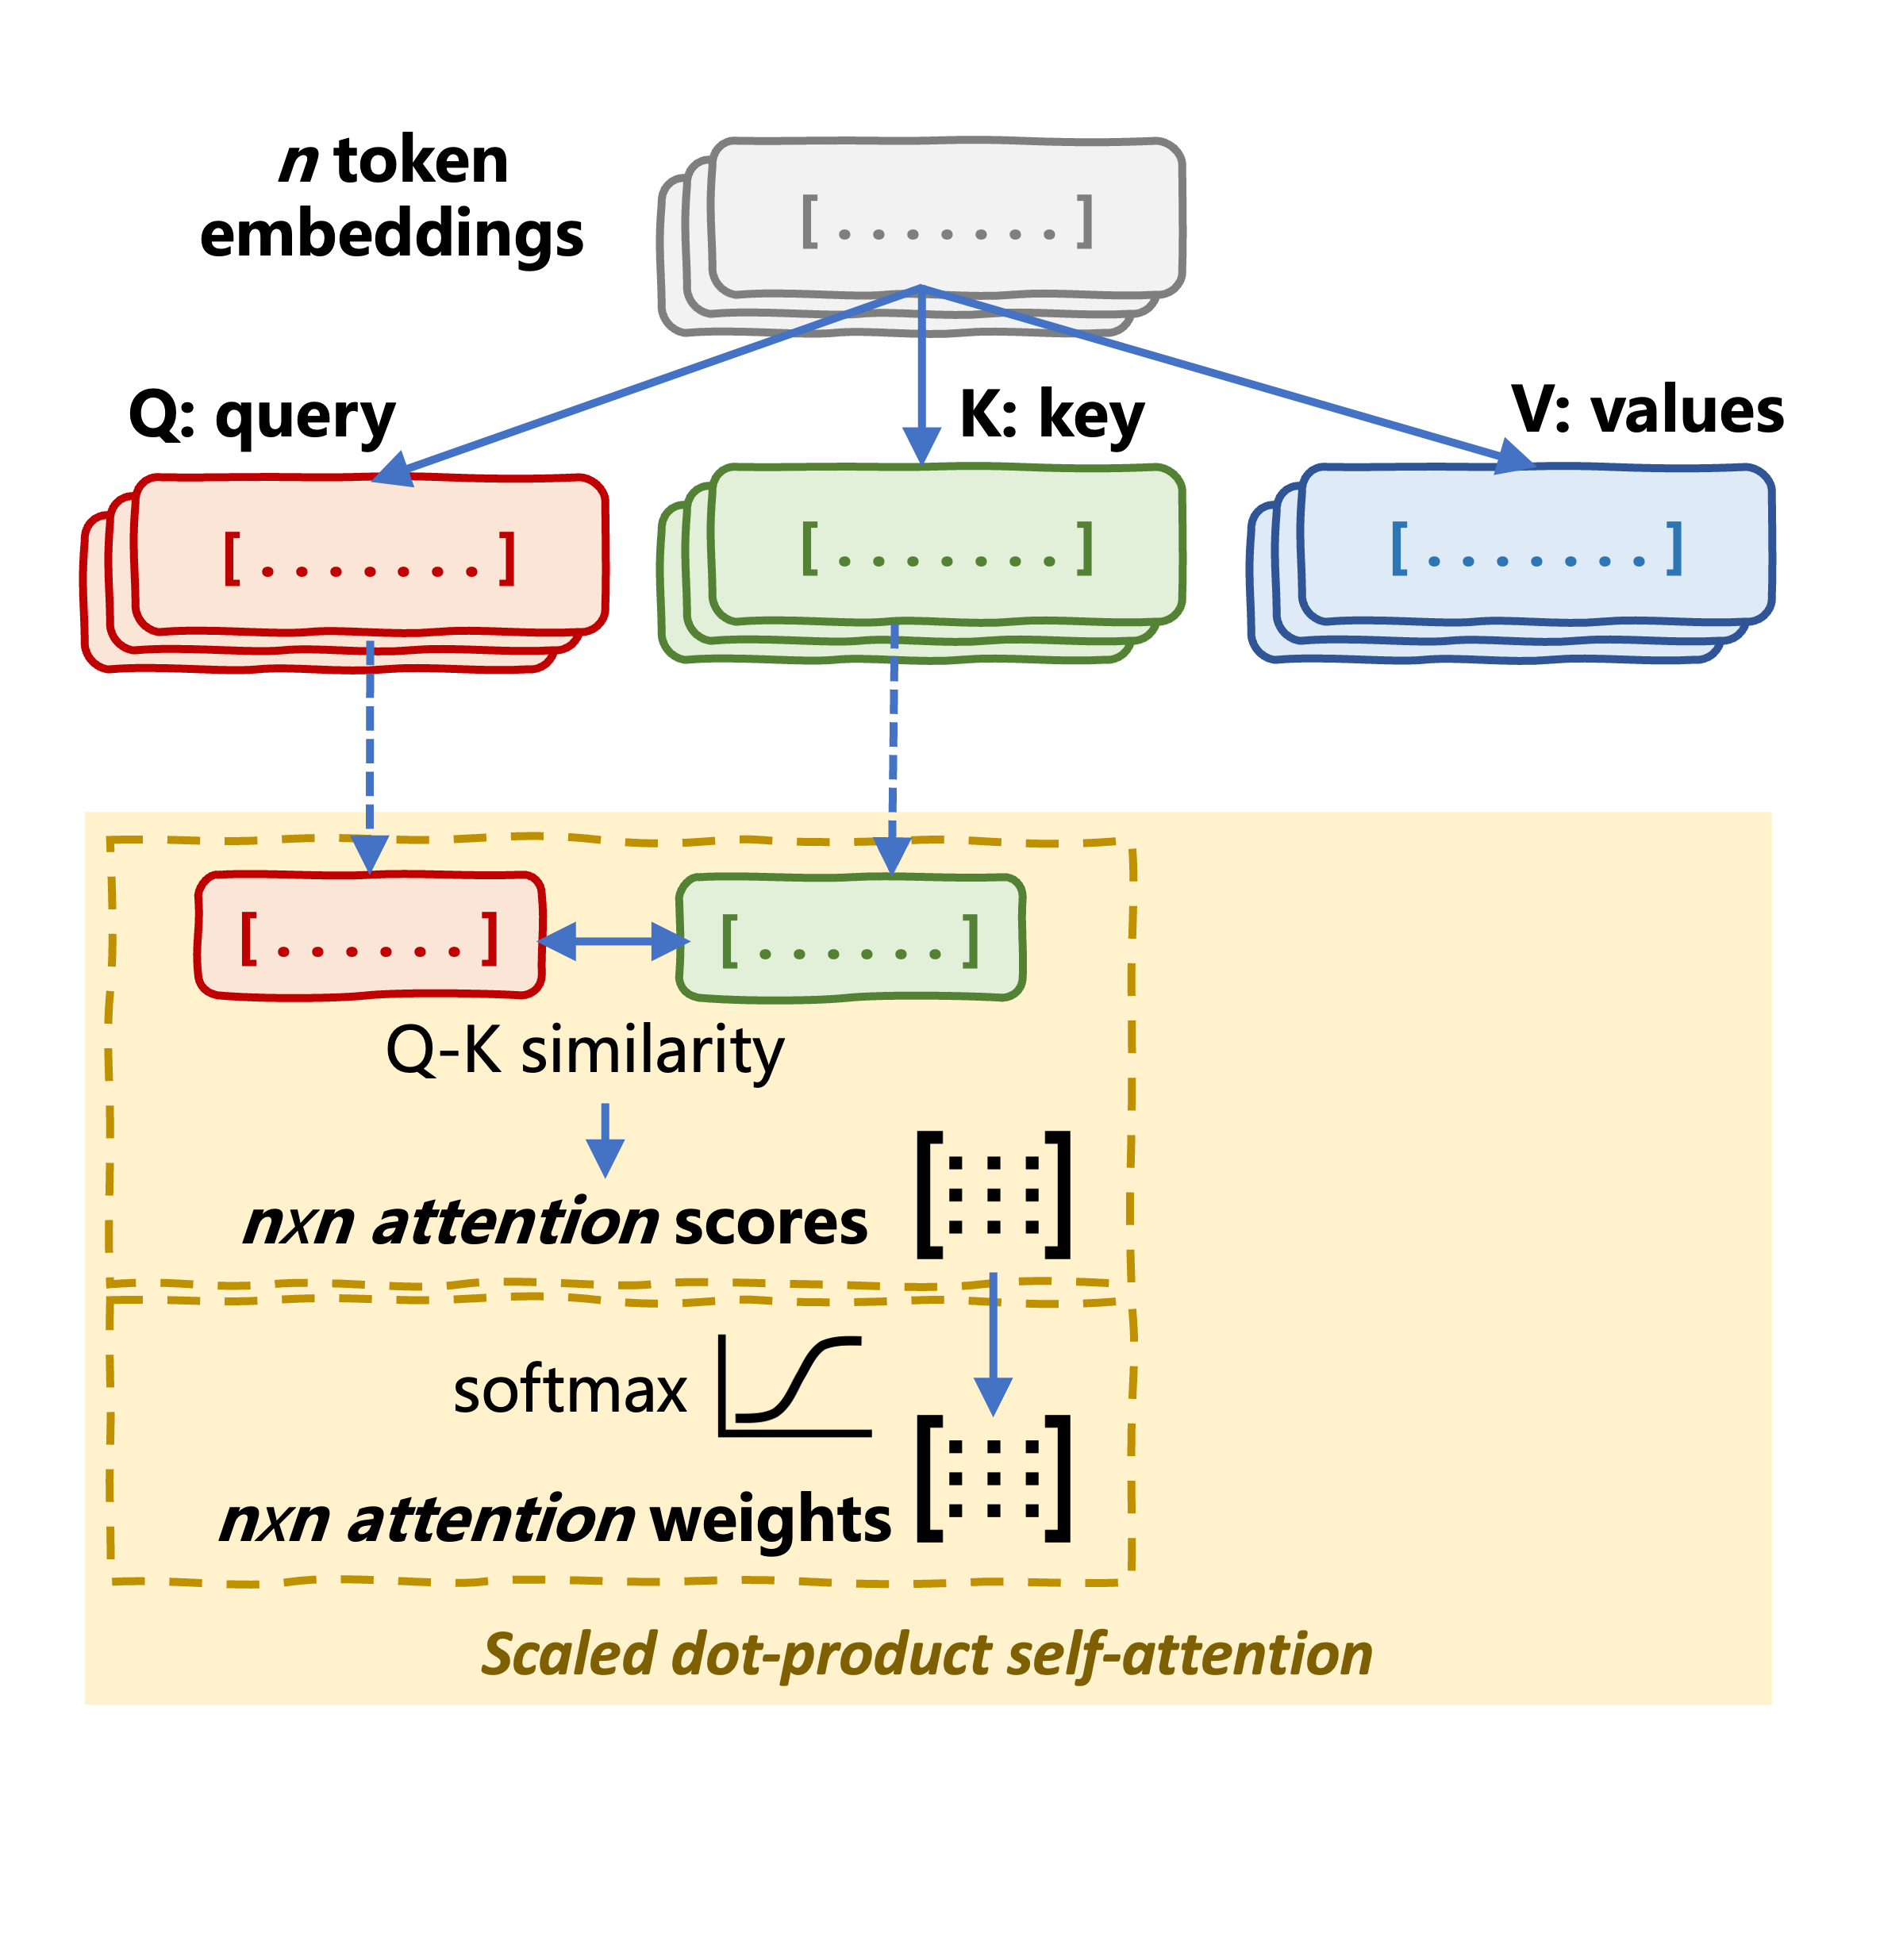
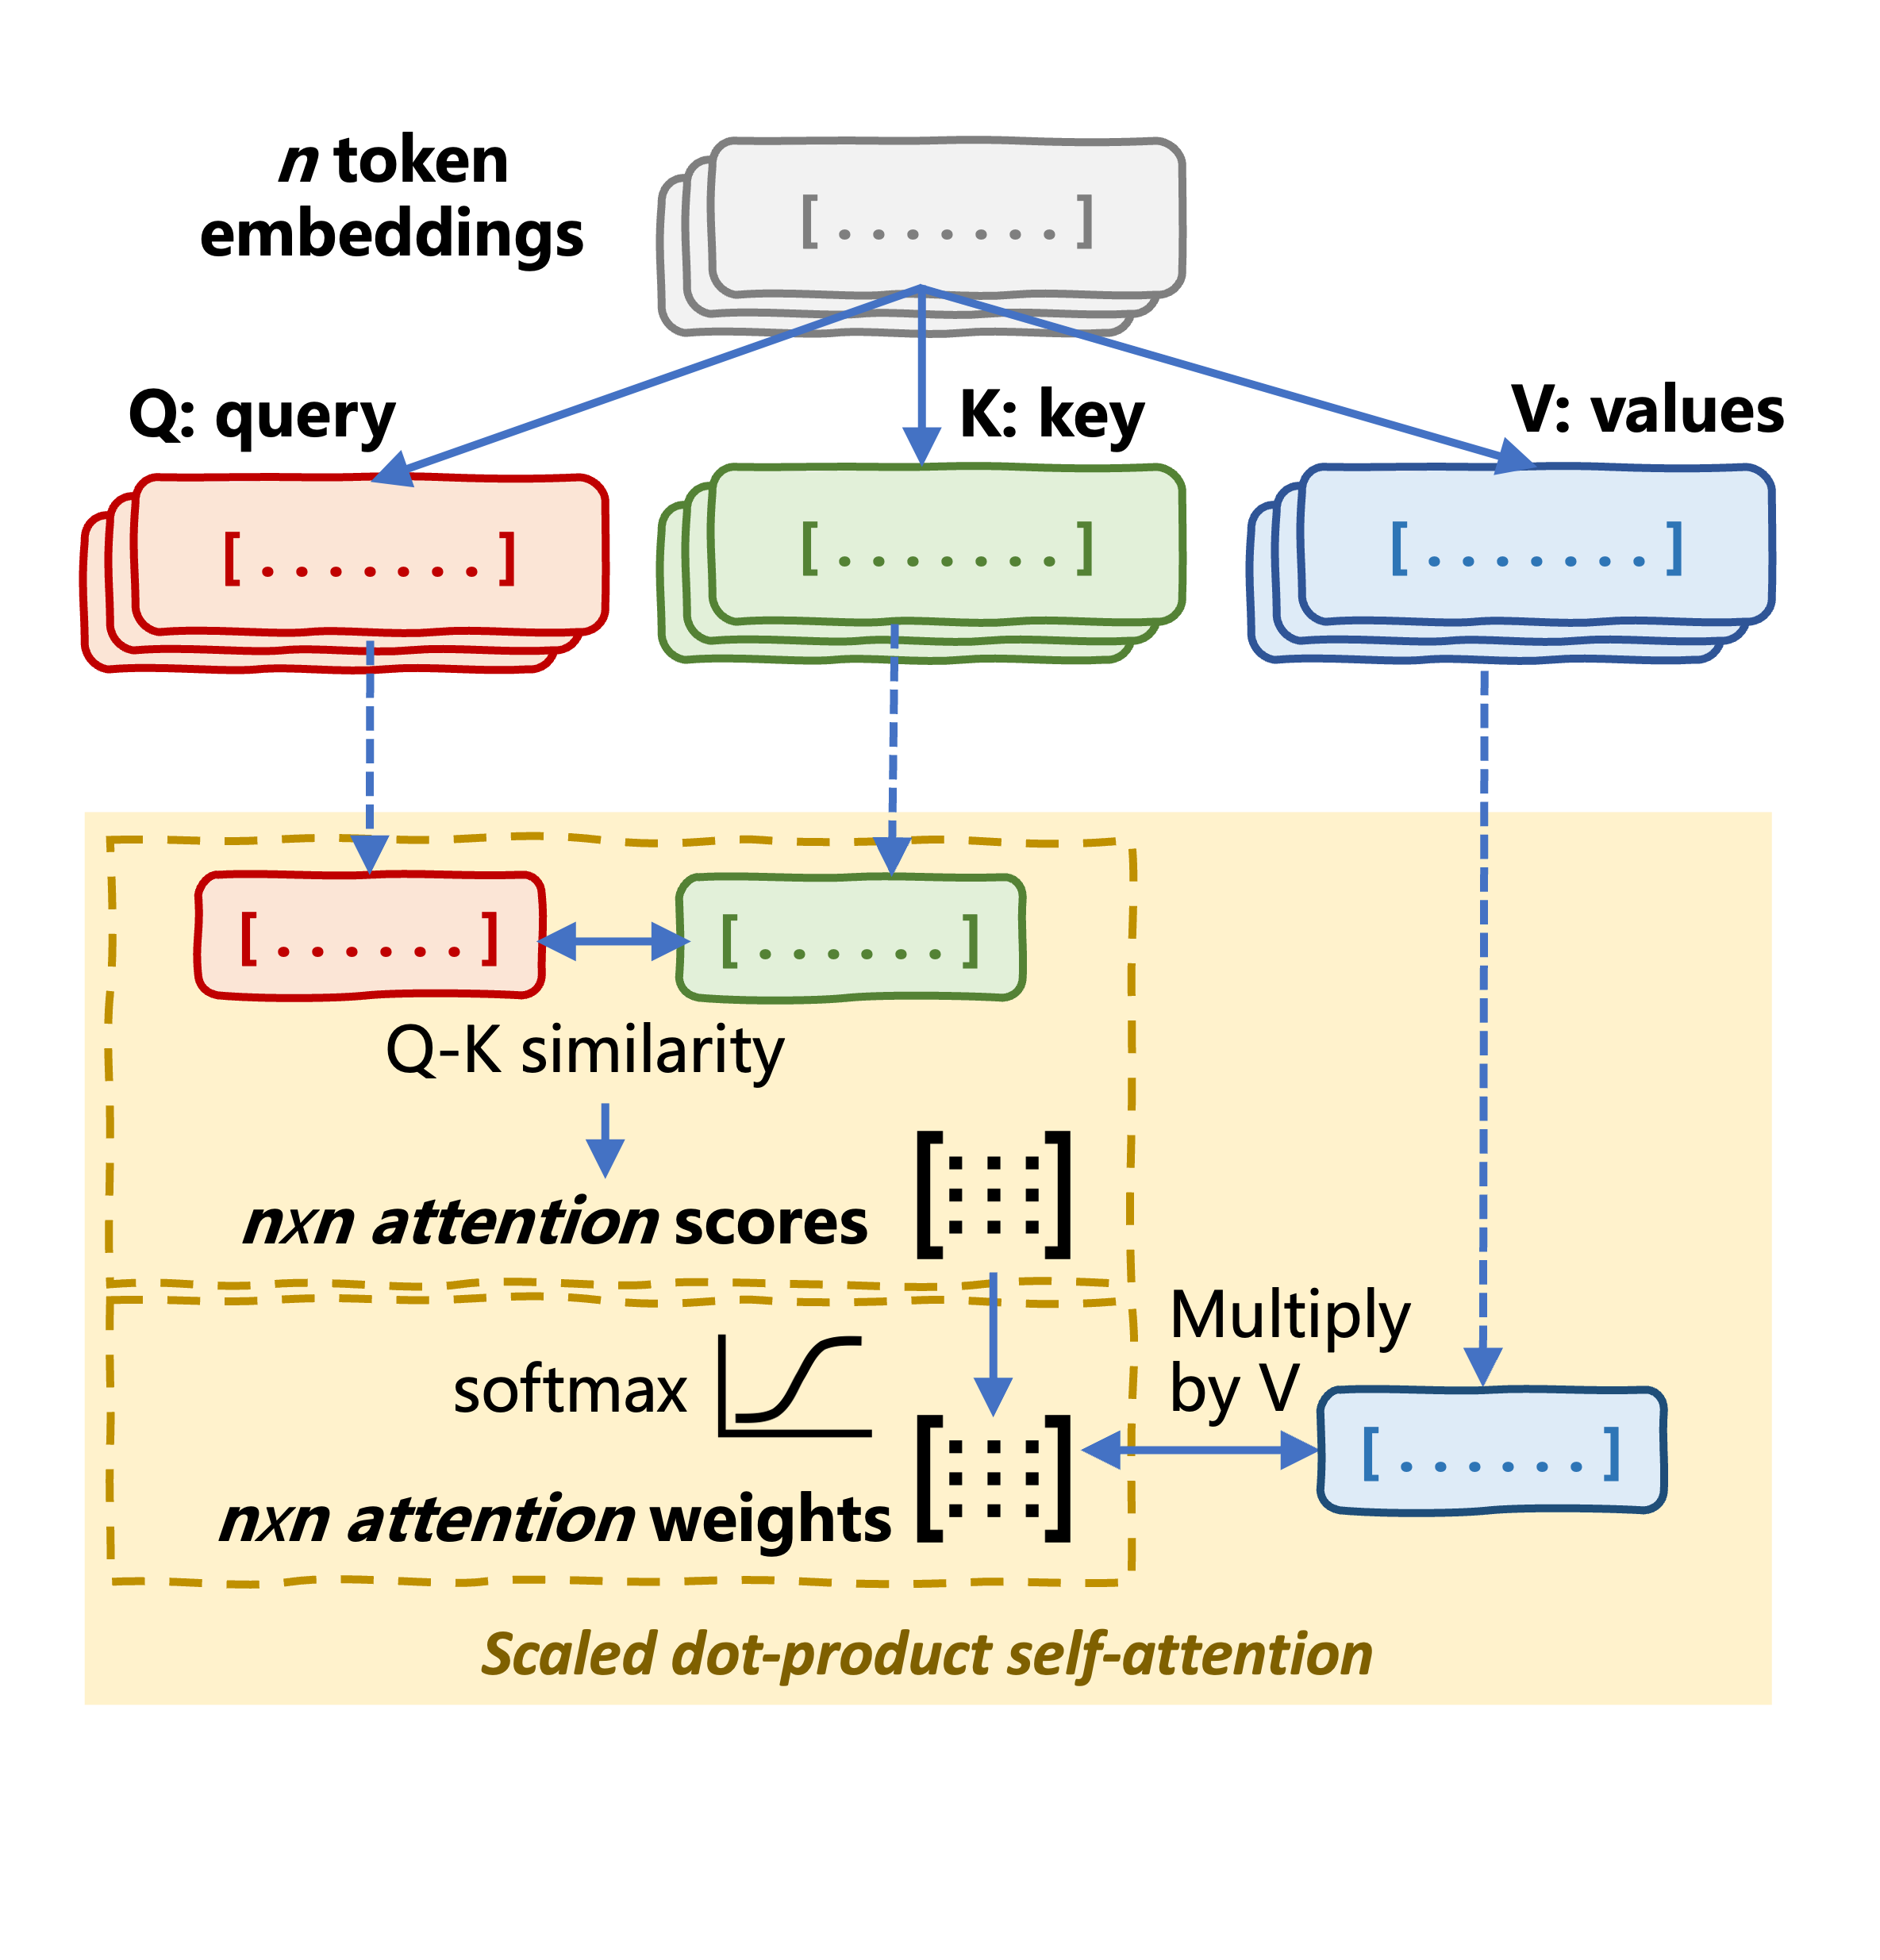
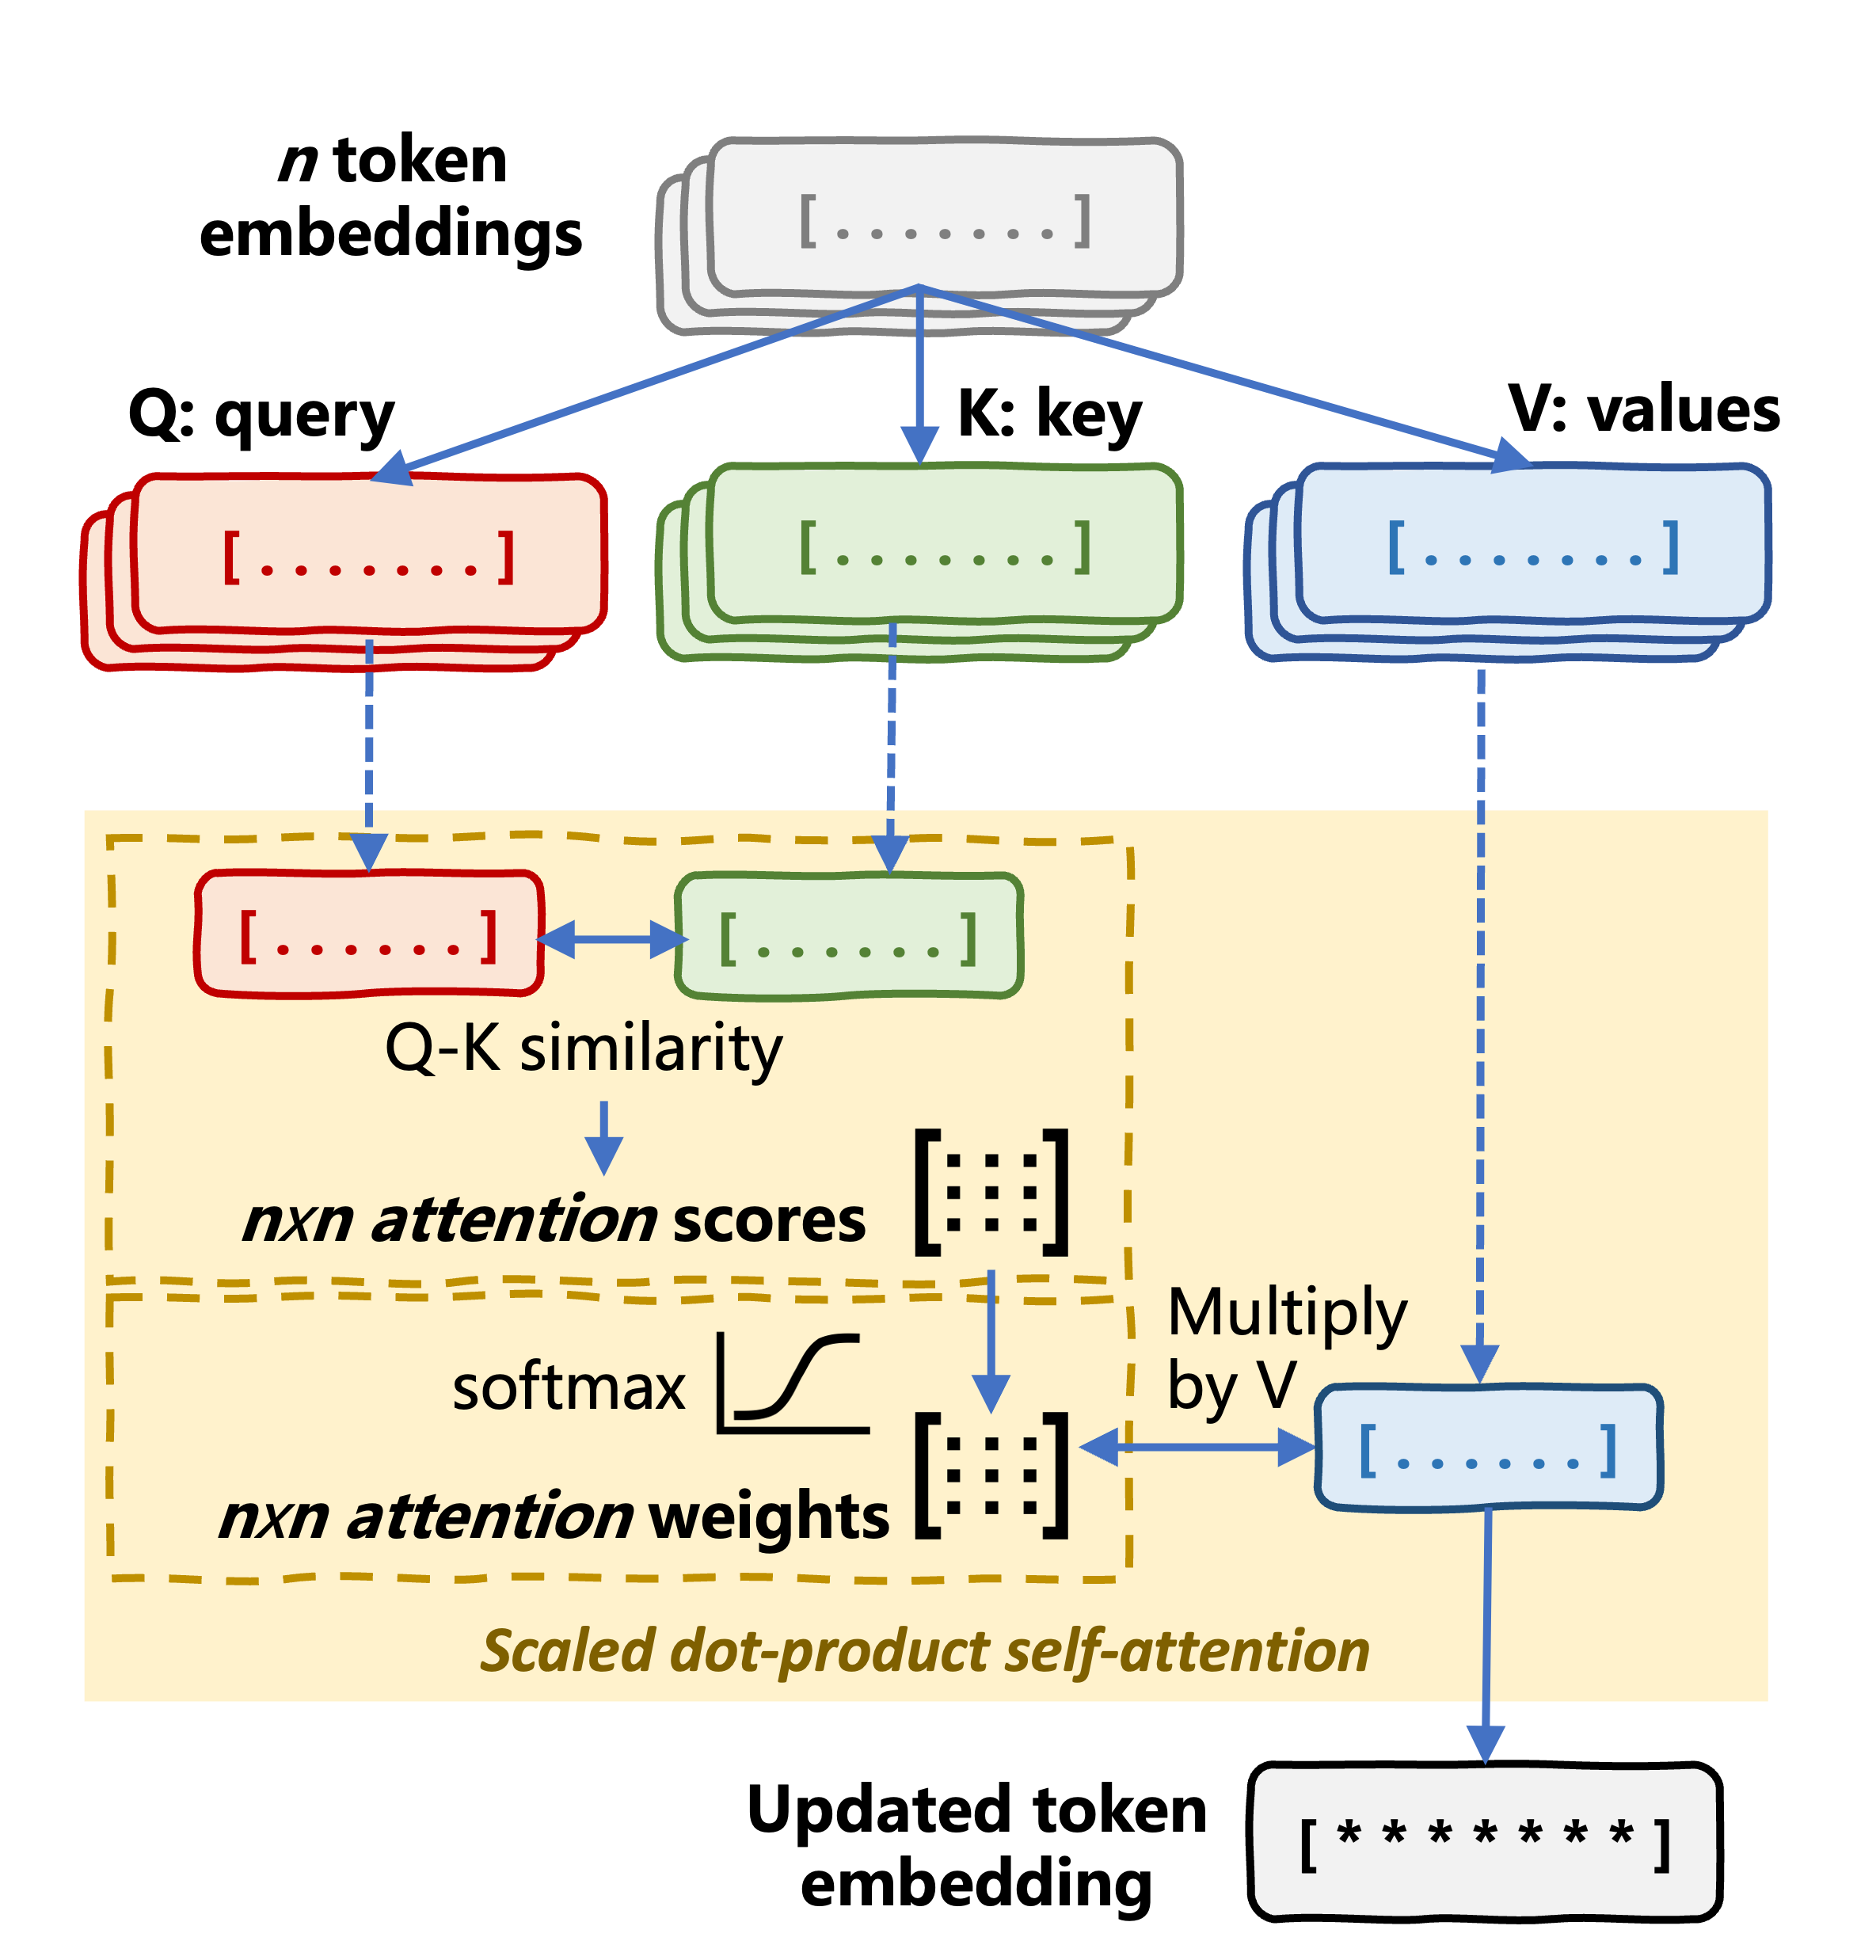
  • Q:指出每個 token 在其它 token 中「要找什麼」
  • K:表示各 token 的內容
  • V:實際要彙整或加權的內容
Transformer Models with PyTorch

自注意力機制

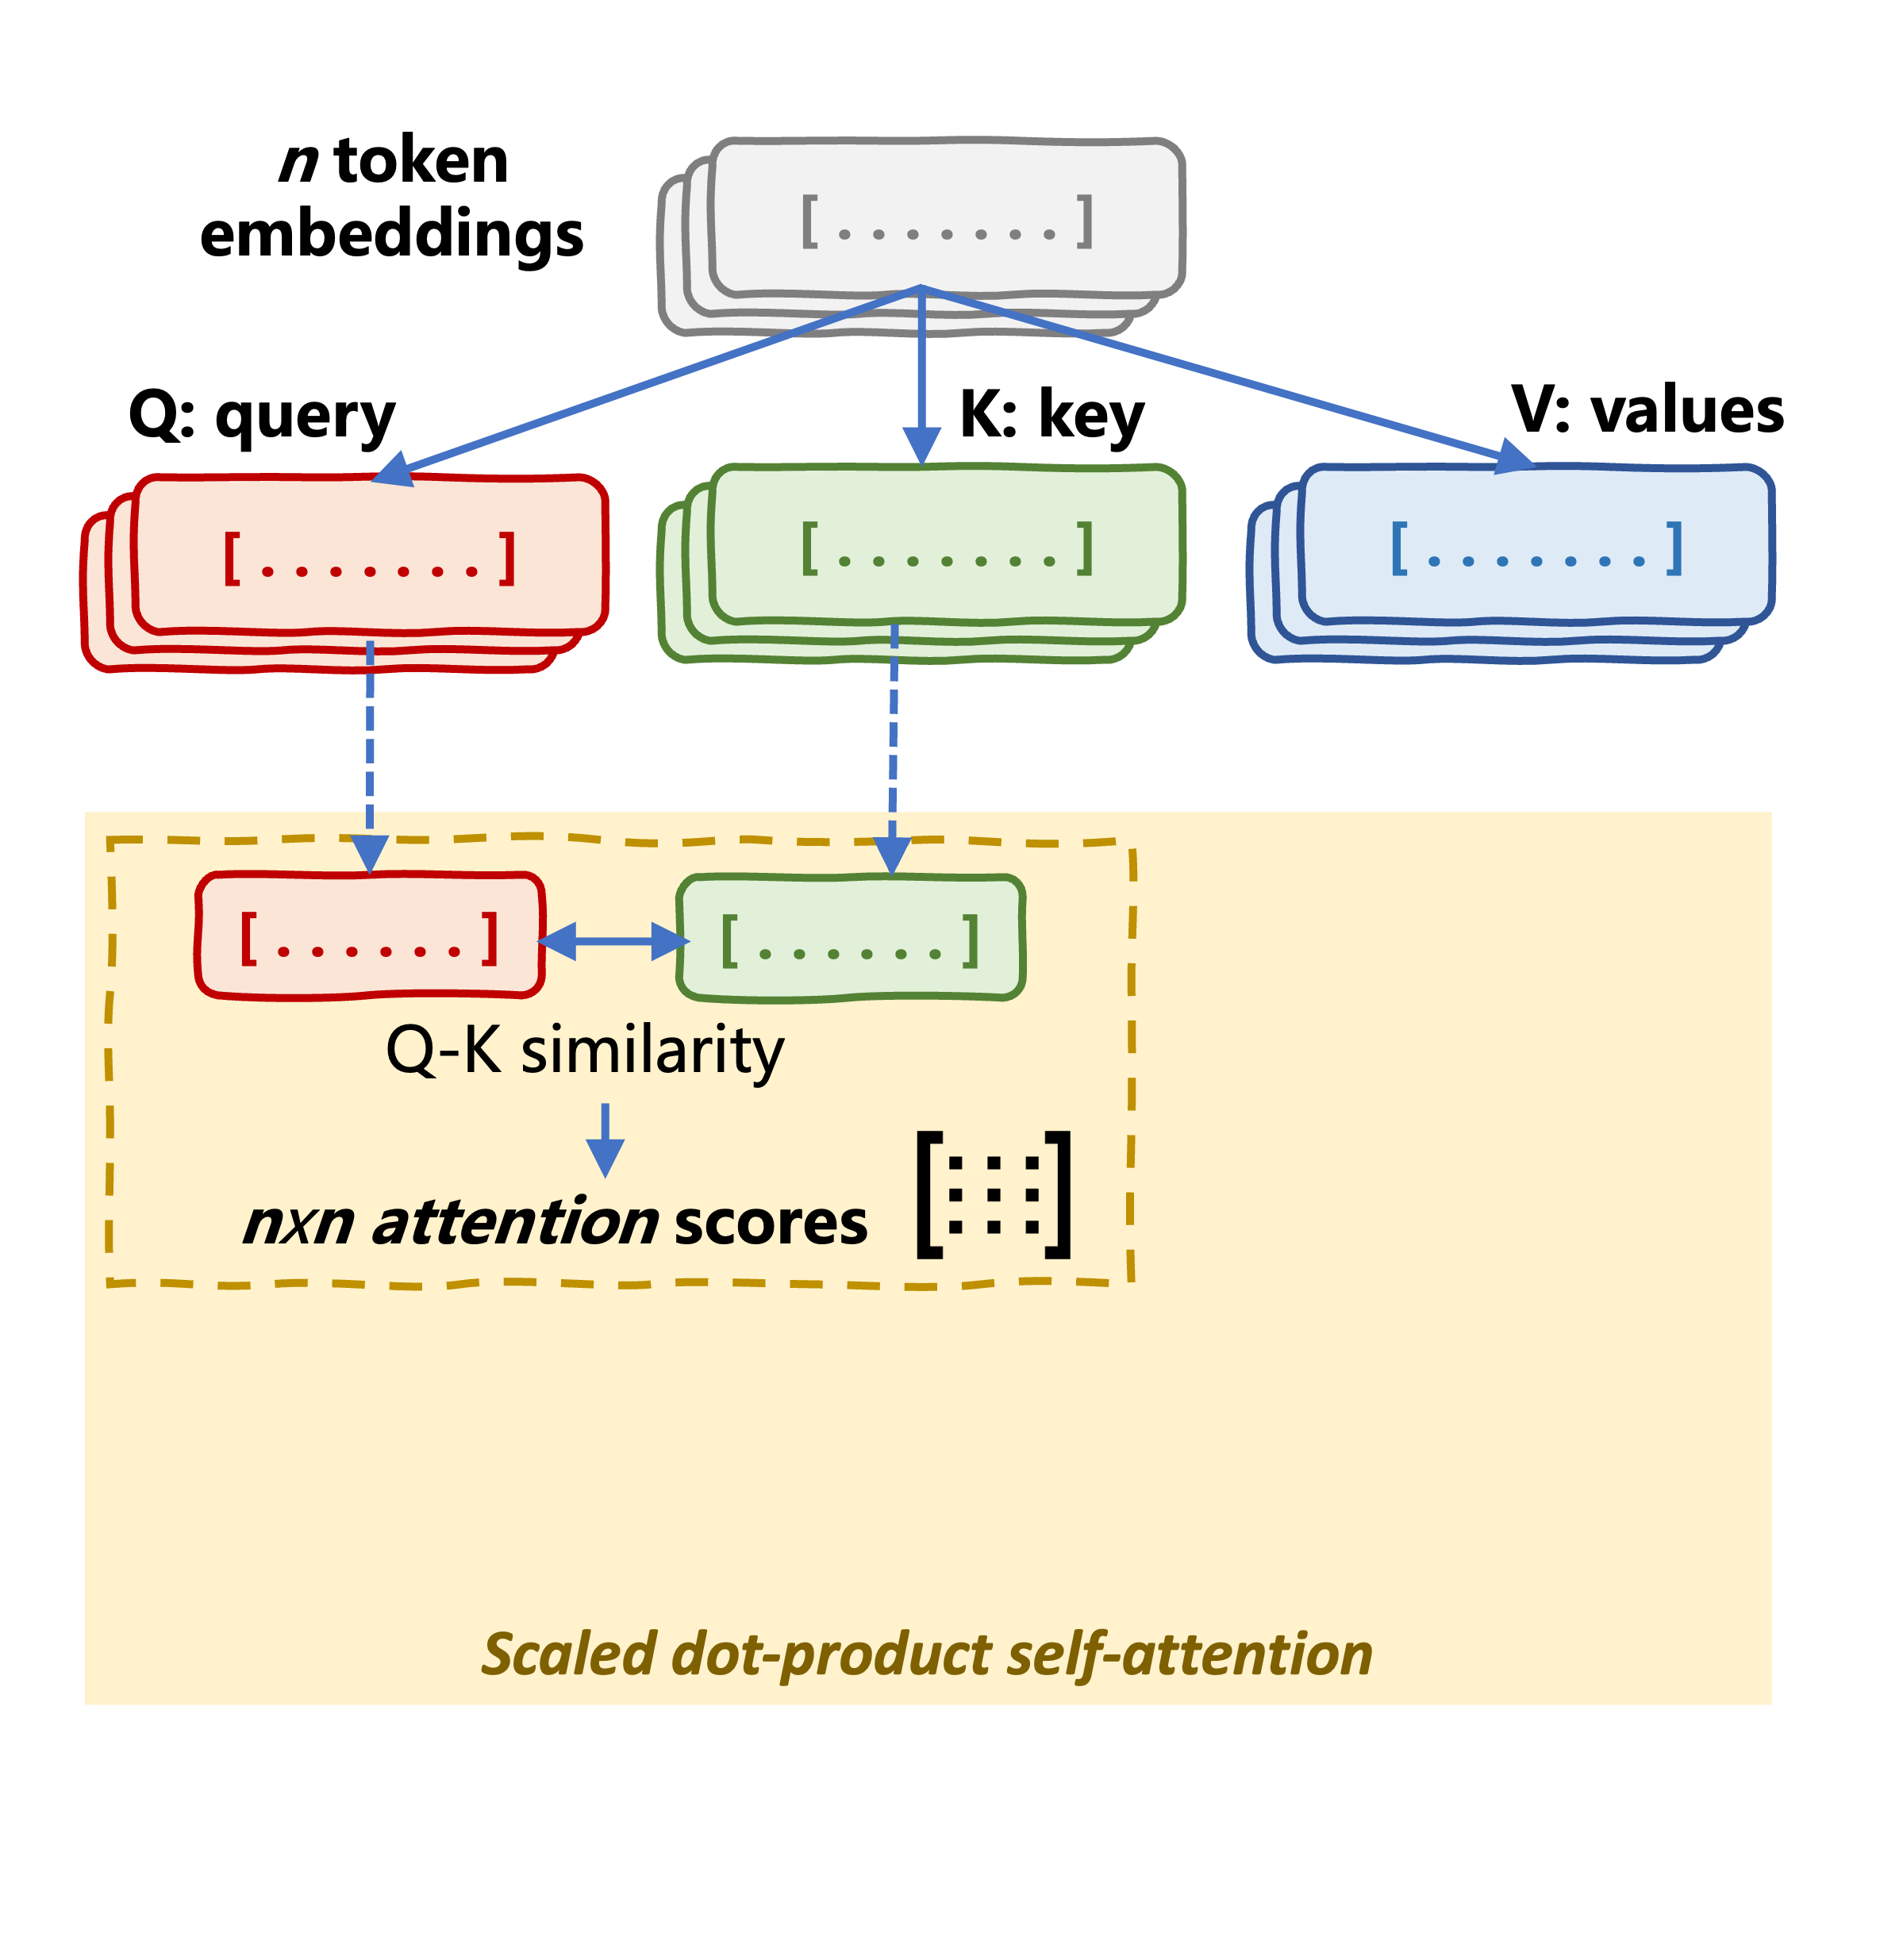
自注意力機制剖析

  • Q:指出每個 token 在其它 token 中「要找什麼」
  • K:表示各 token 的內容
  • V:實際要彙整或加權的內容


  • Attention Scores:Q-K 相似度 → _點積_
Transformer Models with PyTorch

自注意力機制

自注意力機制剖析

  • Q:指出每個 token 在其它 token 中「要找什麼」
  • K:表示各 token 的內容
  • V:實際要彙整或加權的內容


  • Attention Scores:Q-K 相似度 → 點積
  • Attention Weightssoftmax 縮放
Transformer Models with PyTorch

自注意力機制

自注意力機制剖析

  • Attention Scores:Q-K 相似度 → 點積
  • Attention Weightssoftmax 縮放


Orange is my favorite fruit
Query: Orange
Attention weights: .21 .03 .05 .31 .40
Transformer Models with PyTorch

自注意力機制

自注意力機制剖析

  • Attention Scores:Q-K 相似度 → 點積
  • Attention Weightssoftmax 縮放


Orange is my favorite fruit
Query: Orange
Attention weights: .21 .03 .05 .31 .40
Transformer Models with PyTorch

自注意力機制

自注意力機制剖析

  • Attention Scores:Q-K 相似度 → 點積
  • Attention Weightssoftmax 縮放


Orange is my favorite fruit
Query: Orange
Attention weights: .21 .03 .05 .31 .40
Transformer Models with PyTorch

多頭注意力

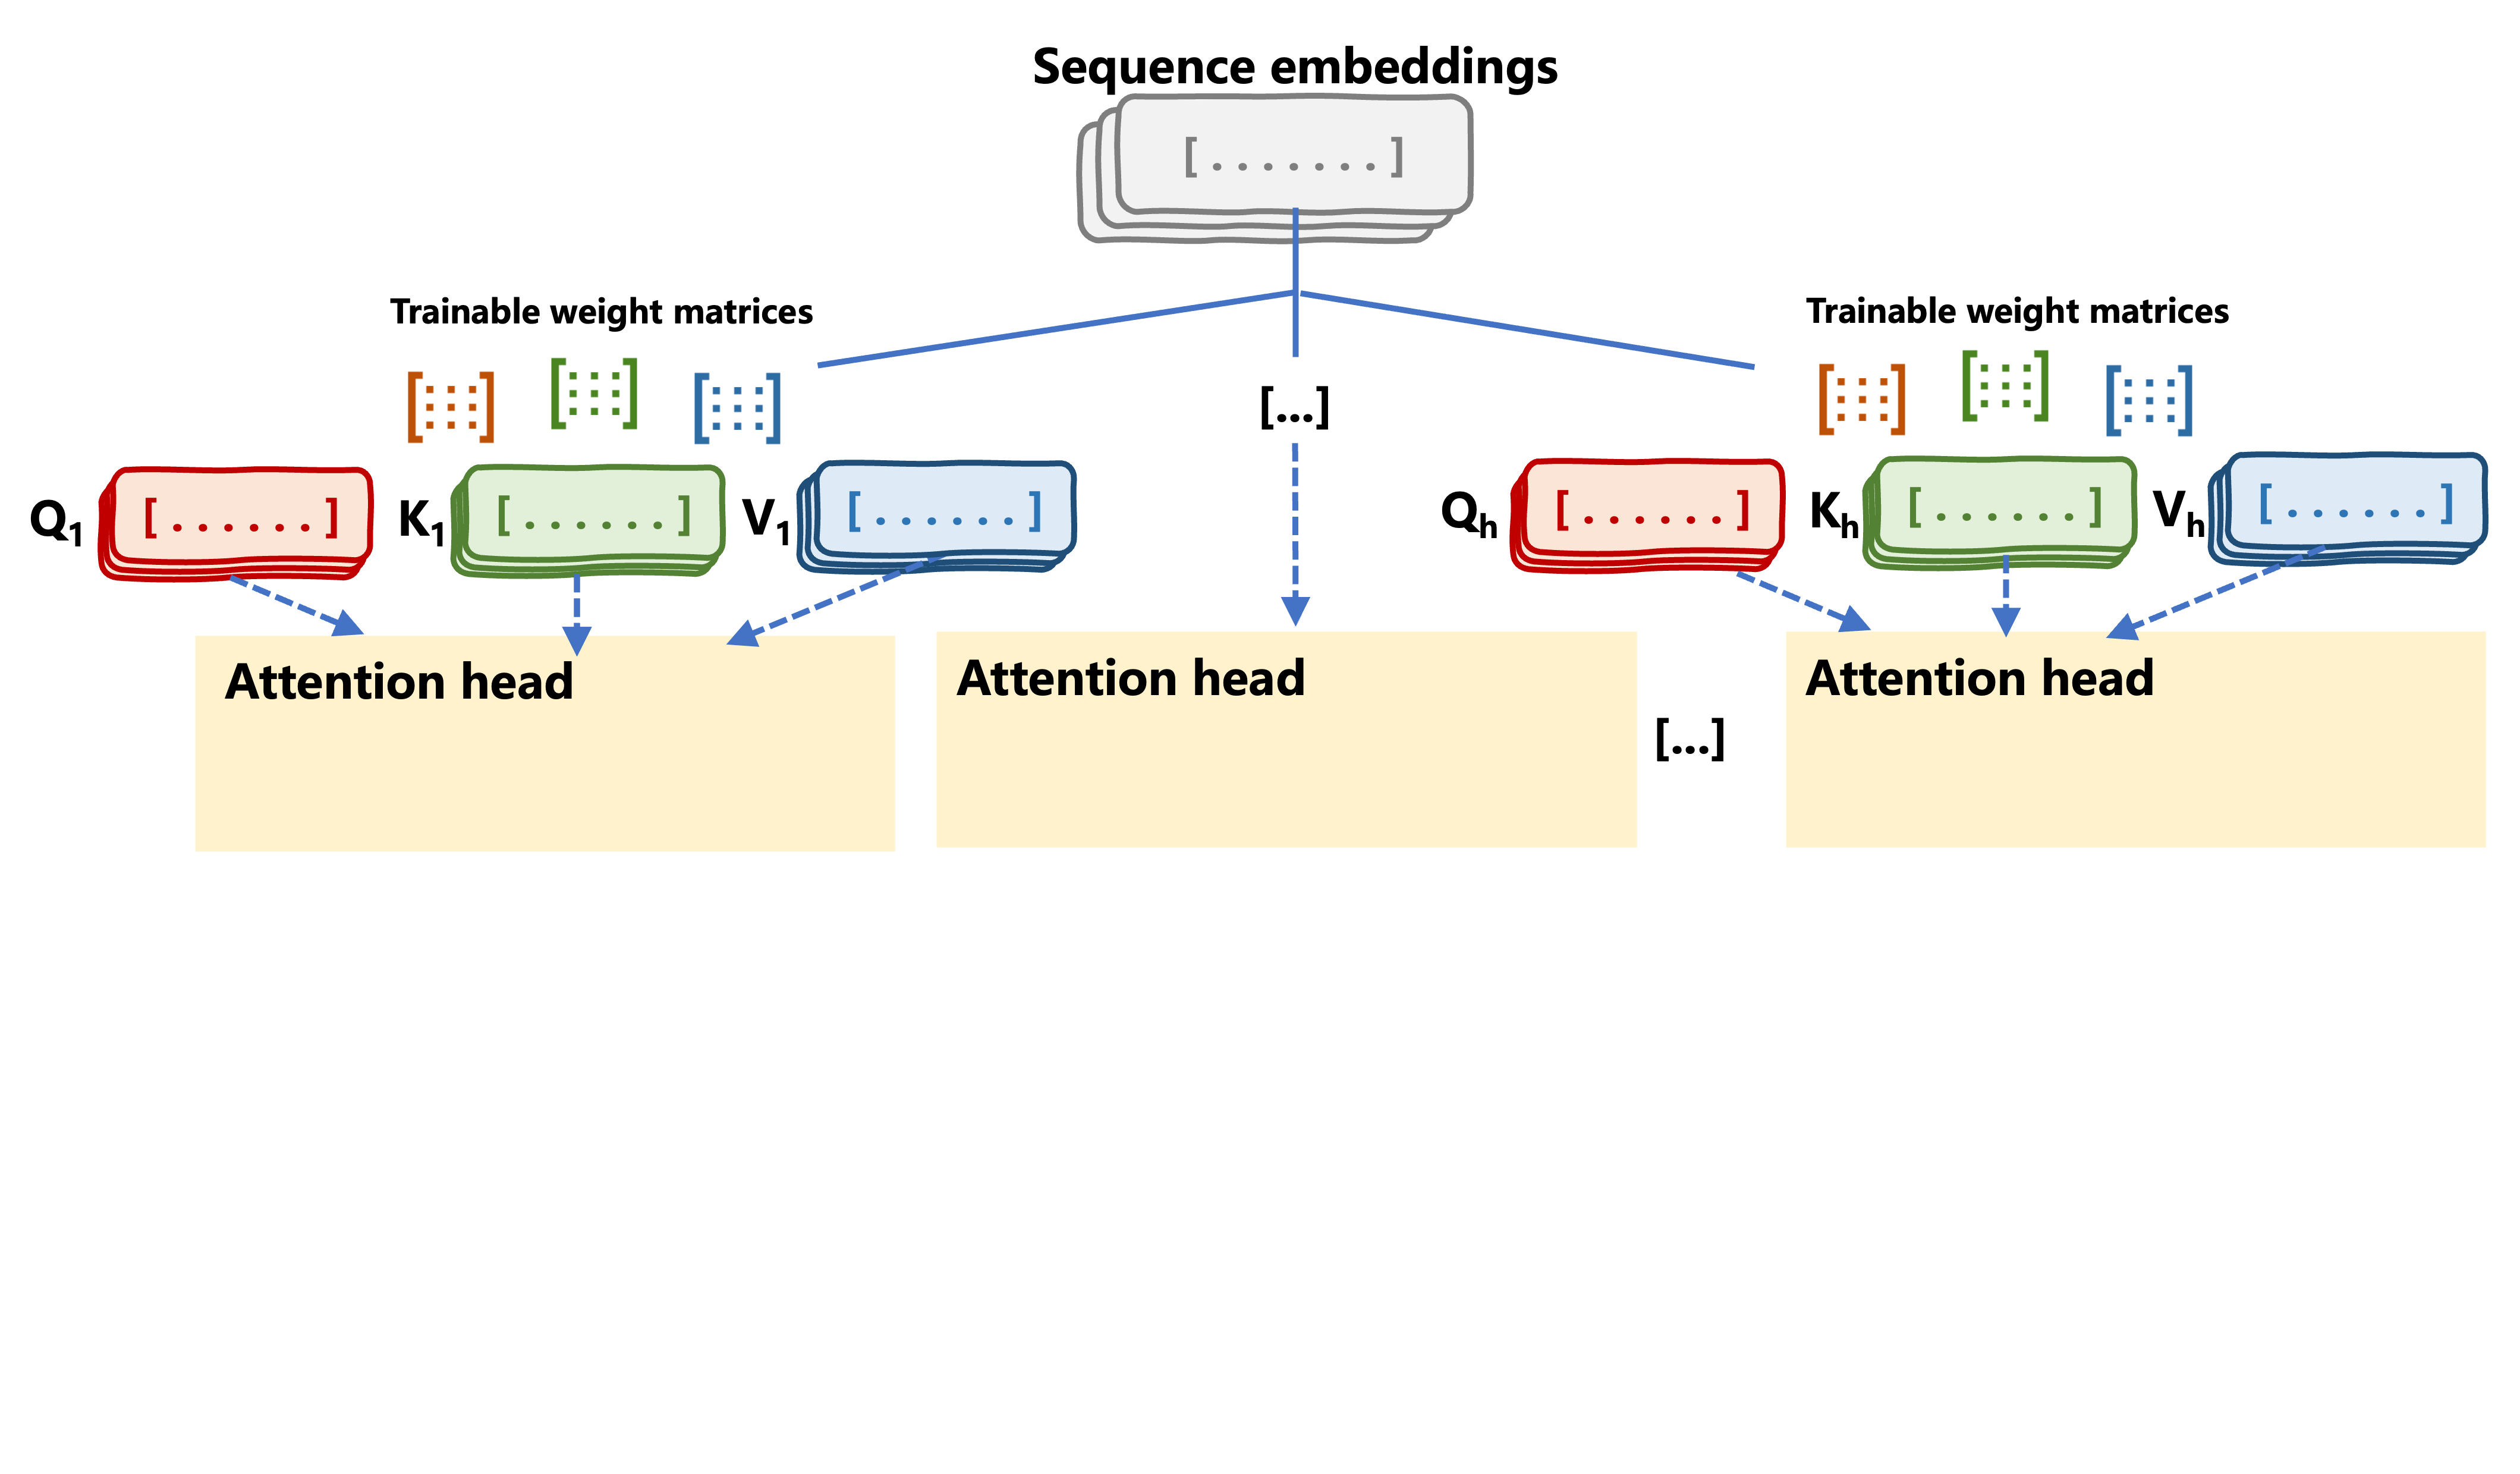
多頭自注意力

Transformer Models with PyTorch

多頭注意力

多頭自注意力

Transformer Models with PyTorch

多頭注意力

多頭自注意力

Transformer Models with PyTorch
import torch.nn as nn
import torch.nn.functional as F

class MultiHeadAttention(nn.Module):

def __init__(self, d_model, num_heads): super().__init__()
assert d_model % num_heads == 0, "d_model must be divisible by num_heads."
self.num_heads = num_heads self.d_model = d_model self.head_dim = d_model // num_heads
self.query_linear = nn.Linear(d_model, d_model, bias=False) self.key_linear = nn.Linear(d_model, d_model, bias=False) self.value_linear = nn.Linear(d_model, d_model, bias=False)
self.output_linear = nn.Linear(d_model, d_model)
  • num_heads:注意力頭的數量,每個負責大小為 head_dim 的嵌入
  • bias=False:在降低複雜度的同時不影響效能(僅限輸入層)
Transformer Models with PyTorch
    def split_heads(self, x, batch_size):

seq_length = x.size(1) x = x.reshape(batch_size, seq_length, self.num_heads, self.head_dim) return x.permute(0, 2, 1, 3)
def compute_attention(self, query, key, value, mask=None):
scores = torch.matmul(query, key.transpose(-2, -1)) / (self.head_dim ** 0.5)
if mask is not None: scores = scores.masked_fill(mask == 0, float('-inf'))
attention_weights = F.softmax(scores, dim=-1) return torch.matmul(attention_weights, value)
def combine_heads(self, x, batch_size):
x = x.permute(0, 2, 1, 3).contiguous() return x.view(batch_size, -1, self.d_model)
  • compute_attention():使用 F.softmax() 計算注意力權重
  • torch.matmul(attention_weights, value):對 value 做加權總和
Transformer Models with PyTorch
    def forward(self, query, key, value, mask=None):
        batch_size = query.size(0)

        query = self.split_heads(self.query_linear(query), batch_size)
        key = self.split_heads(self.key_linear(key), batch_size)
        value = self.split_heads(self.value_linear(value), batch_size)

        attention_weights = self.compute_attention(query, key, value, mask)


output = self.combine_heads(attention_weights, batch_size)
return self.output_linear(output)
  • self.output_linear():串接並投影各頭的輸出
Transformer Models with PyTorch

一起來練習吧!

Transformer Models with PyTorch

Preparing Video For Download...