CSS 定位器

Python 網頁爬蟲

Thomas Laetsch

Data Scientist, NYU

Rosetta CSStone

  • /(首字元除外)改為 >
    • XPath: /html/body/div
    • CSS 定位器: html > body > div
  • //(首字元除外)改為空白
    • XPath: //div/span//p
    • CSS 定位器: div > span p
  • [N] 改為 :nth-of-type(N)
    • XPath: //div/p[2]
    • CSS 定位器: div > p:nth-of-type(2)
Python 網頁爬蟲

Rosetta CSStone

XPATH

xpath = '/html/body//div/p[2]'

CSS

css = 'html > body div > p:nth-of-type(2)'
Python 網頁爬蟲

CSS 的屬性選取

  • 以類別尋找元素,用句點 .
    • 範例:p.class-1 會選到屬於 class-1 的所有段落元素
  • 以 id 尋找元素,用井字號 #
    • 範例:div#uid 會選到 id 等於 uiddiv 元素
Python 網頁爬蟲

CSS 的屬性選取

選取類別為 class1 內的段落元素:

css_locator = 'div#uid > p.class1'

選取所有 class 屬性屬於 class1 的元素:

css_locator = '.class1'
Python 網頁爬蟲

Class 狀態

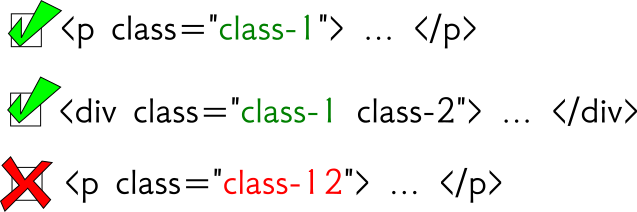
css = '.class1'

類別選取:僅類別

Python 網頁爬蟲

Class 狀態

xpath = '//*[@class="class1"]'
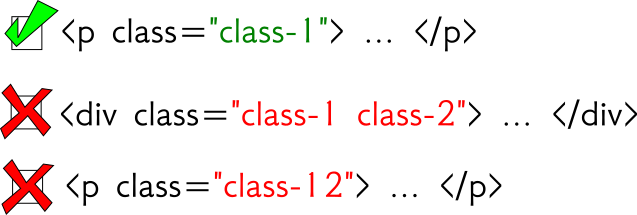
類別選取:等於

Python 網頁爬蟲

Class 狀態

xpath = '//*[contains(@class,"class1")]'
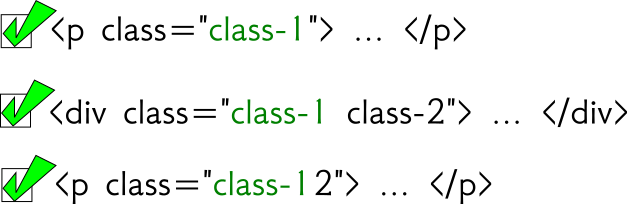
類別選取:包含

Python 網頁爬蟲

使用 CSS 的選取器

from scrapy import Selector 

html = '''
<html>
  <body>
    <div class="hello datacamp">
      <p>Hello World!</p>
    </div>
    <p>Enjoy DataCamp!</p>
  </body>
</html>
''' 
sel = Selector( text = html )
>>> sel.css("div > p")
out: [<Selector xpath='...' data='<p>Hello World!</p>'>] 

>>> sel.css("div > p").extract()
out: [ '<p>Hello World!</p>' ]
Python 網頁爬蟲

C(SS) You Soon!

Python 網頁爬蟲

Preparing Video For Download...