解釋非監督式模型

Python 的 Explainable AI

Fouad Trad

Machine Learning Engineer

分群(Clustering)

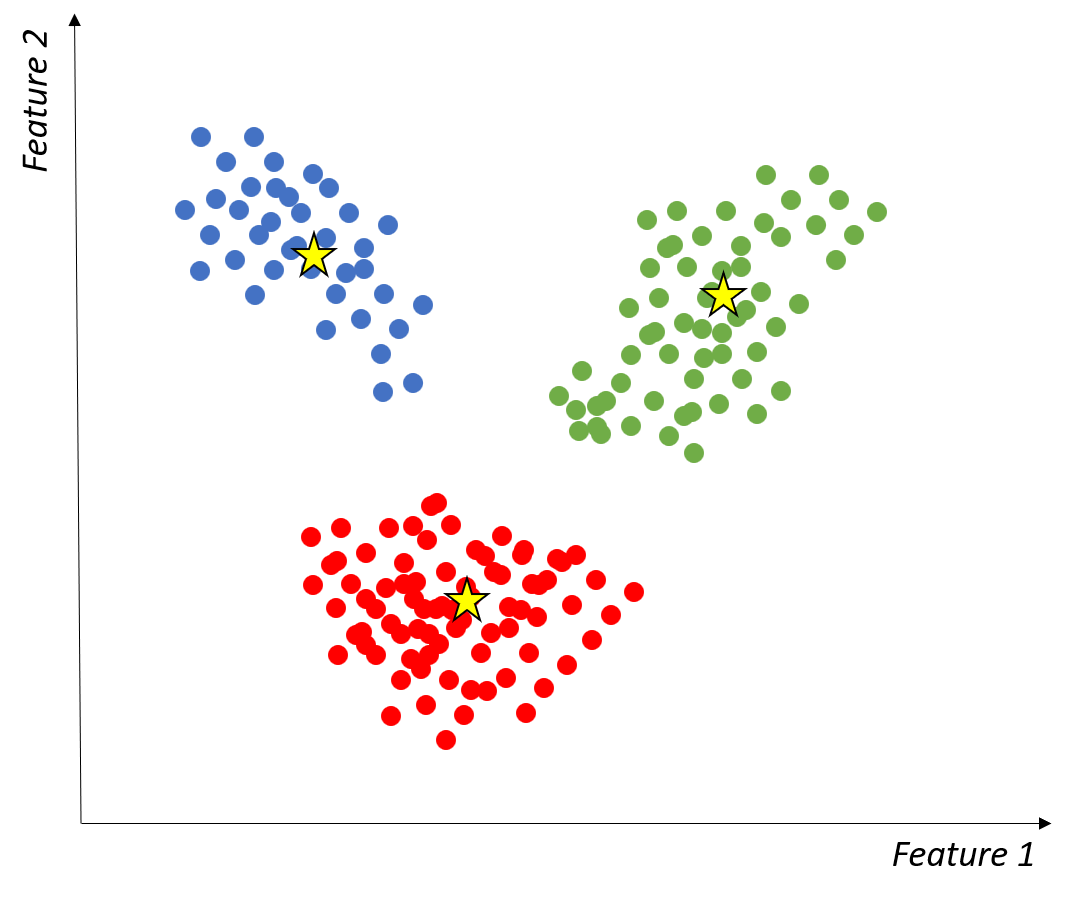
在沒有預先標籤下分群相似的資料點
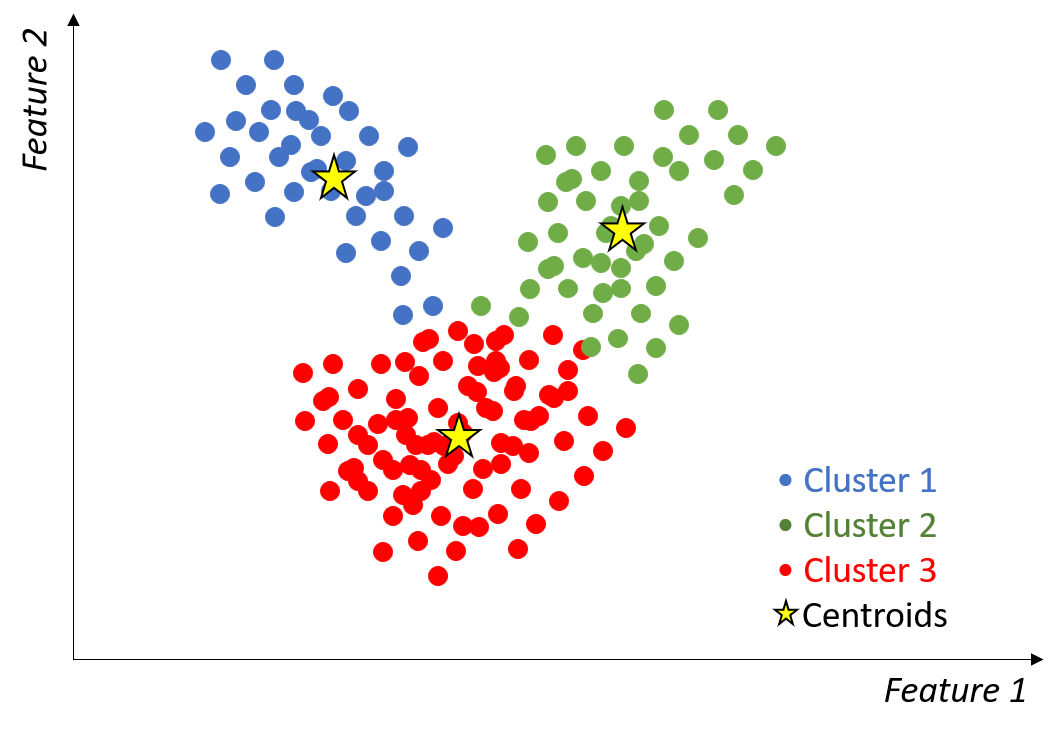
顯示具有 2 個特徵的資料被分成 3 群,每群都有群心的圖片。

Python 的 Explainable AI

Silhouette score(輪廓係數)

  • 衡量分群品質
  • 範圍從 -1 到 1
    • 1 → 分群分離良好

顯示分離良好的叢集圖片。

Python 的 Explainable AI

Silhouette score(輪廓係數)

  • 衡量分群品質
  • 範圍從 -1 到 1
    • 1 → 分群分離良好
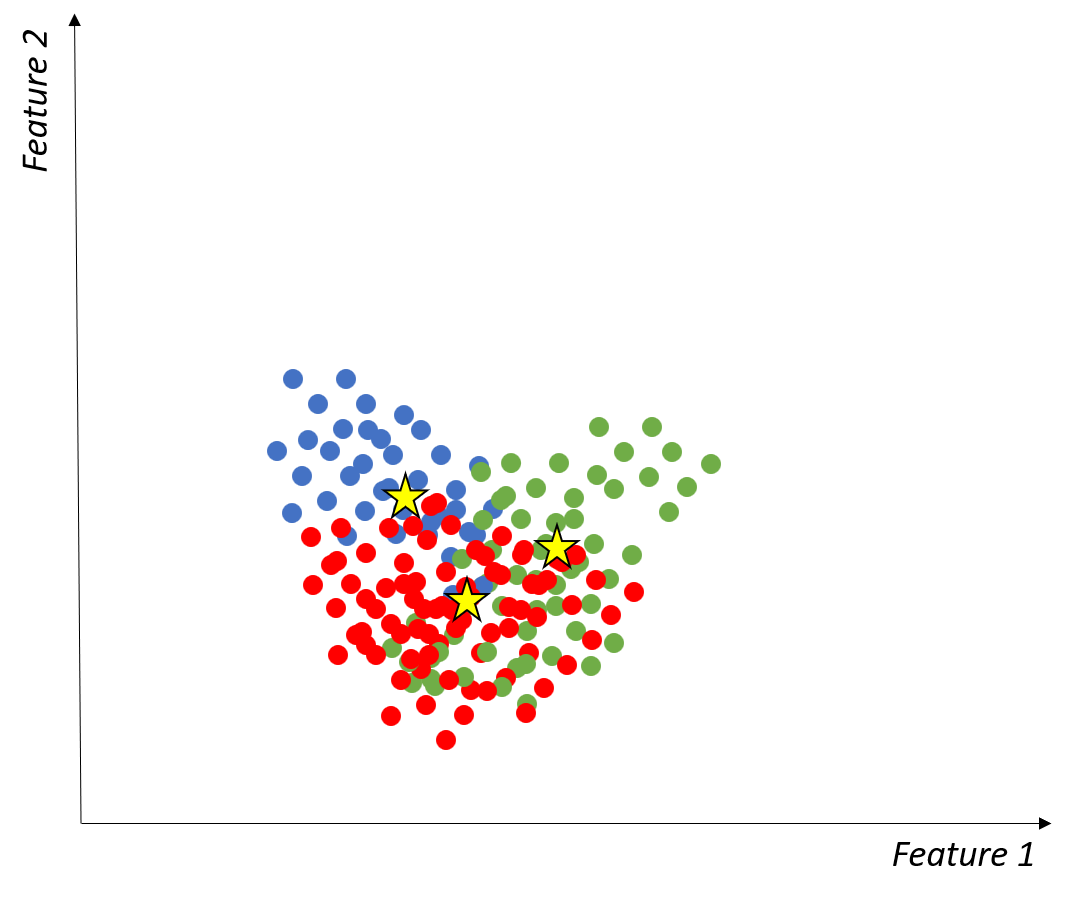
    • -1 → 點被錯誤分配

顯示分群界線不明顯的圖片。

Python 的 Explainable AI

特徵對分群品質的影響

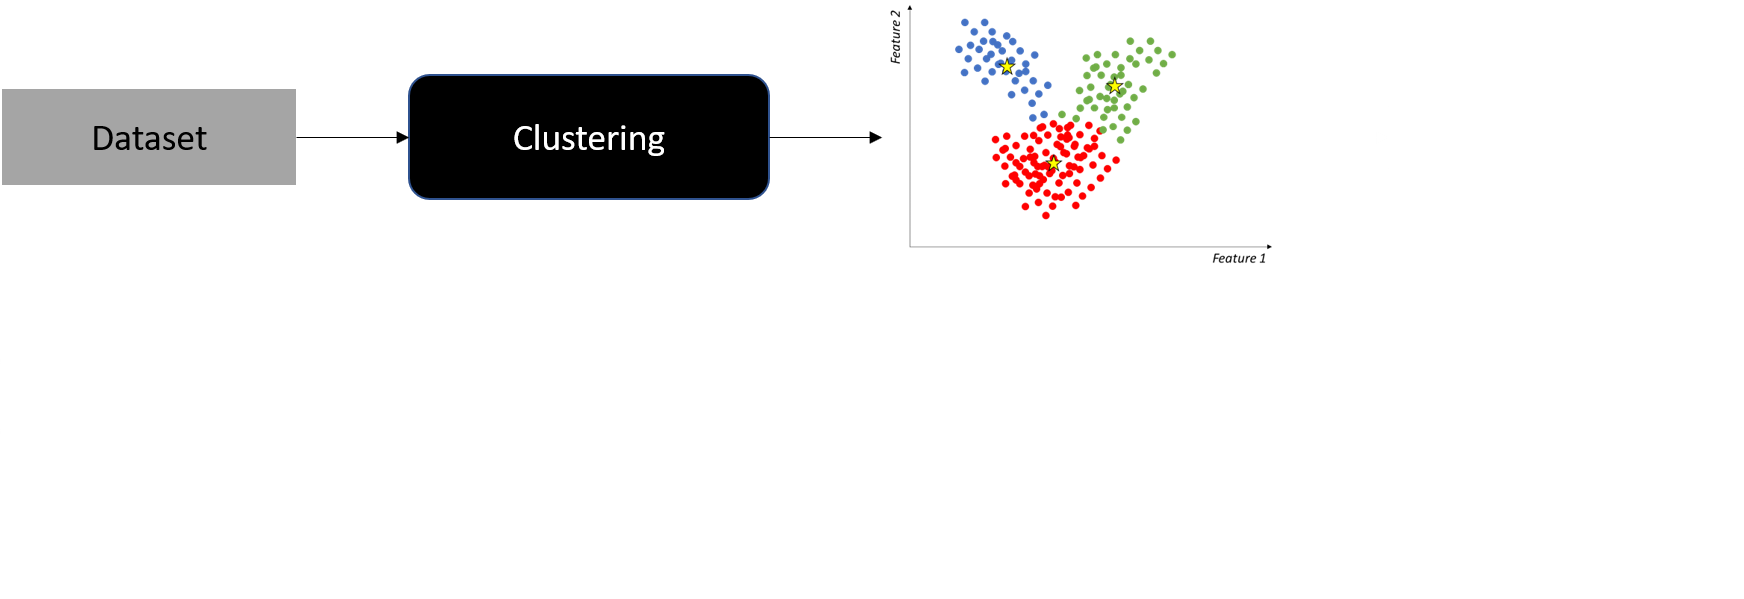
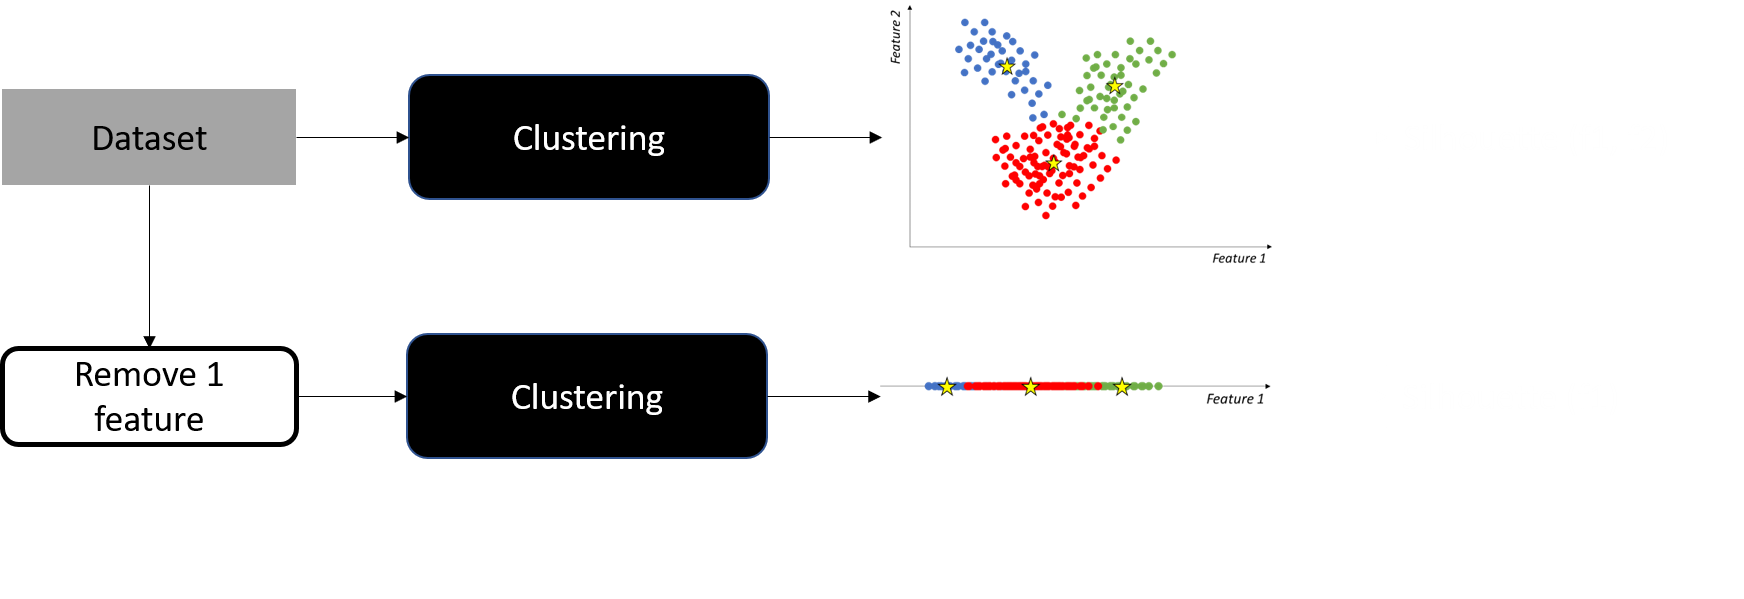
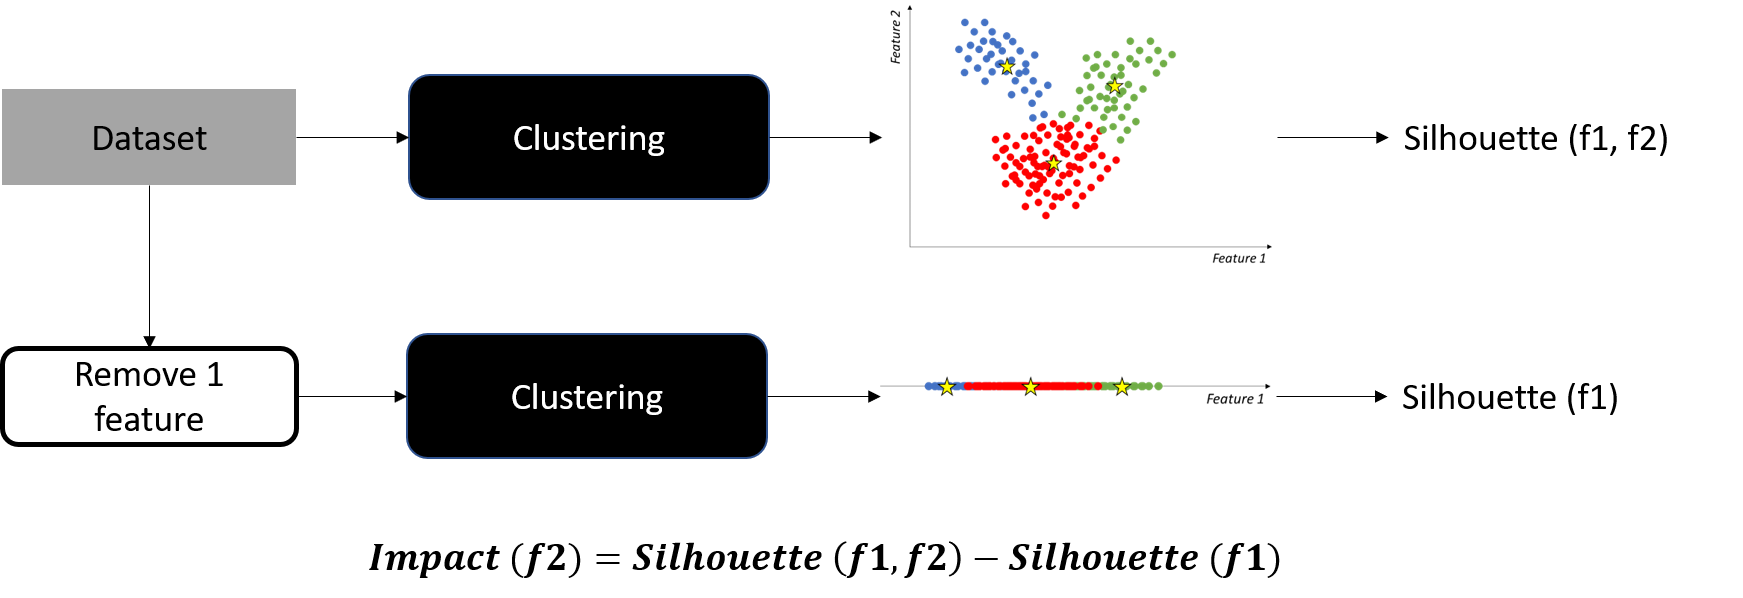
顯示以 2 個特徵進行分群後的結果圖片。

Python 的 Explainable AI

特徵對分群品質的影響

顯示移除一個特徵並重新訓練模型後的分群結果圖片。

Python 的 Explainable AI

特徵對分群品質的影響

顯示用兩個特徵的輪廓分數與移除該特徵後的輪廓分數差,來推導被移除特徵影響力的公式圖片。

  • $\text{Impact(}f) > 0$ → $f$ 有正面貢獻
  • $\text{Impact(}f) < 0$ → $f$ 引入雜訊
Python 的 Explainable AI

Student Performance 資料集

age health status absences G1 G2 G3
18 3 4 0 11 11
17 3 2 9 11 11
15 3 6 12 13 12
15 5 0 14 14 14
16 5 0 11 13 13


X:包含特徵的陣列

Python 的 Explainable AI

計算特徵對分群品質的影響

from sklearn.cluster import KMeans
from sklearn.metrics import silhouette_score


kmeans = KMeans(n_clusters=2).fit(X)
original_score = silhouette_score(X, kmeans.labels_)
for i in range(X.shape[1]):
X_reduced = np.delete(X, i, axis=1)
kmeans.fit(X_reduced)
new_score = silhouette_score(X_reduced, kmeans.labels_)
impact = original_score - new_score print(f'Feature {column_names[i]}: Impact = {impact}')
Python 的 Explainable AI

計算特徵對分群品質的影響

Feature age: Impact = 0.05199181662741281
Feature health status: Impact = 0.06046737420227638
Feature absences: Impact = 0.031290940582026694
Feature G1: Impact = -0.025746421940652353
Feature G2: Impact = -0.02578292339364119
Feature G3: Impact = -0.03163419458330158
Python 的 Explainable AI

Adjusted Rand Index(ARI)

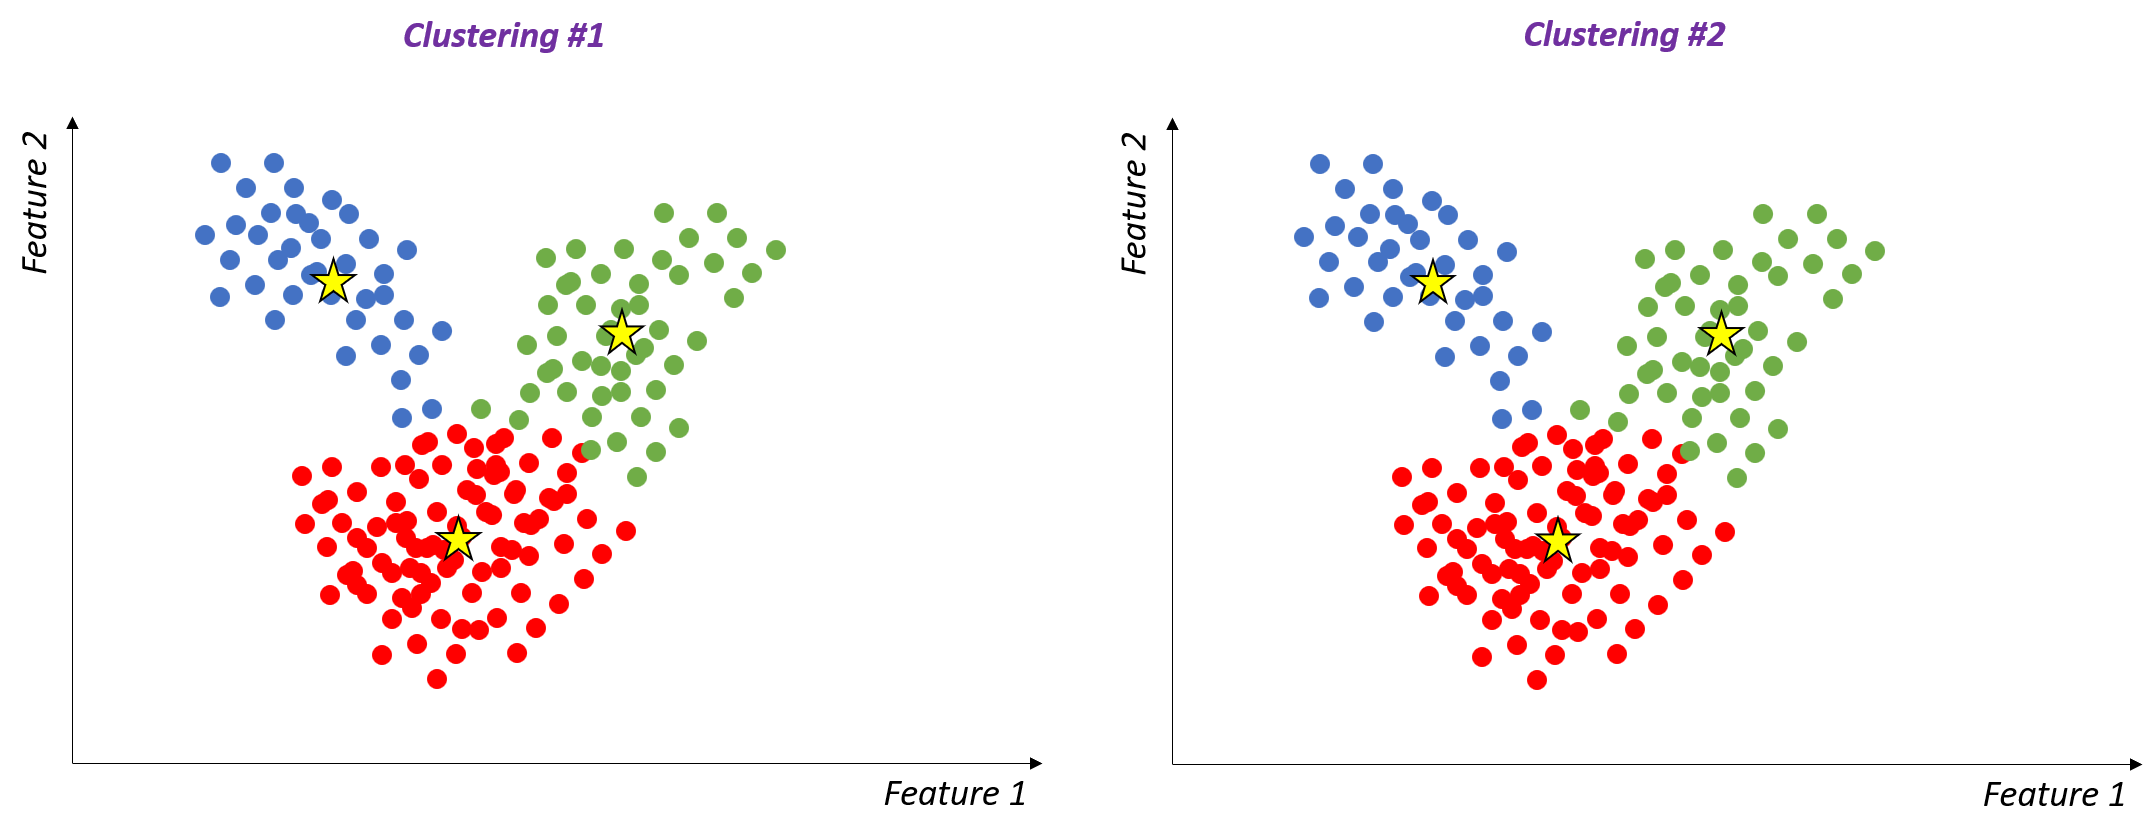
  • 衡量兩次分群標記的一致程度

顯示同一資料集的兩組相似分群結果圖片。

  • 最大 ARI = 1 → 分群完全對齊
Python 的 Explainable AI

Adjusted Rand Index(ARI)

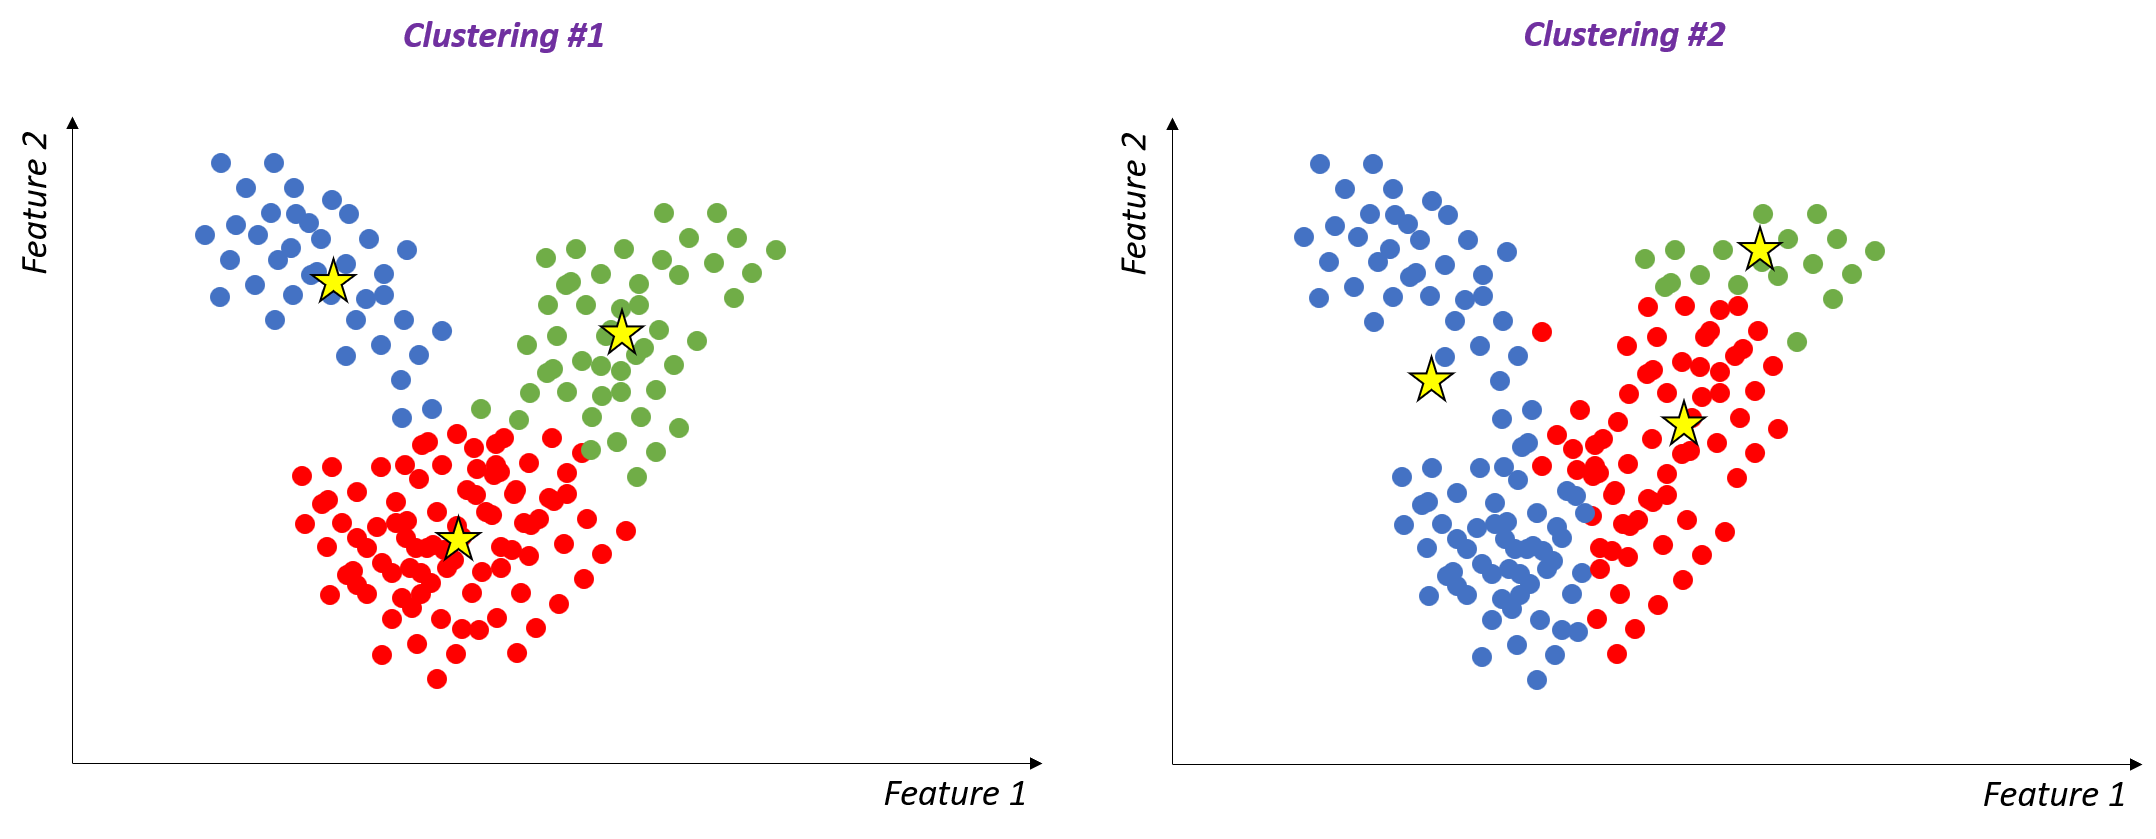
  • 衡量兩次分群標記的一致程度

顯示同一資料集的兩組不同分群結果圖片。

  • 最大 ARI = 1 → 分群完全對齊
  • ARI 越低 → 分群差異越大
Python 的 Explainable AI

分群標記的特徵重要度


  • 逐一移除特徵
  • $\text{Importance}(f) = 1 - \text{ARI (original clusters, modifed clusters)}$
  • $\text(ARI)$ 低 → $\text(1 - ARI)$ 高 → 特徵更重要
Python 的 Explainable AI

分群標記的特徵重要度

from sklearn.metrics import adjusted_rand_score

kmeans = KMeans(n_clusters=2).fit(X) original_clusters = kmeans.predict(X)
for i in range(X.shape[1]):
X_reduced = np.delete(X, i, axis=1)
reduced_clusters = kmeans.fit_predict(X_reduced)
importance = 1 - adjusted_rand_score(original_clusters, reduced_clusters) print(f'{df.columns[i]}: {importance}')
age: 0.0
health status: 0.9995376368119572
absences: 0.0
G1: 0.0
G2: 0.6204069909514572
G3: 0.6204069909514572
Python 的 Explainable AI

一起來練習吧!

Python 的 Explainable AI

Preparing Video For Download...