Regex 中的特殊字元

Python 中的正規表示法

Maria Eugenia Inzaugarat

Data Scientist

尋找樣式

尋找比對的兩種方式:
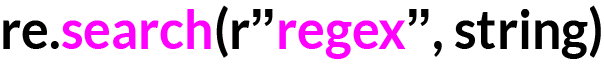
re.search(r"\d{4}", "4506 people attend the show")
<re.Match object; span=(0, 4), match='4506'>


re.search(r"\d+", "Yesterday, I saw 3 shows")
<re.Match object; span=(17, 18), match='3'>
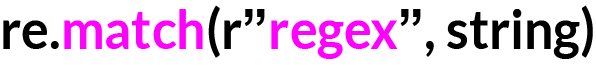
 

re.match(r"\d{4}", "4506 people attend the show")
<re.Match object; span=(0, 4), match='4506'>


re.match(r"\d+","Yesterday, I saw 3 shows")
None
Python 中的正規表示法

特殊字元

  • 比對任一字元(不含換行):.


my_links = "Just check out this link: www.amazingpics.com. It has amazing photos!"

re.findall(r"www com", my_links)
Python 中的正規表示法

特殊字元

  • 比對任一字元(不含換行):.


my_links = "Just check out this link: www.amazingpics.com. It has amazing photos!"

re.findall(r"www.+com", my_links)
['www.amazingpics.com']
Python 中的正規表示法

特殊字元

  • 字串開頭:^
my_string = "the 80s music was much better that the 90s"
re.findall(r"the\s\d+s", my_string)
['the 80s', 'the 90s']


re.findall(r"^the\s\d+s", my_string)
['the 80s']
Python 中的正規表示法

特殊字元

  • 字串結尾:$
my_string = "the 80s music hits were much better that the 90s"
re.findall(r"the\s\d+s$", my_string)
['the 90s']
Python 中的正規表示法

特殊字元

  • 跳脫特殊字元:\
my_string = "I love the music of Mr.Go. However, the sound was too loud."
print(re.split(r".\s", my_string))
['', 'lov', 'th', 'musi', 'o', 'Mr.Go', 'However', 'th', 'soun', 'wa', 'to', 'loud.']


print(re.split(r"\.\s", my_string))
['I love the music of Mr.Go', 'However, the sound was too loud.']
Python 中的正規表示法

OR 運算子

  • 字元:|
my_string = "Elephants are the world's largest land animal! I would love to see an elephant one day"
re.findall(r"Elephant|elephant", my_string)
['Elephant', 'elephant']
Python 中的正規表示法

OR 運算子

  • 字元集合:[ ]
my_string = "Yesterday I spent my afternoon with my friends: MaryJohn2 Clary3"
re.findall(r"[a-zA-Z]+\d", my_string)
['MaryJohn2', 'Clary3']
Python 中的正規表示法

OR 運算子

  • 字元集合:[ ]
my_string = "My&name&is#John Smith. I%live$in#London."
re.sub(r"[#$%&]", " ", my_string)
'My name is John Smith. I live in London.'
Python 中的正規表示法

OR 運算元

  • 字元集合:[ ]
    • ^ 轉為否定


my_links = "Bad website: www.99.com. Favorite site: www.hola.com"
re.findall(r"www[^0-9]+com", my_links)
['www.hola.com']
Python 中的正規表示法

一起來練習吧!

Python 中的正規表示法

Preparing Video For Download...