以 Python 進行信用風險建模
Michael Crabtree
Data Scientist, Ford Motor Company
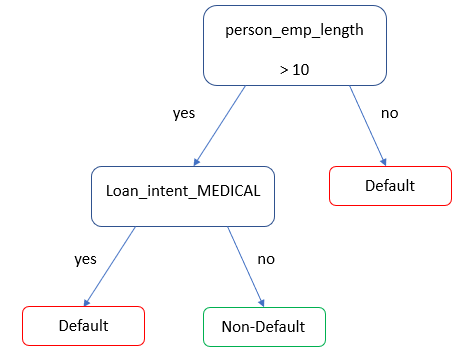
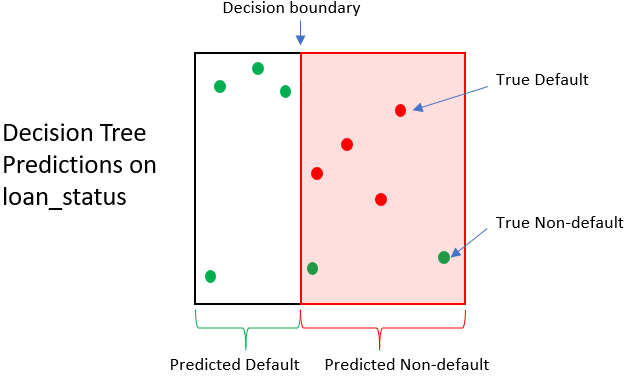
loan_status(違約機率)的簡單決策樹| Loan | True loan status | Pred. Loan Status | Loan payoff value | Selling Value | Gain/Loss |
|---|---|---|---|---|---|
| 1 | 0 | 1 | $1,500 | $250 | -$1,250 |
| 2 | 0 | 1 | $1,200 | $250 | -$950 |
xgboost Python 套件的一部分,這裡簡寫為 xgb.fit() 訓練,和邏輯斯回歸相同# Create a logistic regression model
clf_logistic = LogisticRegression()
# Train the logistic regression
clf_logistic.fit(X_train, np.ravel(y_train))
# Create a gradient boosted tree model
clf_gbt = xgb.XGBClassifier()
# Train the gradient boosted tree
clf_gbt.fit(X_train,np.ravel(y_train))
.predict() 與 .predict_proba() 預測.predict_proba() 輸出介於 0 到 1.predict() 產生 loan_status 的 1 或 0# Predict probabilities of default
gbt_preds_prob = clf_gbt.predict_proba(X_test)
# Predict loan_status as a 1 or 0
gbt_preds = clf_gbt.predict(X_test)
# gbt_preds_prob
array([[0.059, 0.940], [0.121, 0.989]])
# gbt_preds
array([1, 1, 0...])
learning_rate:越小,每一步越保守max_depth:限制樹的深度,越大越複雜xgb.XGBClassifier(learning_rate = 0.2,
max_depth = 4)
以 Python 進行信用風險建模