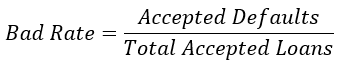以 Python 進行信用風險建模
Michael Crabtree
Data Scientist, Ford Motor Company
prob_default 值設定了門檻loan_statuspreds_df['loan_status'] = preds_df['prob_default'].apply(lambda x: 1 if x > 0.4 else 0)
| Loan | prob_default | threshold | loan_status |
|---|---|---|---|
| 1 | 0.25 | 0.4 | 0 |
| 2 | 0.42 | 0.4 | 1 |
| 3 | 0.75 | 0.4 | 1 |
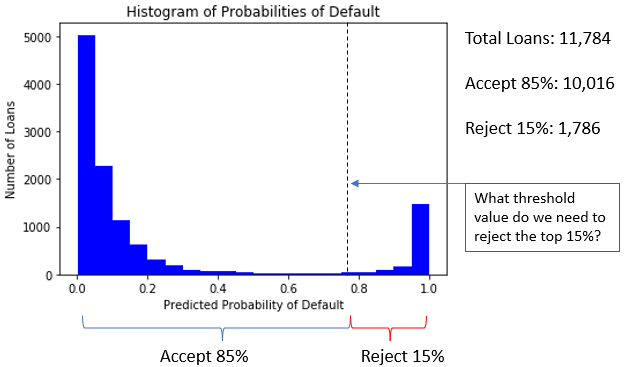
prob_default 最低的 85% 貸款import numpy as np
# Compute the threshold for 85% acceptance rate
threshold = np.quantile(prob_default, 0.85)
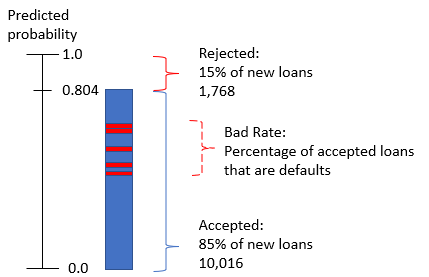
0.804
| Loan | prob_default |
Threshold | Predicted loan_status |
Accept or Reject |
|---|---|---|---|---|
| 1 | 0.65 | 0.804 | 0 | Accept |
| 2 | 0.85 | 0.804 | 1 | Reject |
loan_status 值# Compute the quantile on the probabilities of default
preds_df['loan_status'] = preds_df['prob_default'].apply(lambda x: 1 if x > 0.804 else 0)
prob_default 多落在模型校準不佳的區域#Calculate the bad rate
np.sum(accepted_loans['true_loan_status']) / accepted_loans['true_loan_status'].count()
0、違約為 1,則 sum() 即為違約筆數.count() 等同於該資料框的列數以 Python 進行信用風險建模