以 Python 進行信用風險建模
Michael Crabtree
Data Scientist, Ford Motor Company
# Model Intercept
array([-3.30582292e-10])
# Coefficients for ['loan_int_rate','person_emp_length','person_income']
array([[ 1.28517496e-09, -2.27622202e-09, -2.17211991e-05]])
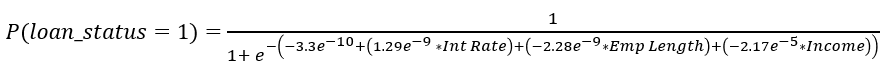
# 計算違約機率
int_coef_sum = -3.3e-10 +
(1.29e-09 * loan_int_rate) + (-2.28e-09 * person_emp_length) + (-2.17e-05 * person_income)
prob_default = 1 / (1 + np.exp(-int_coef_sum))
prob_nondefault = 1 - (1 / (1 + np.exp(-int_coef_sum)))
# Intercept
intercept = -1.02
# Coefficient for employment length
person_emp_length_coef = -0.056
person_emp_length 每增加 1 年,違約機率會下降# Intercept
intercept = -1.02
# Coefficient for employment length
person_emp_length_coef = -0.056
person_emp_length 每增加 1 年,違約機率會下降| intercept | person_emp_length | value * coef | probability of default |
|---|---|---|---|
-1.02 |
10 | (10 * -0.06) |
.17 |
-1.02 |
11 | (11 * -0.06) |
.16 |
-1.02 |
12 | (12 * -0.06) |
.15 |
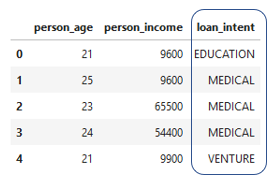
數值型:loan_int_rate、person_emp_length、person_income
非數值型:
cr_loan_clean['loan_intent']
EDUCATION
MEDICAL
VENTURE
PERSONAL
DEBTCONSOLIDATION
HOMEIMPROVEMENT
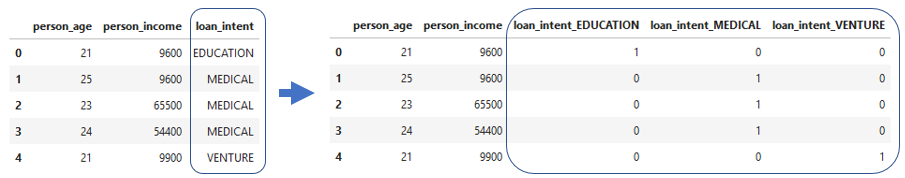
column_VALUE 中放 0 或 1pandas 的 get_dummies()# 分開數值欄位
cred_num = cr_loan.select_dtypes(exclude=['object'])
# 分開非數值欄位
cred_cat = cr_loan.select_dtypes(include=['object'])
# 僅對非數值欄位做 one-hot 編碼
cred_cat_onehot = pd.get_dummies(cred_cat)
# 合併數值欄位與 one-hot 欄位
cr_loan = pd.concat([cred_num, cred_cat_onehot], axis=1)
.predict_proba() 方法# 訓練模型
clf_logistic.fit(X_train, np.ravel(y_train))
# 用模型進行預測
clf_logistic.predict_proba(X_test)
# 機率: [[non-default, default]]
array([[0.55, 0.45]])
以 Python 進行信用風險建模