交叉驗證

Python 的模型驗證

Kasey Jones

Data Scientist

交叉驗證

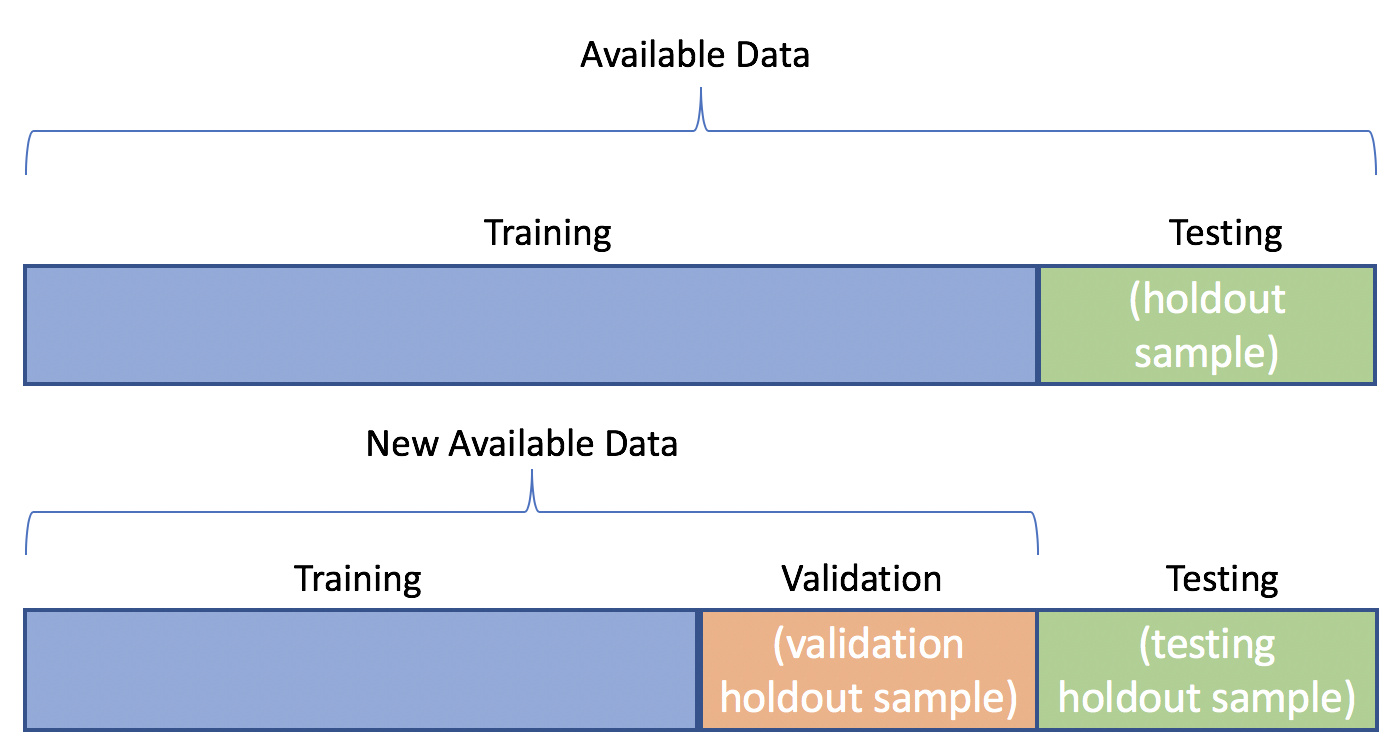
建立訓練、驗證、測試資料集,就是把整體資料切成 3 個子集。例:60% 訓練,20% 驗證,20% 測試。

Python 的模型驗證

交叉驗證

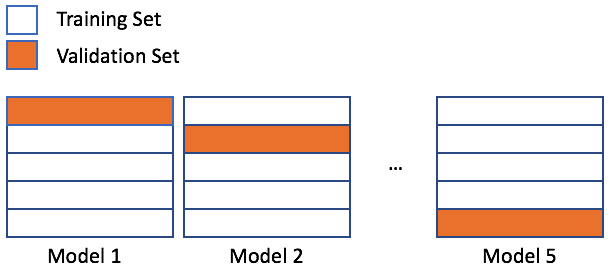
交叉驗證會多次將資料切成訓練與驗證集,而非只做一次 80:20。你可以用 5 種不同的 80:20 切法。

Python 的模型驗證

n_splits:交叉驗證分割次數

shuffle:是否在分割前隨機打散資料的布林值

random_state:隨機種子

from sklearn.model_selection import KFold

X = np.array(range(40))
y = np.array([0] * 20 + [1] * 20)

kf = KFold(n_splits=5)

splits = kf.split(X)
Python 的模型驗證
kf = KFold(n_splits=5)
splits = kf.split(X)

for train_index, test_index in splits: print(len(train_index), len(test_index))
32 8 32 8 32 8 32 8 32 8
# Print one of the index sets:
print(train_index, test_index)
[ 0  1  2  3  4  5  6  7  8  9 10 11 12 13 14 15 16 17 18 19 20 ...]
[32 33 34 35 36 37 38 39]
Python 的模型驗證
rfr = RandomForestRegressor(n_estimators=25, random_state=1111)

errors = [] for train_index, val_index in splits: X_train, y_train = X[train_index], y[train_index] X_val, y_val = X[val_index], y[val_index] rfr.fit(X_train, y_train) predictions = rfr.predict(X_val) errors.append(<some_accuracy_metric>)
print(np.mean(errors))
4.25
Python 的模型驗證

一起來練習吧!

Python 的模型驗證

Preparing Video For Download...