資料漂移

端到端機器學習

Joshua Stapleton

Machine Learning Engineer

為何需要偵測資料漂移

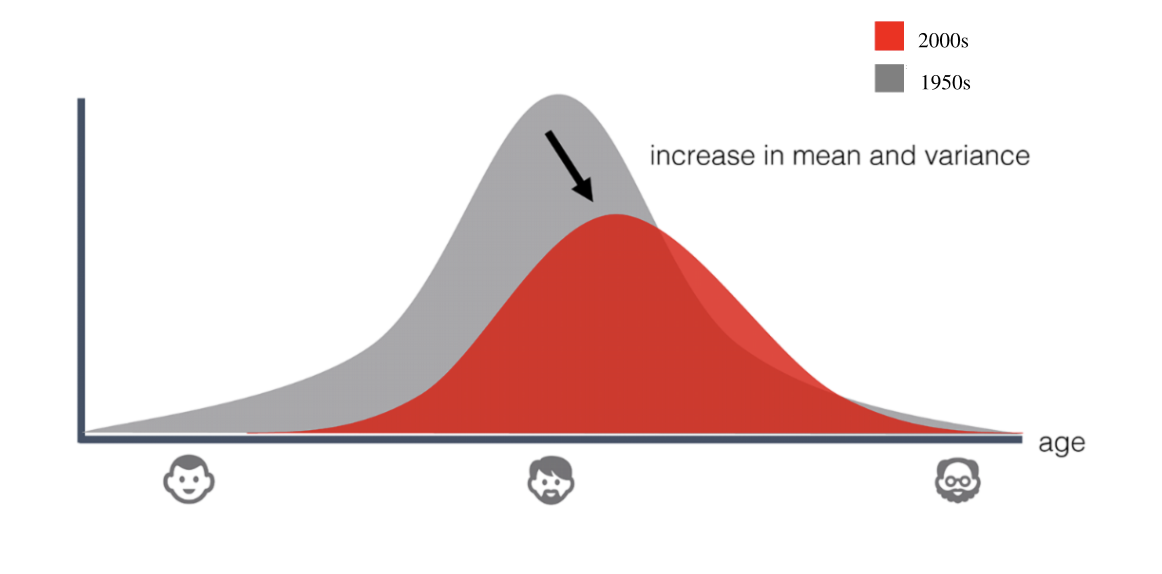
一張圖顯示不同年齡的心臟病分佈隨時間變化——如今心臟病更少,且發生年齡更高

端到端機器學習

Kolmogorov–Smirnov 檢定

  • 常用於偵測資料漂移
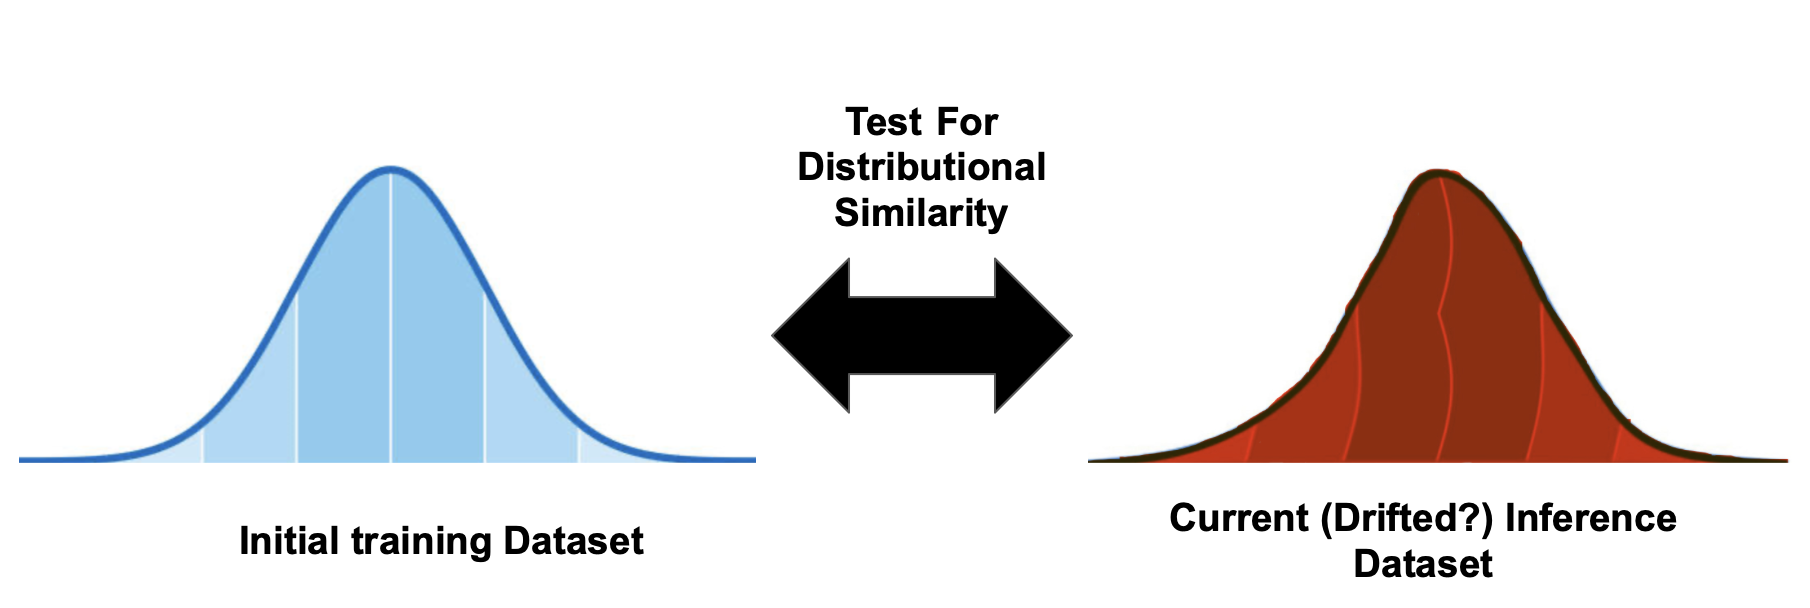
  • 比較資料集樣本差異以判斷分佈相似度

兩張圖比較初始訓練資料集與已發生資料漂移的新推論資料集之分佈差異

端到端機器學習

使用 ks_2samp() 函式

  • ks_2samp() 會回傳兩個值:檢定統計量、p-value。
  • 使用 p-value 來接受或拒絕「分佈相似」的虛無假設。
from scipy.stats import ks_2samp
# load the 1D data distribution samples for comparison
sample_1, sample_2 = training_dataset_sample, current_inference_sample
# perform the KS-test - ensure input samples are numpy arrays
test_statistic, p_value = ks_2samp(sample_1, sample_2)
if p_value < 0.05:
    print("Reject null hypothesis - data drift might be occuring")
else:
    print("Samples are likely to be from the same dataset")
端到端機器學習

修正資料漂移

更新模型以納入新資料

  • 重新訓練模型
  • 重新調整/更新模型參數

新/推論資料不足?

  • 在混合資料集上重新訓練
  • 增加新資料量

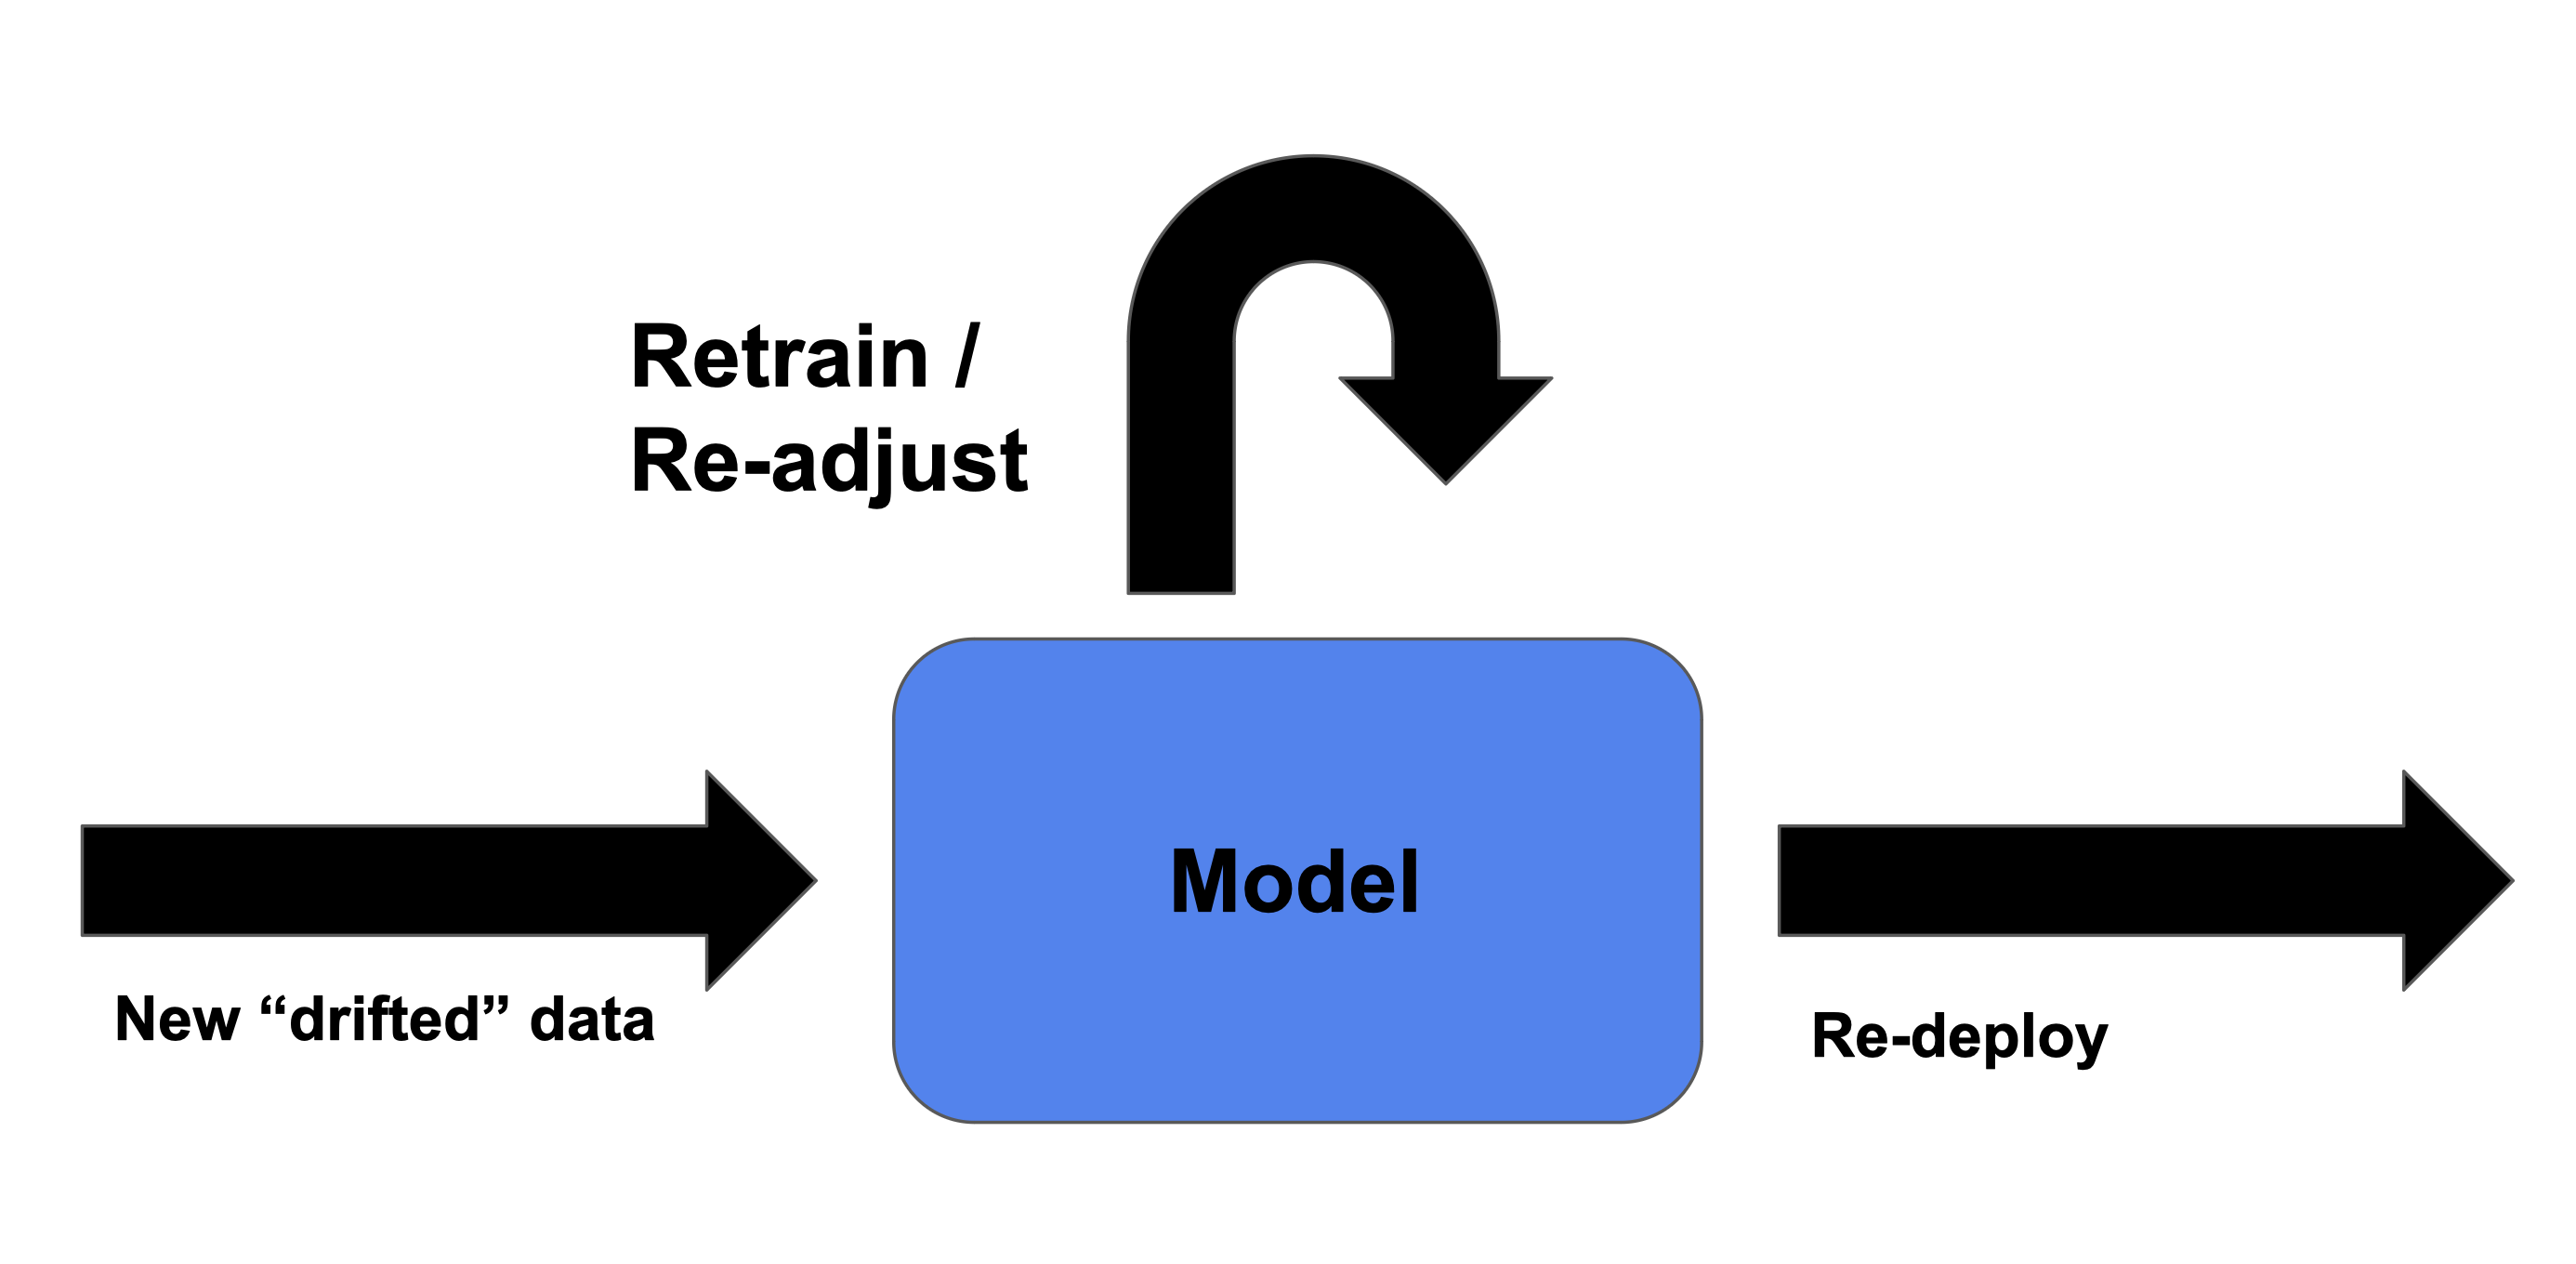
流程圖顯示對出現資料漂移的模型進行再訓練與重新部署的過程

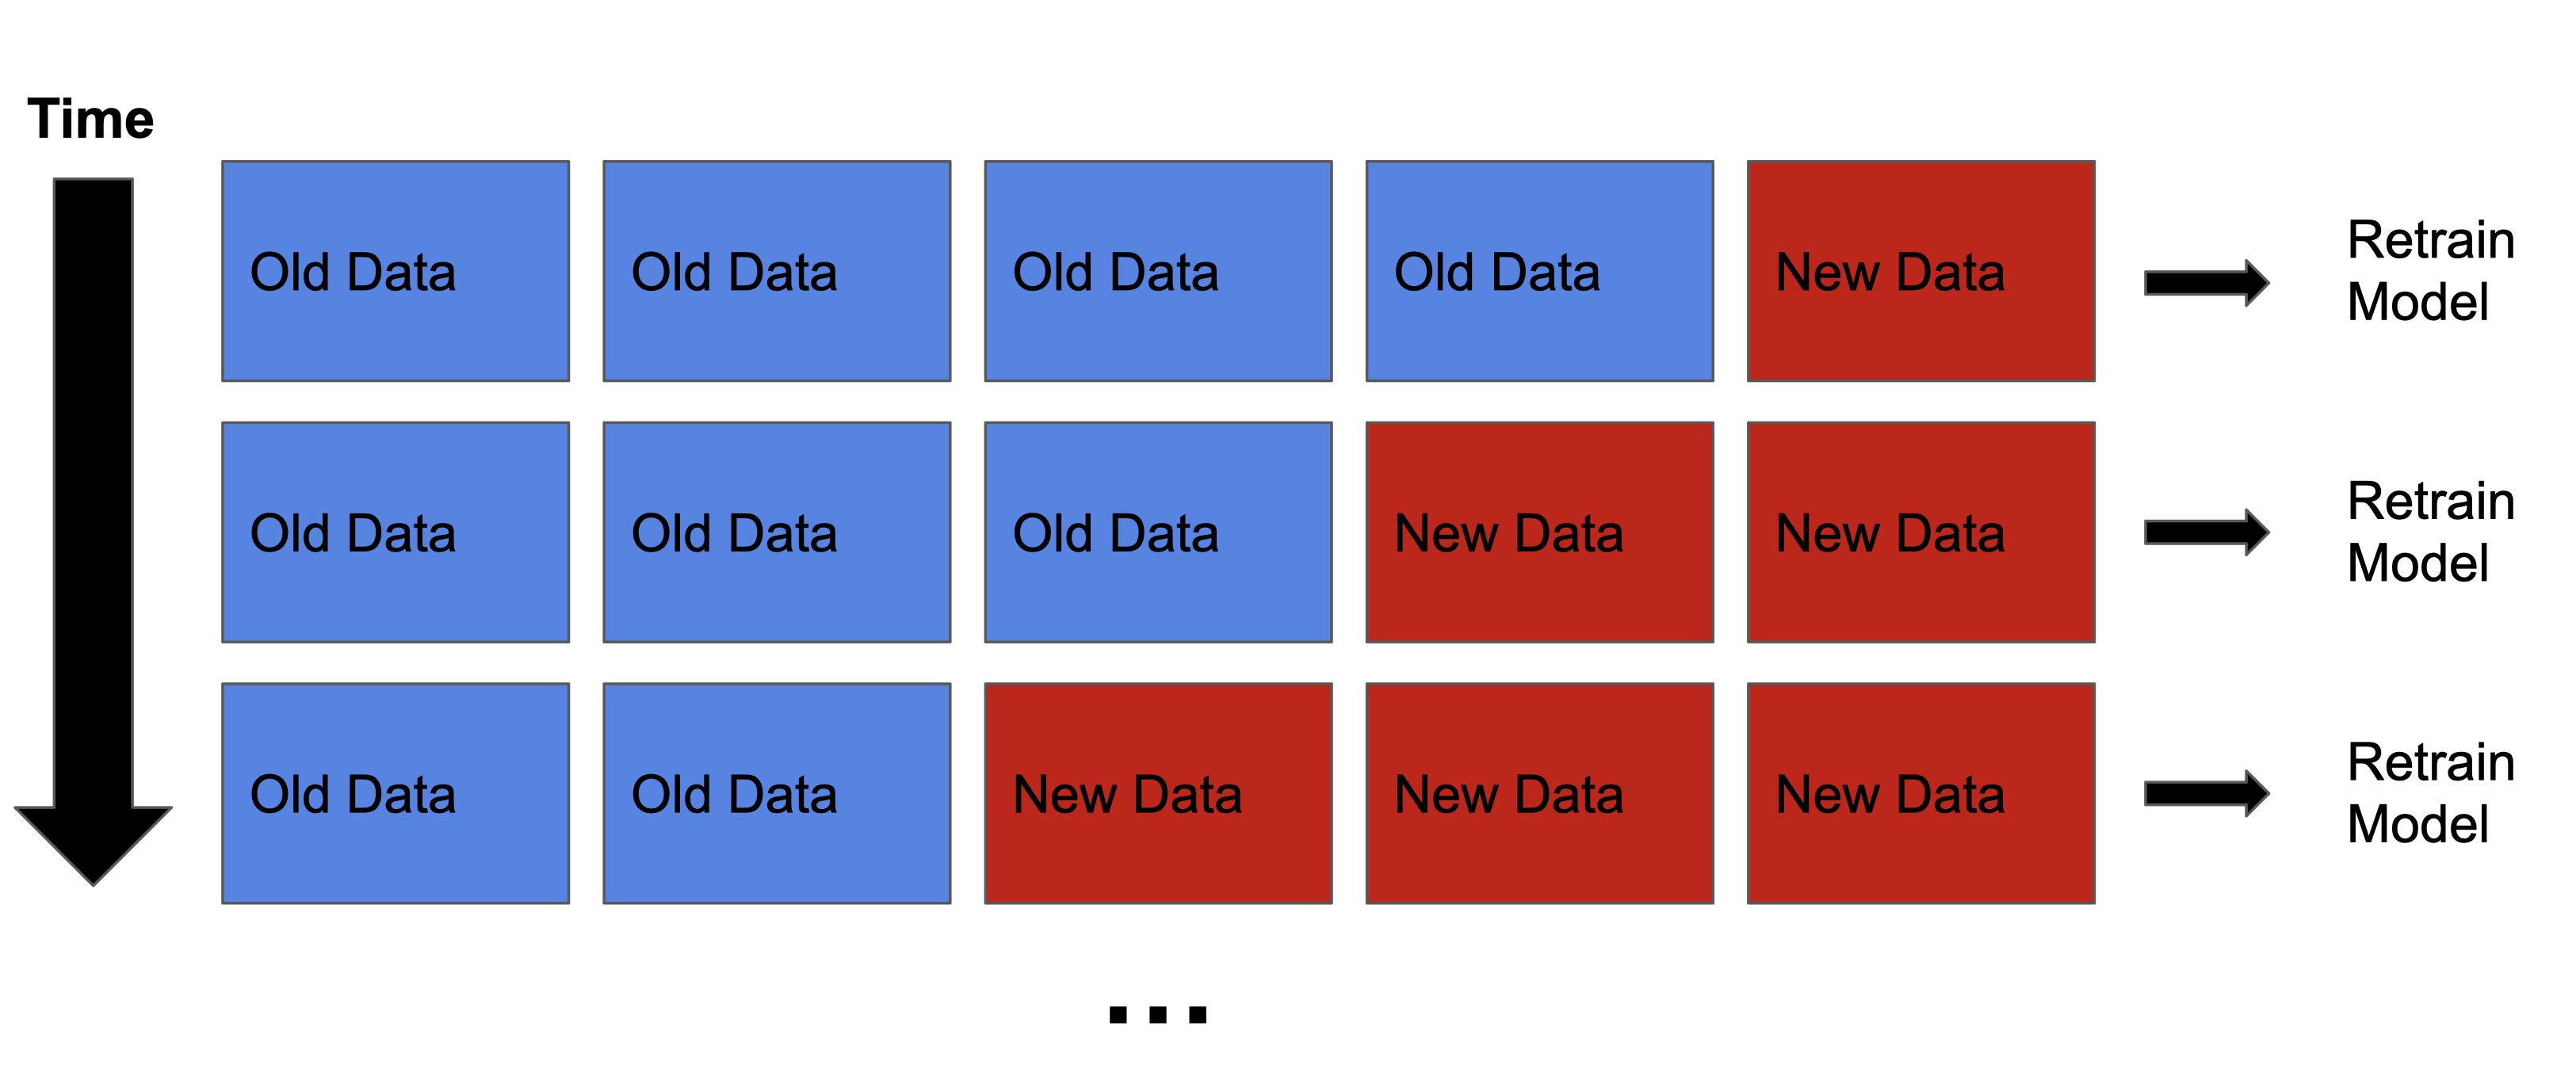
示意圖說明隨時間取得新資料後,定期以越來越多的新資料再訓練模型

端到端機器學習

更多偵測與修正資料漂移的資源

端到端機器學習

一起來練習吧!

端到端機器學習

Preparing Video For Download...