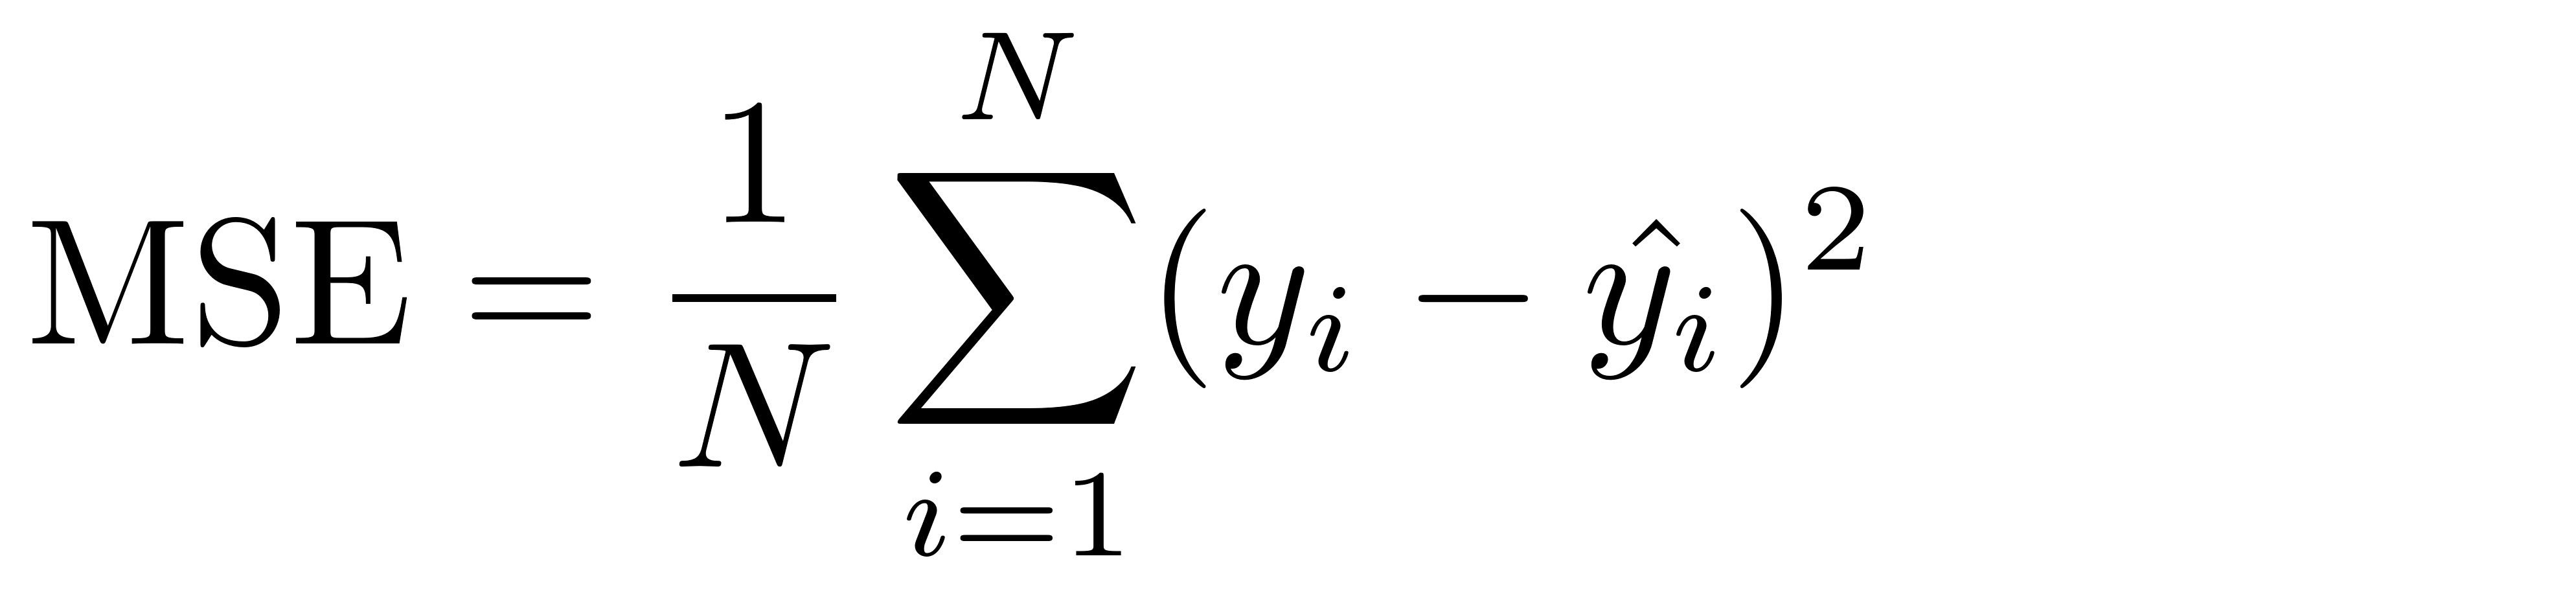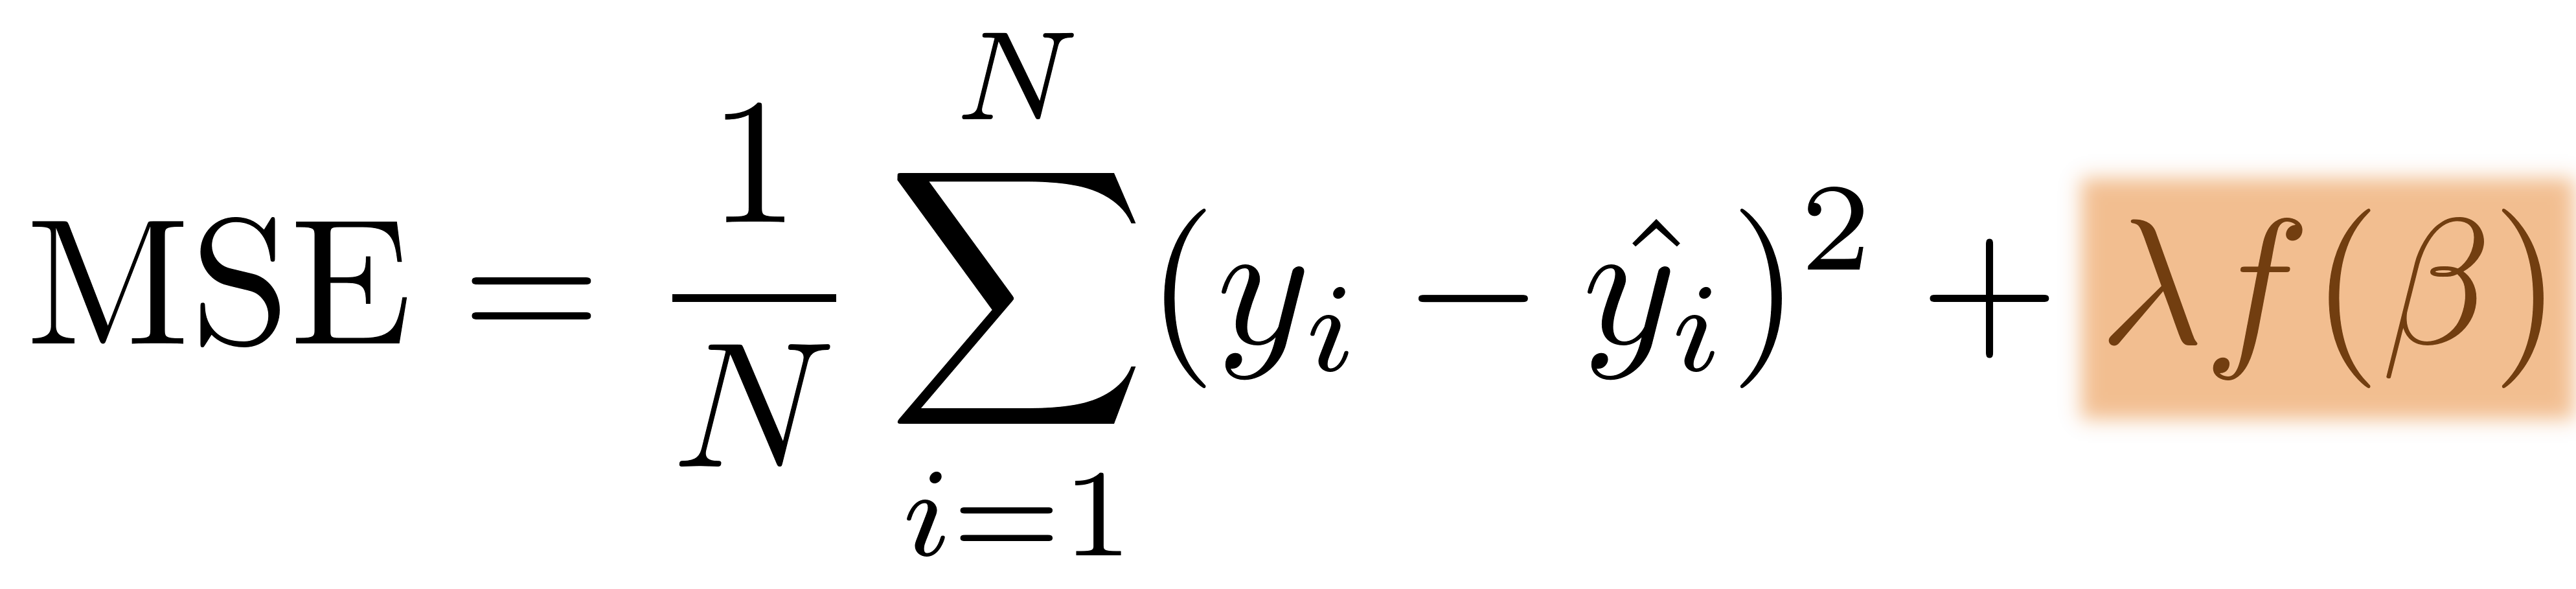使用 PySpark 的機器學習
Andrew Collier
Data Scientist, Fathom Data


線性迴歸的目標是最小化 MSE。

線性迴歸的目標是最小化 MSE。

加入依賴係數的「正則化」項。
在損失函式中加入額外的「正則化」項。
正則化項可以是
也可以混合 Lasso 與 Ridge 迴歸。
正則化強度由參數 $\lambda$ 決定:
assembler = VectorAssembler(inputCols=[
'mass', 'cyl', 'type_dummy', 'density_line', 'density_quad', 'density_cube'
], outputCol='features')
cars = assembler.transform(cars)
+-----------------------------------------------------------------------------+-----------+
|features |consumption|
+-----------------------------------------------------------------------------+-----------+
|[1451.0,6.0,1.0,0.0,0.0,0.0,0.0,303.8743455497,63.63860639785,13.32745683724]|9.05 |
|[1129.0,4.0,0.0,0.0,1.0,0.0,0.0,244.2137140385,52.82580879050,11.42673778726]|6.53 |
|[1399.0,4.0,0.0,0.0,1.0,0.0,0.0,307.6753903672,67.66557958374,14.88136784335]|7.84 |
|[1147.0,4.0,0.0,1.0,0.0,0.0,0.0,264.1031545014,60.81122599620,14.00212433714]|7.84 |
+-----------------------------------------------------------------------------+-----------+
對訓練資料擬合(標準)線性迴歸模型。
regression = LinearRegression(labelCol='consumption').fit(cars_train)
# 測試資料的 RMSE
0.708699086182001
檢視係數:
regression.coefficients
DenseVector([-0.012, 0.174, -0.897, -1.445, -0.985, -1.071, -1.335, 0.189, -0.780, 1.160])
# alpha = 0 | lambda = 0.1 -> Ridge
ridge = LinearRegression(labelCol='consumption', elasticNetParam=0, regParam=0.1)
ridge.fit(cars_train)
# RMSE
0.724535609745491
# Ridge 係數
DenseVector([ 0.001, 0.137, -0.395, -0.822, -0.450, -0.582, -0.806, 0.008, 0.029, 0.001])
# 線性迴歸係數
DenseVector([-0.012, 0.174, -0.897, -1.445, -0.985, -1.071, -1.335, 0.189, -0.780, 1.160])
# alpha = 1 | lambda = 0.1 -> Lasso
lasso = LinearRegression(labelCol='consumption', elasticNetParam=1, regParam=0.1)
lasso.fit(cars_train)
# RMSE
0.771988667026998
# Lasso 係數
DenseVector([ 0.0, 0.0, 0.0, -0.056, 0.0, 0.0, 0.0, 0.026, 0.0, 0.0])
# Ridge 係數
DenseVector([ 0.001, 0.137, -0.395, -0.822, -0.450, -0.582, -0.806, 0.008, 0.029, 0.001])
# 線性迴歸係數
DenseVector([-0.012, 0.174, -0.897, -1.445, -0.985, -1.071, -1.335, 0.189, -0.780, 1.160])
使用 PySpark 的機器學習