使用 spaCy 衡量語意相似度

使用 spaCy 的自然語言處理

Azadeh Mobasher

Principal Data Scientist

語意相似度方法


  • 分析文本找出相似性的流程
  • 將文本分到預先定義的類別,或偵測相關文本
  • 相似度分數衡量兩段文本的相似程度


What is the cheapest flight from Boston to Seattle?
Which airline serves Denver, Pittsburgh and Atlanta?
What kinds of planes are used by American Airlines?
使用 spaCy 的自然語言處理

相似度分數

  • 定義在文本上的度量
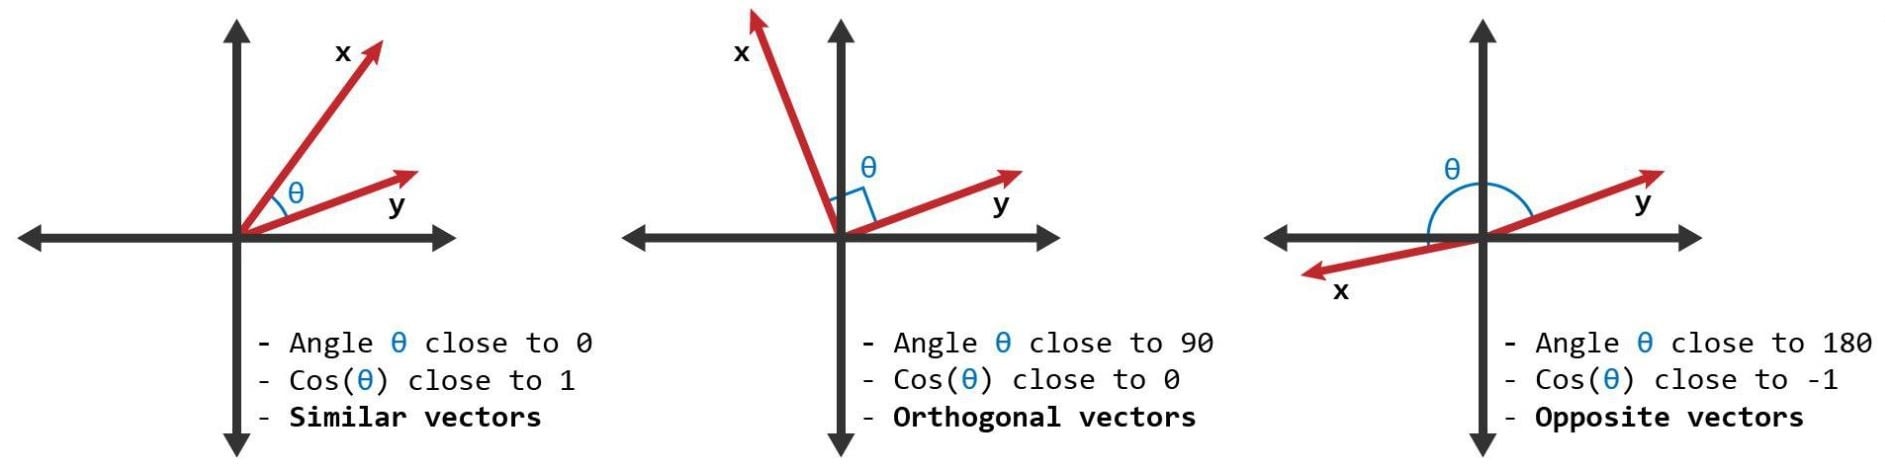
  • 衡量相似度可用餘弦相似度詞向量
  • 餘弦相似度介於 0 到 1 之間

餘弦相似度與向量

使用 spaCy 的自然語言處理

Token 相似度

  • spaCy 可計算 Token 物件之間的相似度分數
nlp = spacy.load("en_core_web_md")
doc1 = nlp("We eat pizza")
doc2 = nlp("We like to eat pasta")

token1 = doc1[2] token2 = doc2[4] print(f"Similarity between {token1} and {token2} = ", round(token1.similarity(token2), 3))
>>> Similarity between pizza and pasta =  0.685
使用 spaCy 的自然語言處理

Span 相似度

  • spaCy 可計算兩個 Span 物件的語意相似度
doc1 = nlp("We eat pizza")
doc2 = nlp("We like to eat pasta")

span1 = doc1[1:]
span2 = doc2[1:]

print(f"Similarity between \"{span1}\" and \"{span2}\" = ", round(span1.similarity(span2), 3))
>>> Similarity between "eat pizza" and "like to eat pasta" =  0.588
print(f"Similarity between \"{doc1[1:]}\" and \"{doc2[3:]}\" = ",
        round(doc1[1:].similarity(doc2[3:]), 3))
>>> Similarity between "eat pizza" and "eat pasta" =  0.936
使用 spaCy 的自然語言處理

Doc 相似度

  • spaCy 可計算兩個文件的相似度分數
nlp = spacy.load("en_core_web_md")

doc1 = nlp("I like to play basketball")
doc2 = nlp("I love to play basketball")
print("Similarity score :", round(doc1.similarity(doc2), 3))
>>> Similarity score : 0.975
  • 高餘弦相似度代表語意高度相近
  • Doc 向量預設為詞向量的平均值
使用 spaCy 的自然語言處理

句子相似度

  • spaCy 可找出與指定關鍵字相關的內容
  • 尋找與關鍵字「price」相近的客服問題:
sentences = nlp("What is the cheapest flight from Boston to Seattle? 
                 Which airline serves Denver, Pittsburgh and Atlanta? 
                 What kinds of planes are used by American Airlines?")

keyword = nlp("price")

for i, sentence in enumerate(sentences.sents): print(f"Similarity score with sentence {i+1}: ", round(sentence.similarity(keyword), 5))
>>> Similarity score with sentence 1:  0.26136
Similarity score with sentence 2:  0.14021
Similarity score with sentence 3:  0.13885
使用 spaCy 的自然語言處理

一起來練習吧!

使用 spaCy 的自然語言處理

Preparing Video For Download...