零樣本影片分類

使用 Hugging Face 的多模態模型

James Chapman

Curriculum Manager, DataCamp

零樣本影片分類


商業情境:

  • 競品廣告帶來更多銷售
  • 我們的競品在廣告中更正向嗎?


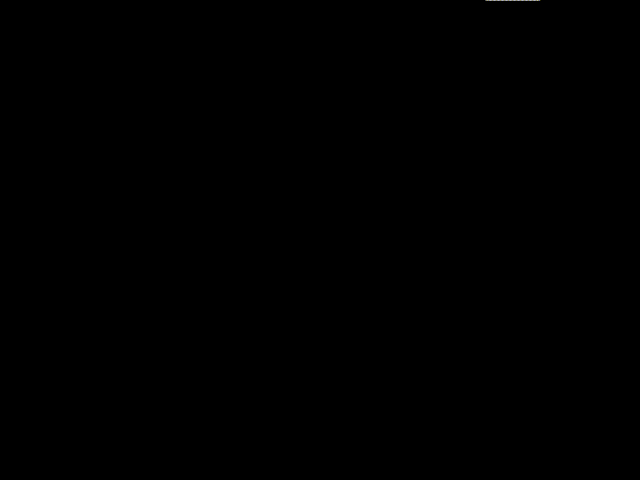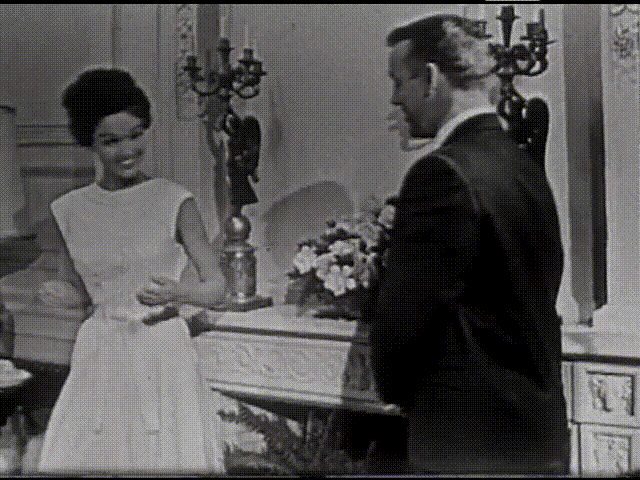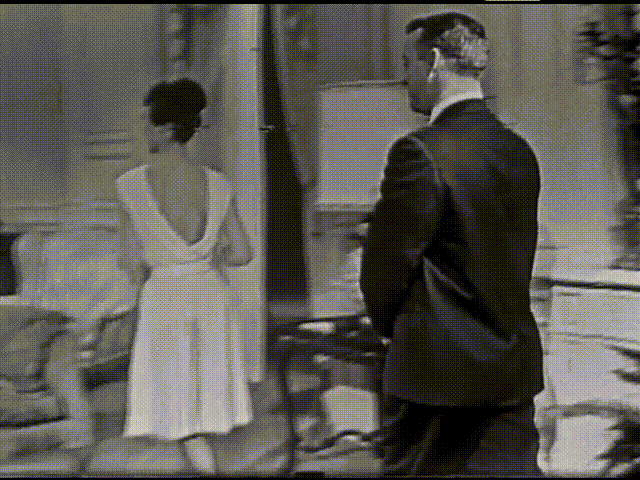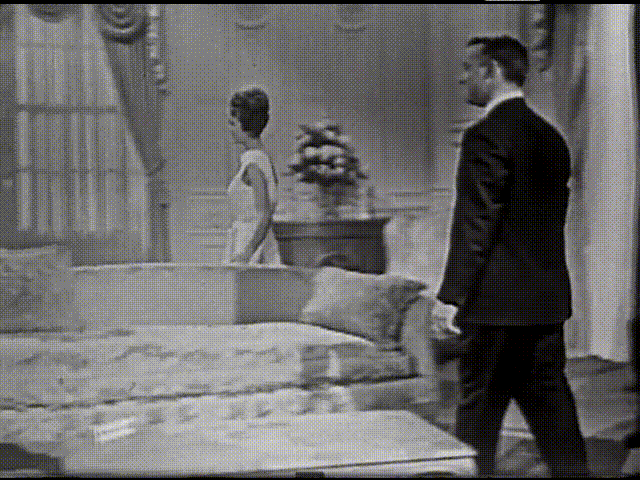
1950 年代的牙膏廣告

1 https://repository.duke.edu/dc/adviews/dmbb37204
使用 Hugging Face 的多模態模型

CLAP

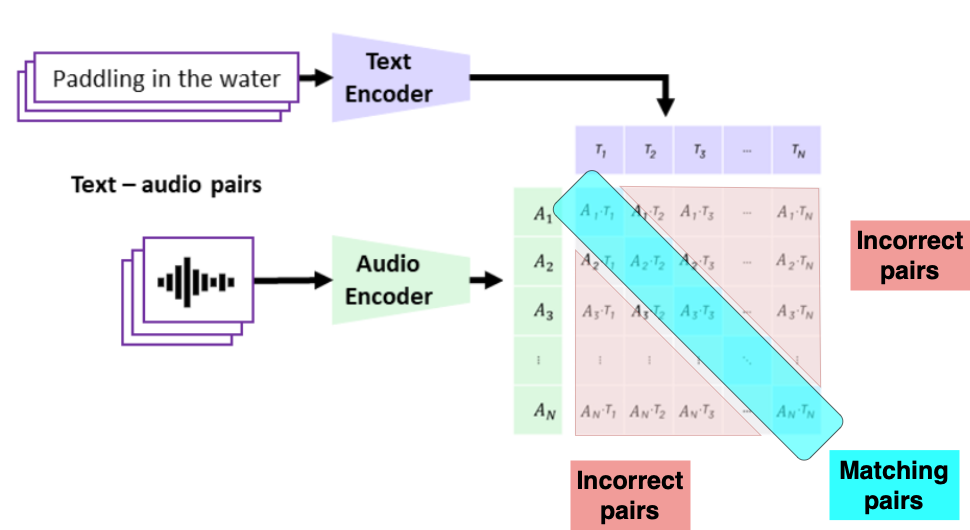
  • 對比式語言與音訊預訓練(Contrastive Language Audio Pretraining)
  • 類似用於訓練 CLIP 的方法
    • 分開的文字編碼器與音訊編碼器
  • 633k 組音訊+描述配對
  • 對比式預訓練對齊音訊與文字的嵌入

CLAP 圖示:對齊嵌入的配對

1 https://arxiv.org/html/2211.06687v4
使用 Hugging Face 的多模態模型

方法:多模態 ZSL

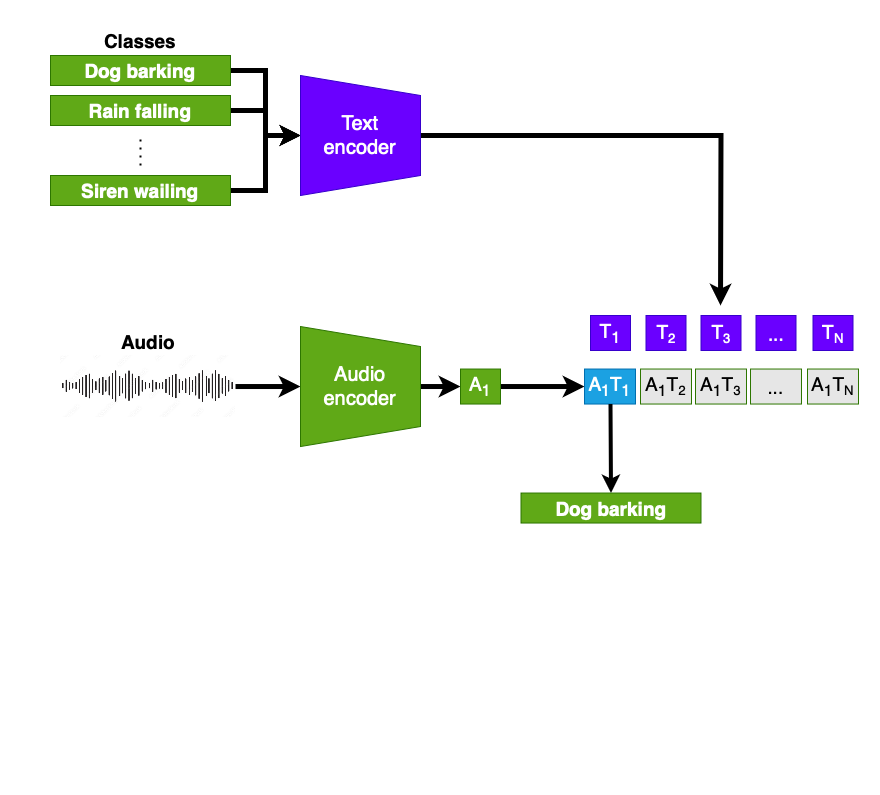
使用 CLAP 的「零樣本學習」

晚期融合方法第 1 部分:CLAP 特寫

1 https://arxiv.org/html/2310.02298v3
使用 Hugging Face 的多模態模型

方法:多模態 ZSL

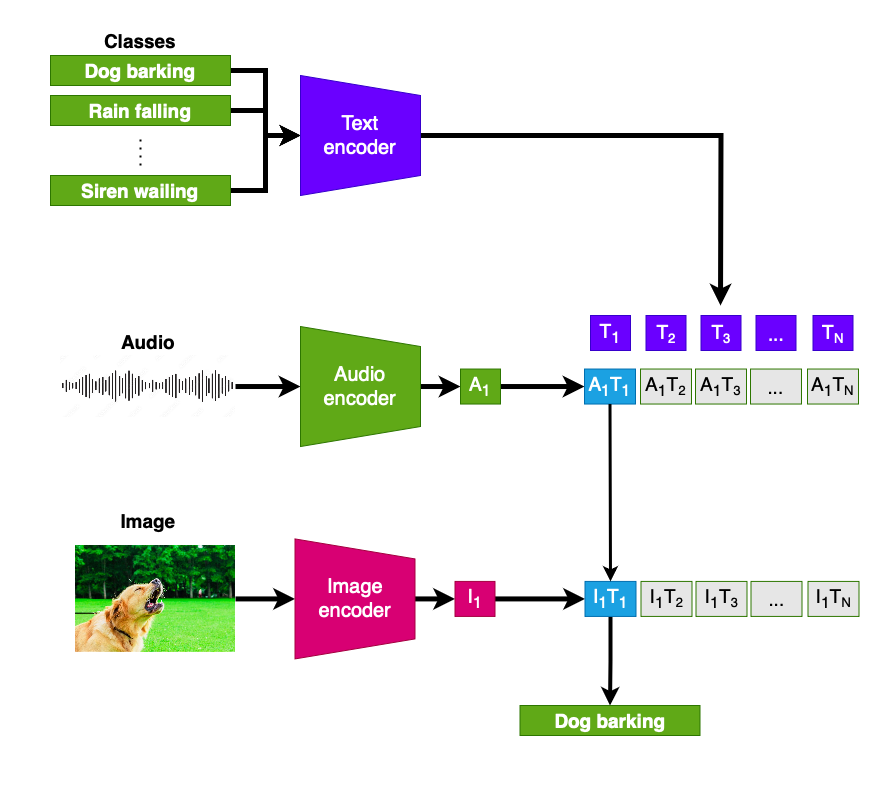
使用 CLAP 的「零樣本學習」

+ 使用 CLIP 的零樣本學習

  • 共同的文字類別
  • 合併 CLIP 與 CLAP 的機率

晚期融合方法第 2 部分:CLIP+CLAP 特寫

使用 Hugging Face 的多模態模型

影片與音訊

moviepy 分離 .mp4 的音訊與影像串流:

from moviepy.editor import VideoFileClip
from moviepy.video.io.ffmpeg_tools import ffmpeg_extract_subclip

ffmpeg_extract_subclip("advert.mp4", 0, 5, "advert_5s.mp4")


video = VideoFileClip("advert_5s.mp4")
audio = video.audio
audio.write_audiofile("advert_5s.mp3")
使用 Hugging Face 的多模態模型

準備音訊與影片

from decord import VideoReader
from PIL import Image
video_reader = VideoReader(video_path)
video = video_reader.get_batch(range(20)).asnumpy()
video = video[:, :, :, ::-1]
video = [Image.fromarray(frame) for frame in video]


from datasets import Dataset, Audio audio_dataset = Dataset.from_dict({"audio": [audio_path]}).cast_column("audio", Audio()) audio_sample = audio_dataset[0]["audio"]["array"]
使用 Hugging Face 的多模態模型

影片預測

emotions = ["joy", "fear", "anger", "sadness", "disgust", "surprise", "neutral"]


image_class = pipeline(model="openai/clip-vit-large-patch14", task="zero-shot-image-classification")
predictions = image_classifier(video, candidate_labels=emotions) scores = [ {l['label']: l['score'] for l in prediction} for prediction in predictions ]
avg_image_scores = {emotion: sum([s[emotion] for s in scores])/len(scores) for emotion in emotions} print(f"Average scores: {avg_image_scores}")
Average scores: {'joy': 0.10063326267991216, 'fear': 0.0868348691612482, ...}
使用 Hugging Face 的多模態模型

音訊預測與合併

audio_class = pipeline(model="laion/clap-htsat-unfused", 
                       task="zero-shot-audio-classification")


audio_scores = audio_class(audio_sample, candidate_labels=emotions) audio_scores = {l['label']: l['score'] for l in audio_scores}
multimodal_scores = {emotion: (avg_image_scores[emotion] + audio_scores[emotion])/2 for emotion in emotions} print(f"Multimodal scores: {multimodal_scores}")
Multimodal scores: {'joy': 0.3109628591220826, 'fear': 0.09013736313208938, 
'anger': 0.011454355076421053, 'sadness': 0.06018101833760738, 'disgust': 0.07207315033301712, 
'surprise': 0.252118631079793, 'neutral': 0.2030726027674973}
使用 Hugging Face 的多模態模型

一起來練習吧!

使用 Hugging Face 的多模態模型

Preparing Video For Download...