多模態情感分析

使用 Hugging Face 的多模態模型

James Chapman

Curriculum Manager, DataCamp

Vision Language Models(VLM)
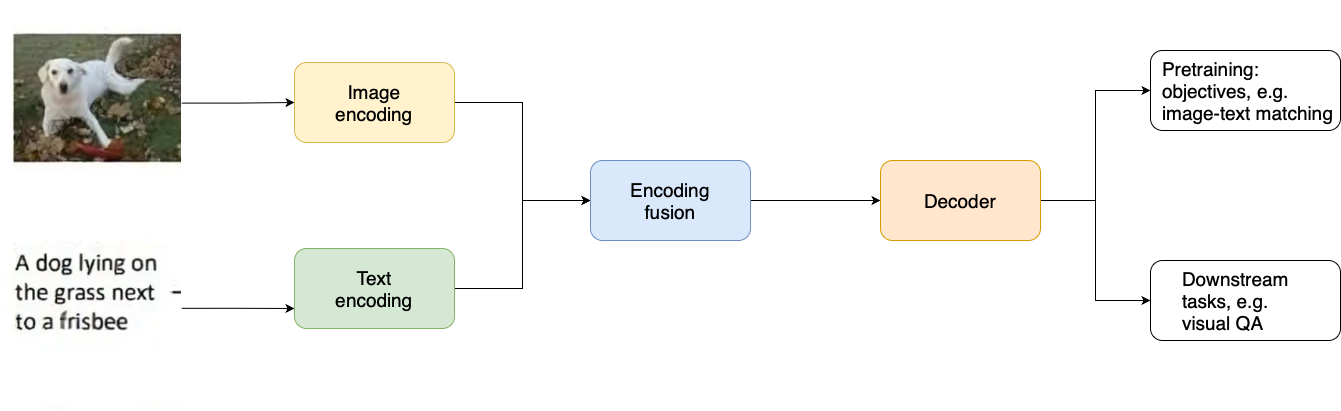
視覺語言模型的一般架構示意圖

  • 影像與文字分別編碼
  • 特徵融合
  • 建立共享表徵
    • 一個模型支援多任務
使用 Hugging Face 的多模態模型

視覺推理任務

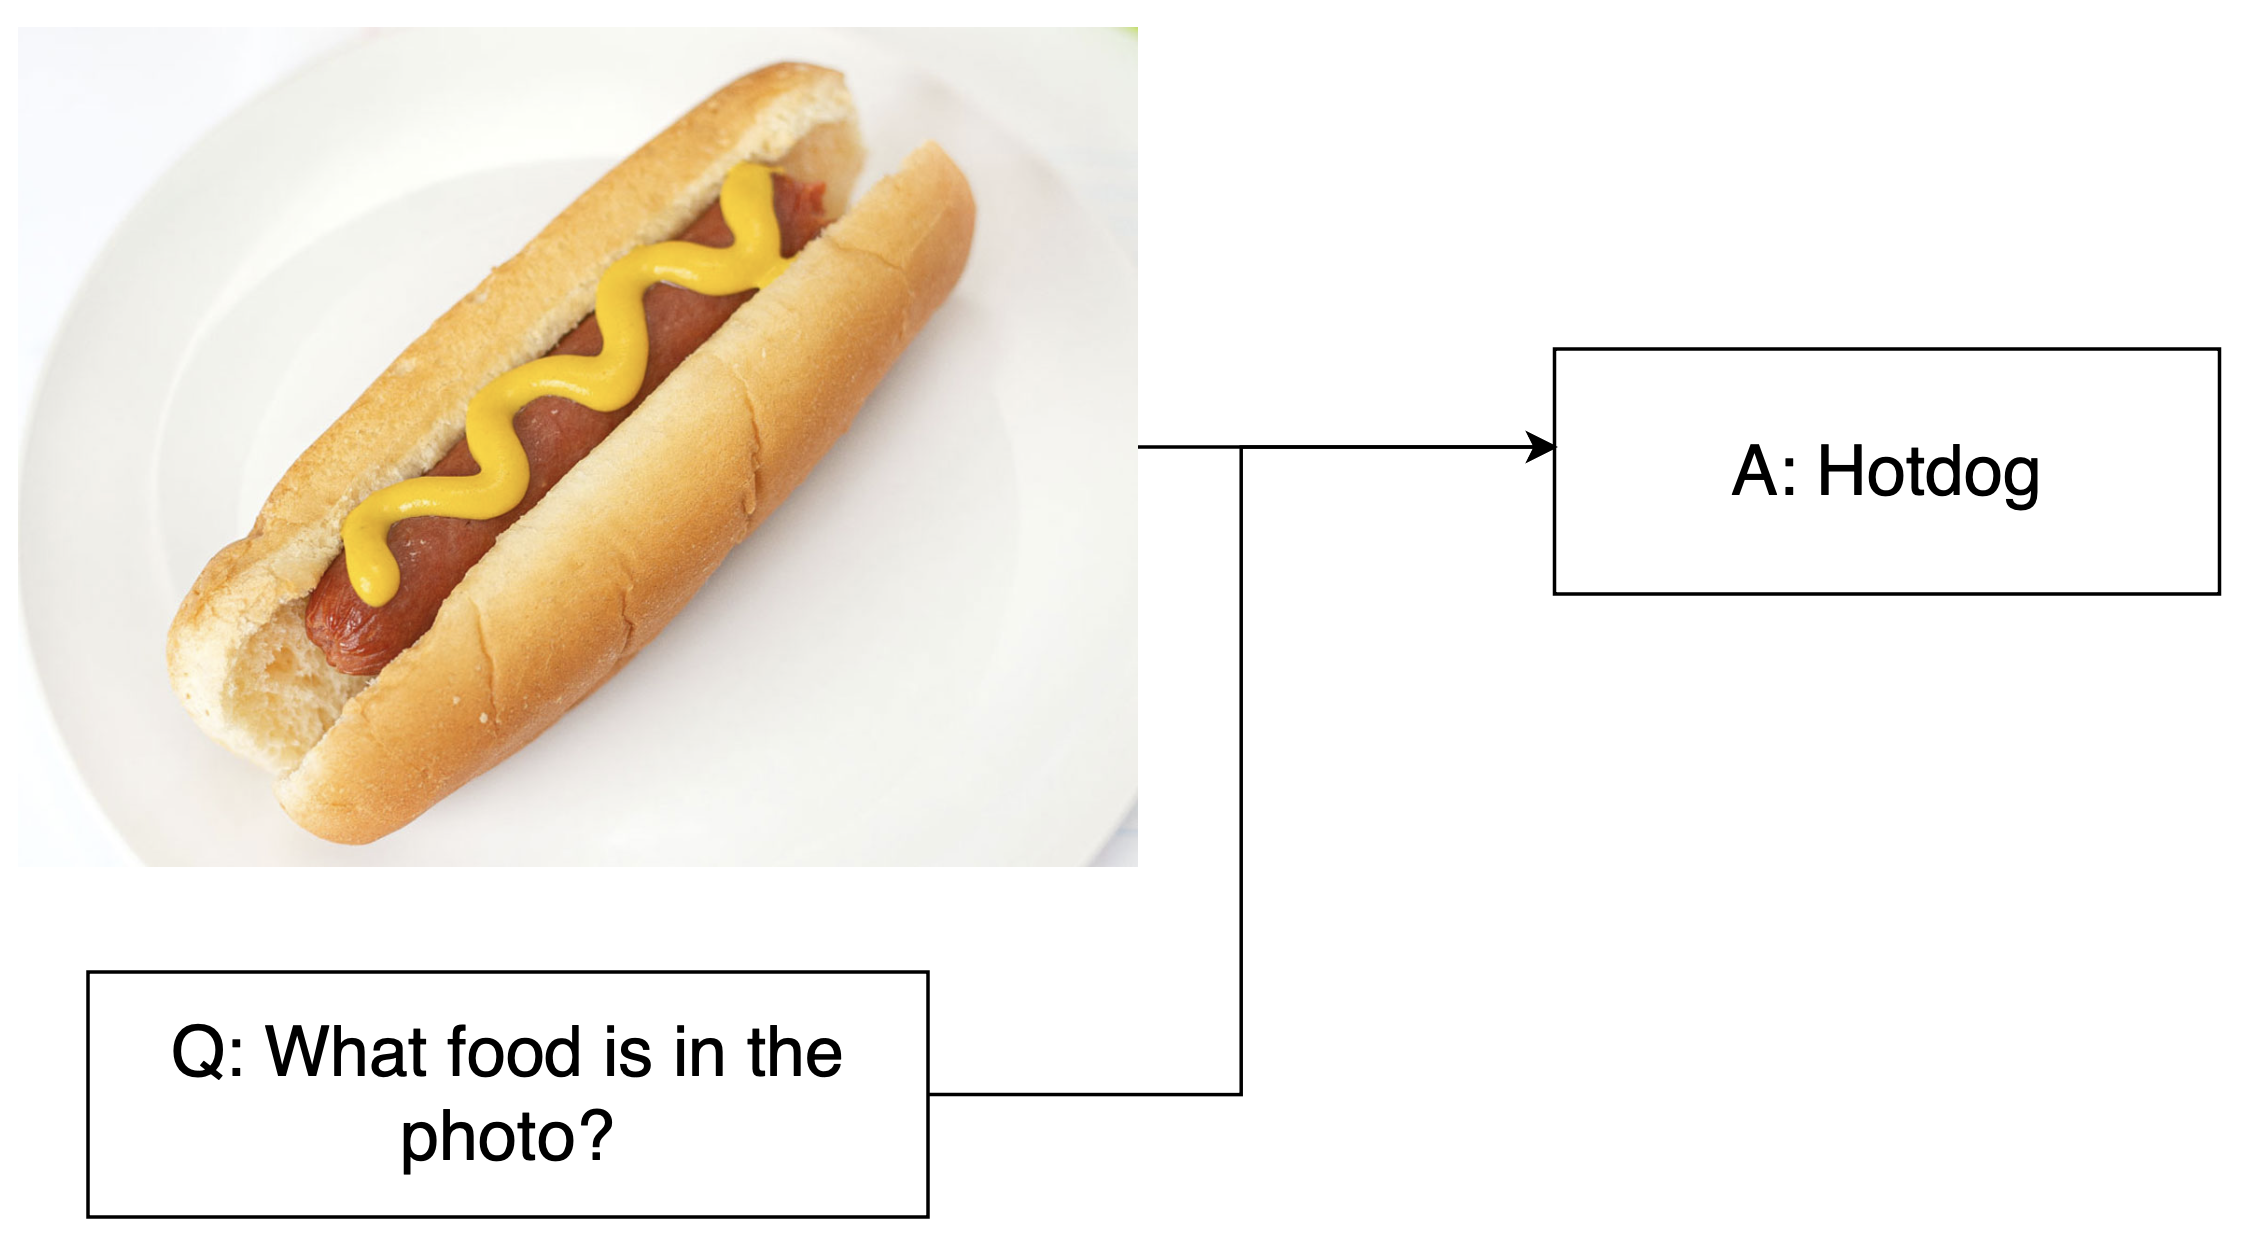
  • VQA:影像+問題 → 直接回答影像內容

熱狗範例的視覺問答

1 https://arxiv.org/pdf/1505.00468
使用 Hugging Face 的多模態模型

視覺推理任務

  • VQA:影像+問題 → 直接回答影像內容
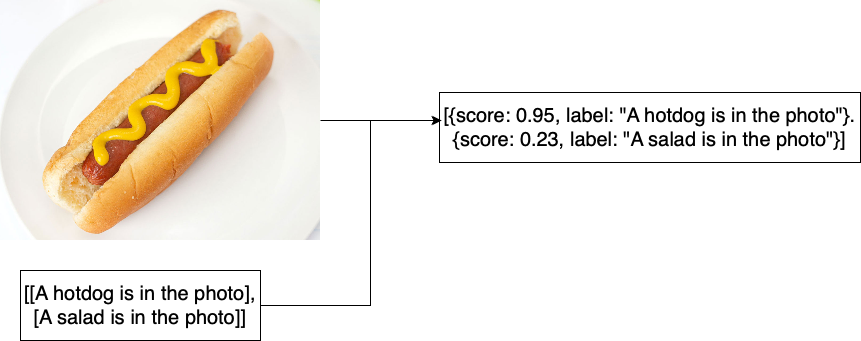
  • Matching:影像+陳述 → 判斷真/假

以熱狗與敘述進行配對的範例

使用 Hugging Face 的多模態模型

視覺推理任務

  • VQA:影像+問題 → 直接回答影像內容
  • Matchings:影像+陳述 → 判斷真/假
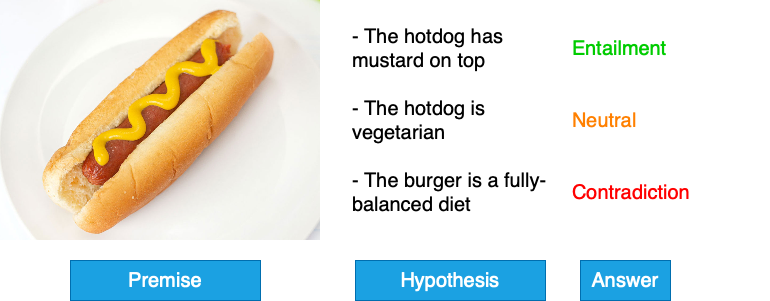
  • Entailment:影像+對比文本 → 檢查語意關係

以熱狗示範蘊涵:包含、無關、矛盾的假設

使用 Hugging Face 的多模態模型

情境:股價影響

from datasets import load_dataset
dset = "RealTimeData/bbc_news_alltime"
dataset = load_dataset(dset, '2017-01', 
                       split="train")


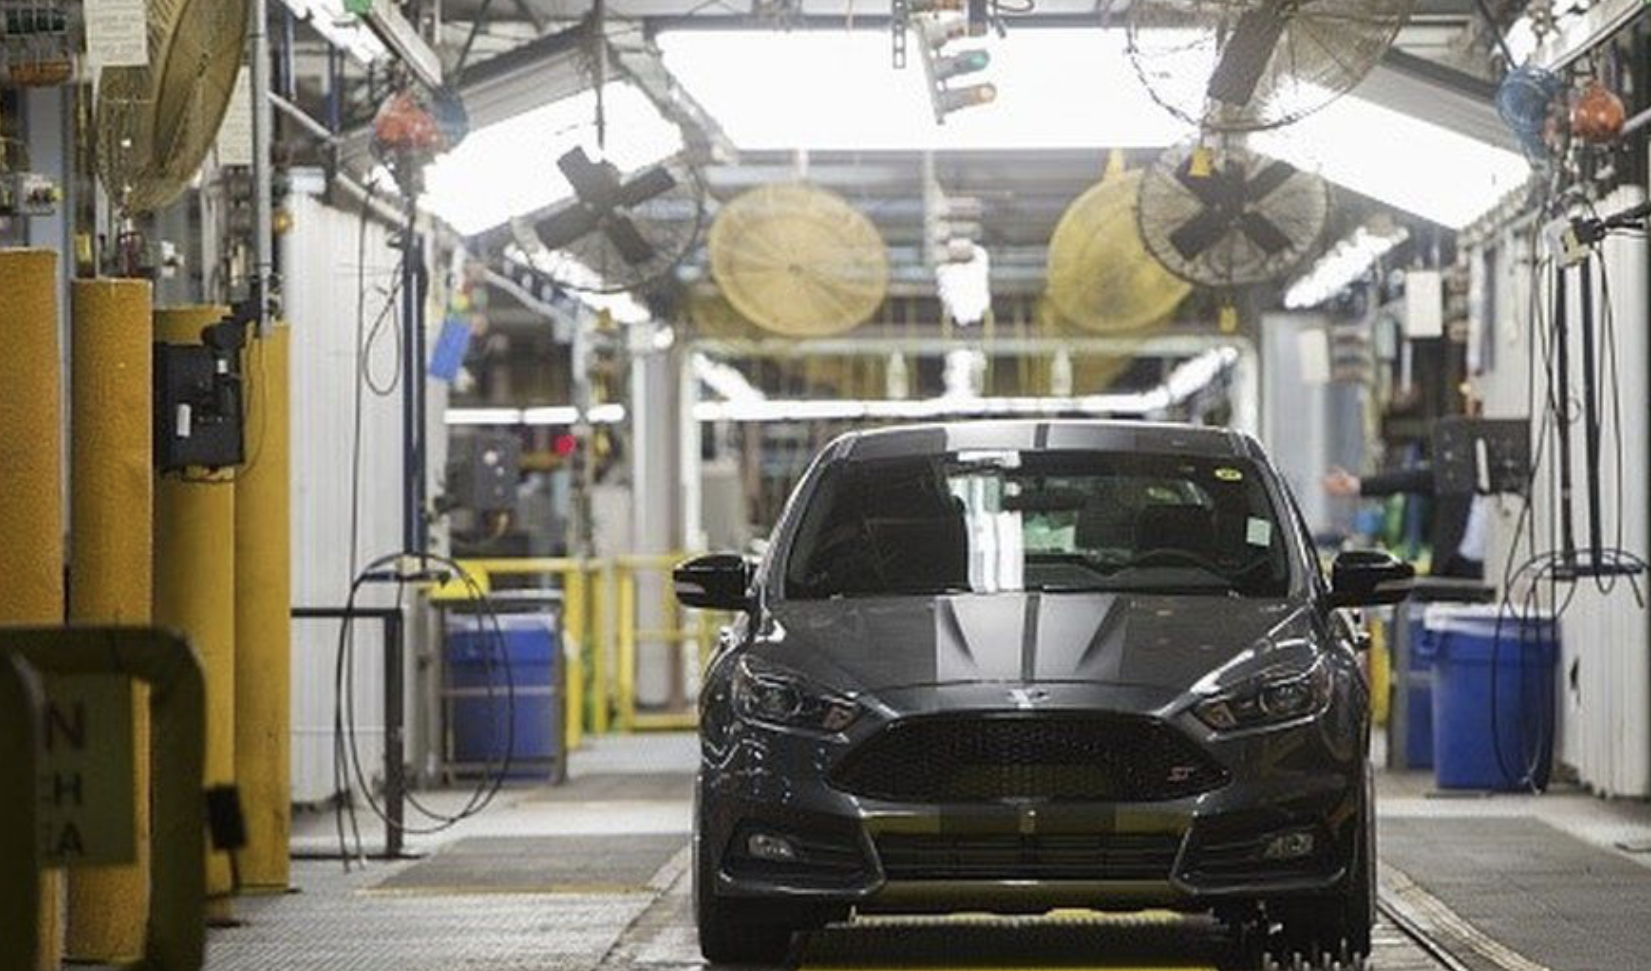
image = dataset[87]["top_image"] content = dataset[87]["content"] print(content)
'Ford\'s decision to cancel a $1.6bn 
investment in Mexico and 
invest an extra $700m in Michigan ...

新聞文章中的汽車生產投資相關圖片

使用 Hugging Face 的多模態模型

Qwen 2 VLMs

from transformers import Qwen2VLForConditionalGeneration
from qwen_vl_utils import process_vision_info


vl_model = Qwen2VLForConditionalGeneration.from_pretrained( "Qwen/Qwen2-VL-2B-Instruct", device_map="auto", torch_dtype="auto" )
使用 Hugging Face 的多模態模型

前處理器

from transformers import Qwen2VLProcessor

min_pixels = 224 * 224
max_pixels = 448 * 448
vl_model_processor = Qwen2VLProcessor.from_pretrained(
    "Qwen/Qwen2-VL-2B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels
)
使用 Hugging Face 的多模態模型

多模態提示詞

text_query = f"Is the sentiment of the following content good or bad for the Ford share price:
{article_text}. Provide reasoning."


chat_template = [ { "role": "user", "content": [ {"type": "image", "image": article_image}, {"type": "text", "text": text_query} ] } ]
使用 Hugging Face 的多模態模型

VLM 分類

text = vl_model_processor.apply_chat_template(chat_template, tokenize=False,
                                              add_generation_prompt=True)

image_inputs, _ = process_vision_info(chat_template)
inputs = vl_model_processor(text=[text], images=image_inputs, padding=True, return_tensors="pt")
generated_ids = vl_model.generate(**inputs, max_new_tokens=500)
generated_ids_trimmed = [out_ids[len(in_ids) :] for in_ids, out_ids\ in zip(inputs.input_ids, generated_ids)]
使用 Hugging Face 的多模態模型

VLM 分類

output_text = vl_model_processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
The sentiment of the provided text is negative. The author is expressing concern and
skepticism ...
使用 Hugging Face 的多模態模型

一起來練習吧!

使用 Hugging Face 的多模態模型

Preparing Video For Download...