視覺問答(VQA)

使用 Hugging Face 的多模態模型

James Chapman

Curriculum Manager, DataCamp

多模態問答任務
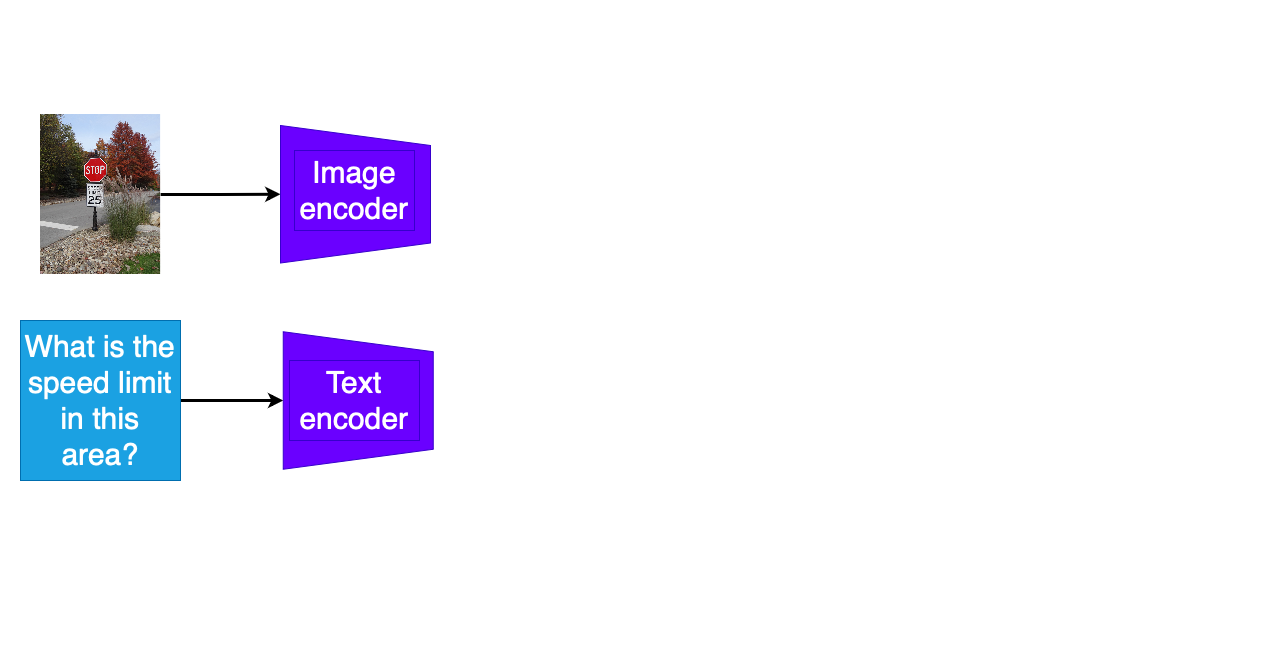
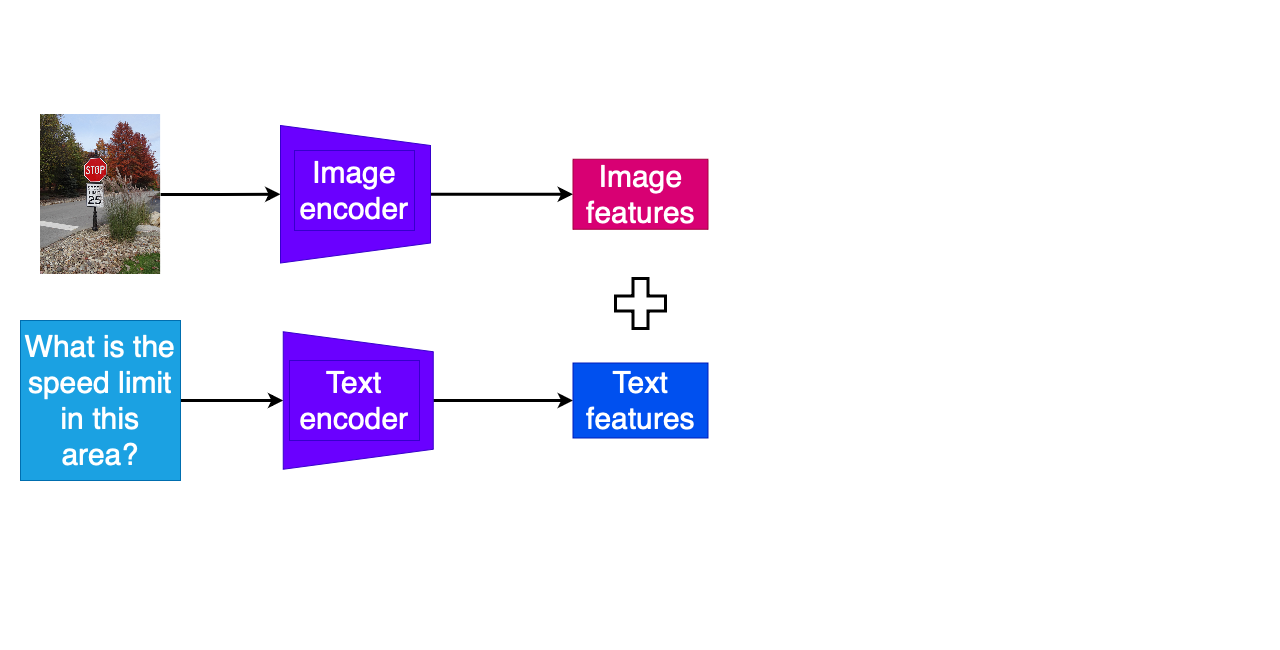
VQA 模型中影像與文字處理流程的圖解

  1. 問題文字與其他模態分開編碼
使用 Hugging Face 的多模態模型

多模態問答任務

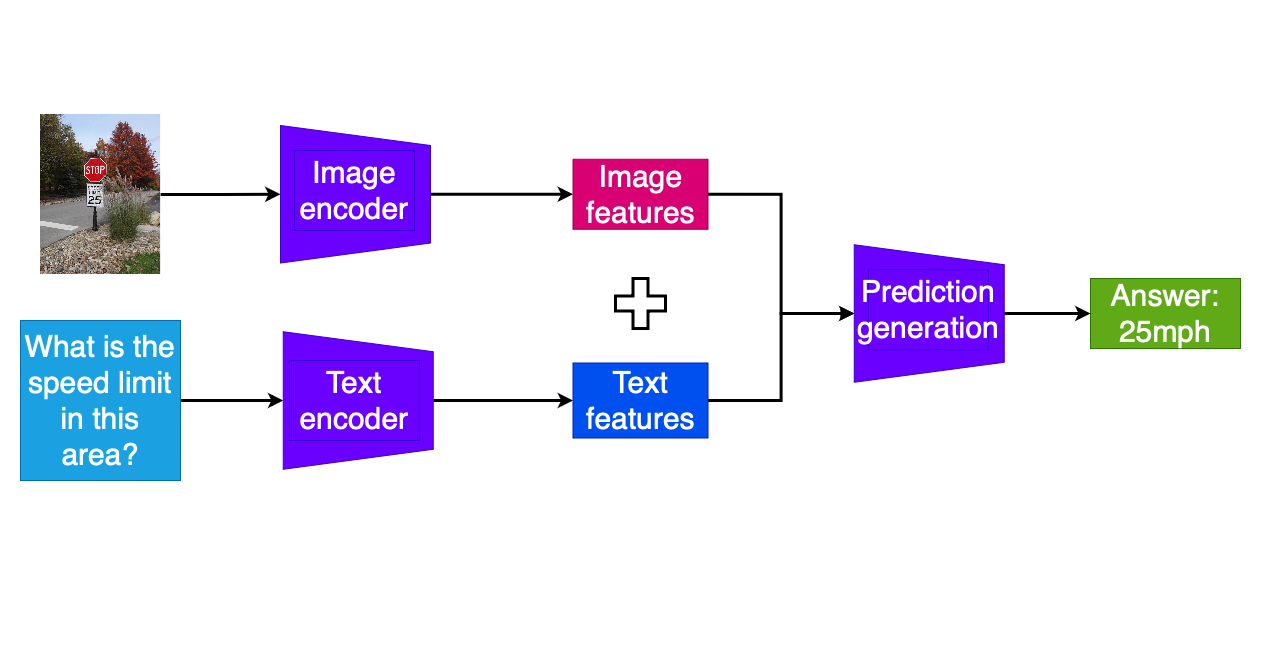
VQA 模型中影像與文字處理流程的圖解

  1. 問題文字與其他模態分開編碼
  2. 將編碼後的特徵組合
使用 Hugging Face 的多模態模型

多模態問答任務

VQA 模型中影像與文字處理流程的圖解

  1. 問題文字與其他模態分開編碼
  2. 將編碼後的特徵組合
  3. 透過額外模型層預測答案詞元
使用 Hugging Face 的多模態模型

VQA

import requests
from PIL import Image

url = "https://www.worldanimalprotection
.org/cdn-cgi/image/width=1920,format=
auto/globalassets/images/elephants/1
033551-elephant.jpg"


image = Image.open(requests.get(url, stream=True).raw)
text = "What animal is in this photo?"

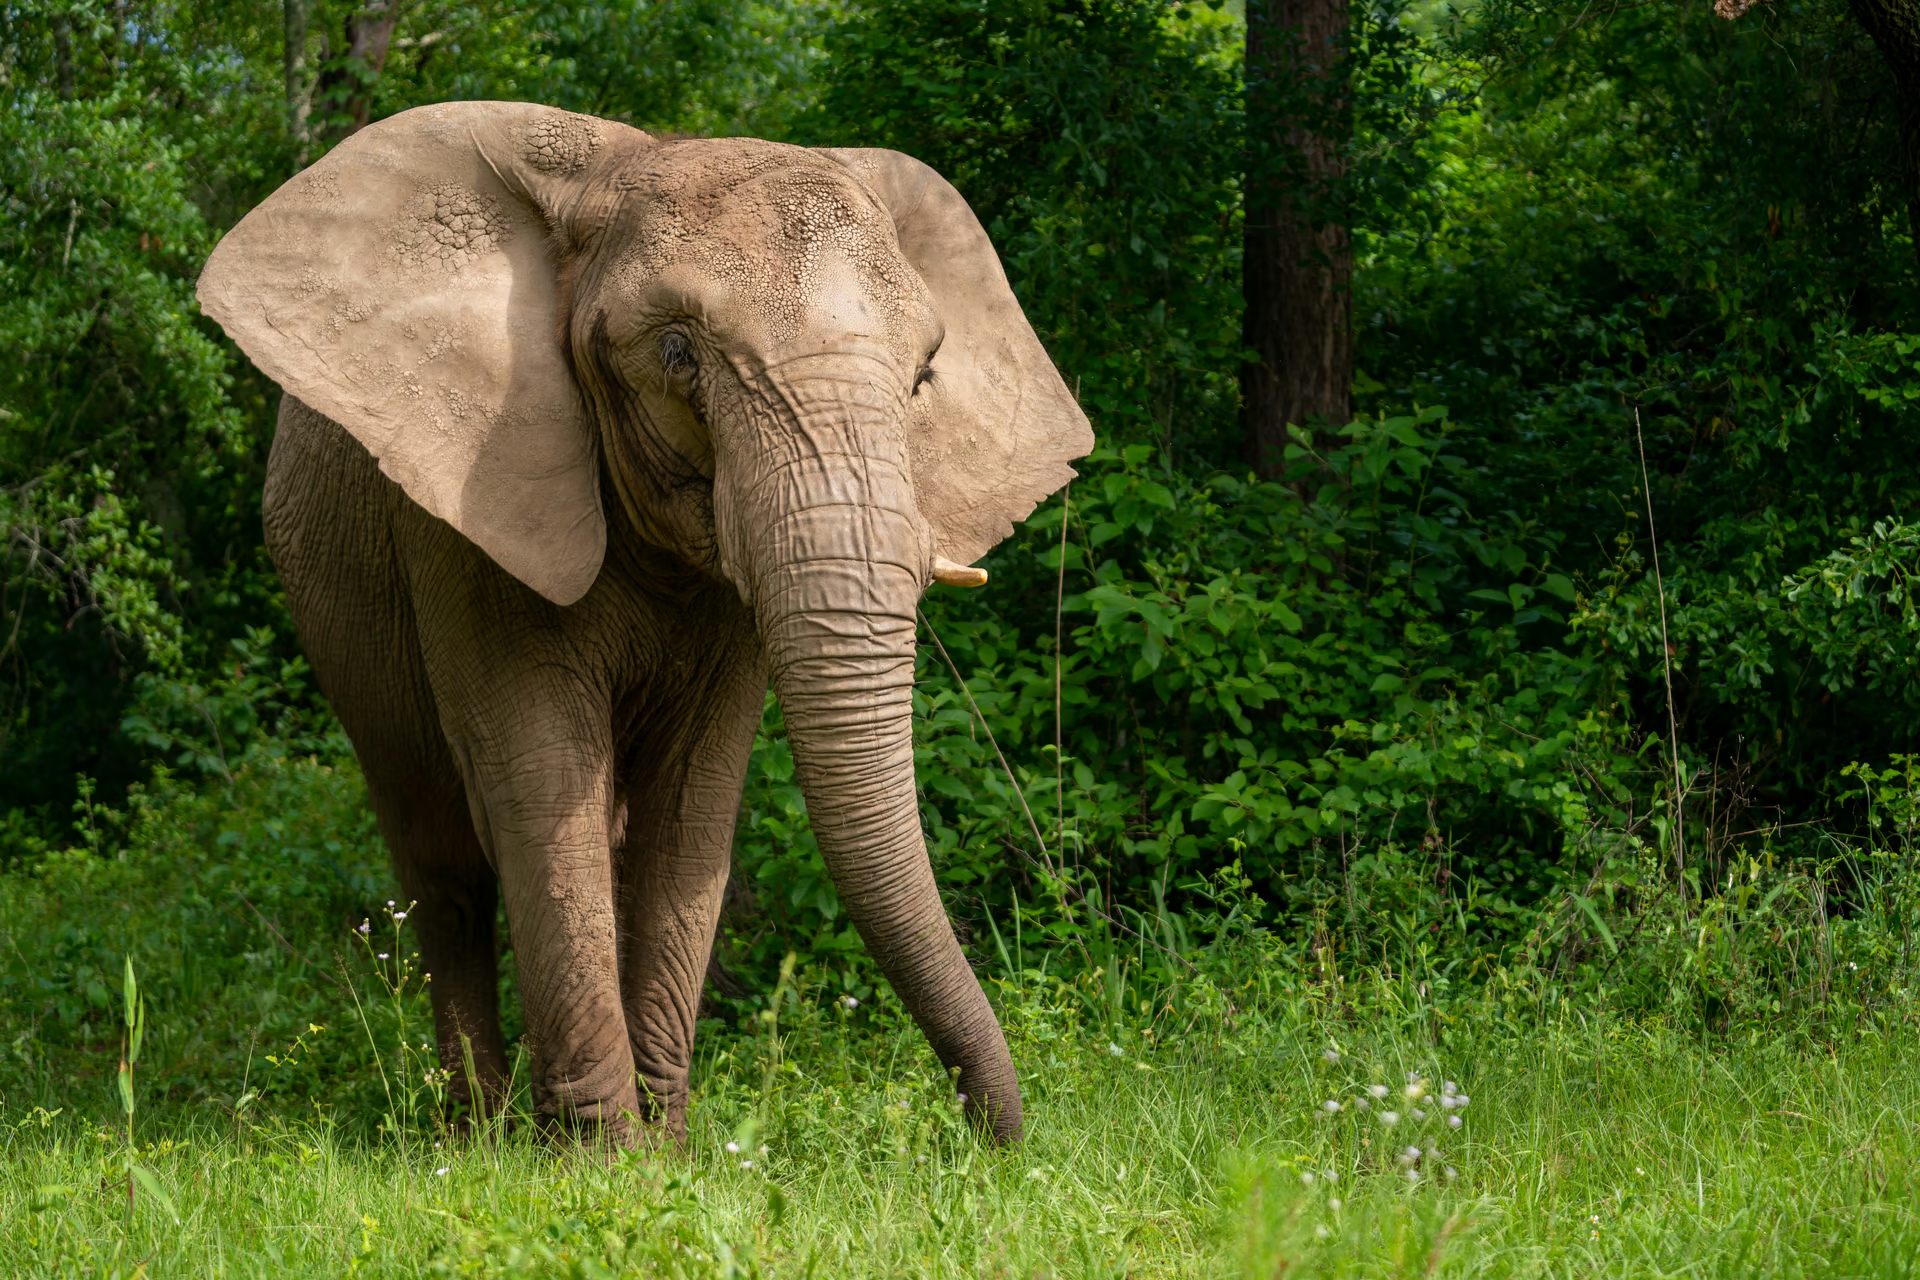
野外的大象照片

使用 Hugging Face 的多模態模型

VQA


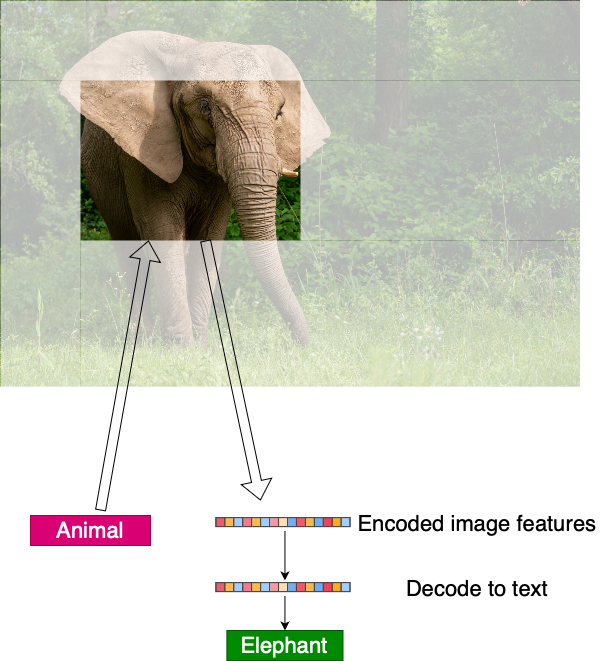
  • 模型已知多種物件的影像與文字特徵
  • 可重複使用,且無需額外微調

聚焦動物並進行辨識的圖解

使用 Hugging Face 的多模態模型

VQA

from transformers import ViltProcessor, ViltForQuestionAnswering


processor = ViltProcessor.from_pretrained("dandelin/vilt-b32-finetuned-vqa") model = ViltForQuestionAnswering.from_pretrained("dandelin/vilt-b32-finetuned-vqa")
encoding = processor(image, text, return_tensors="pt")
outputs = model(**encoding)
idx = outputs.logits.argmax(-1).item()
print("Predicted answer:", model.config.id2label[idx])
Predicted answer: elephant
使用 Hugging Face 的多模態模型

文件 VQA

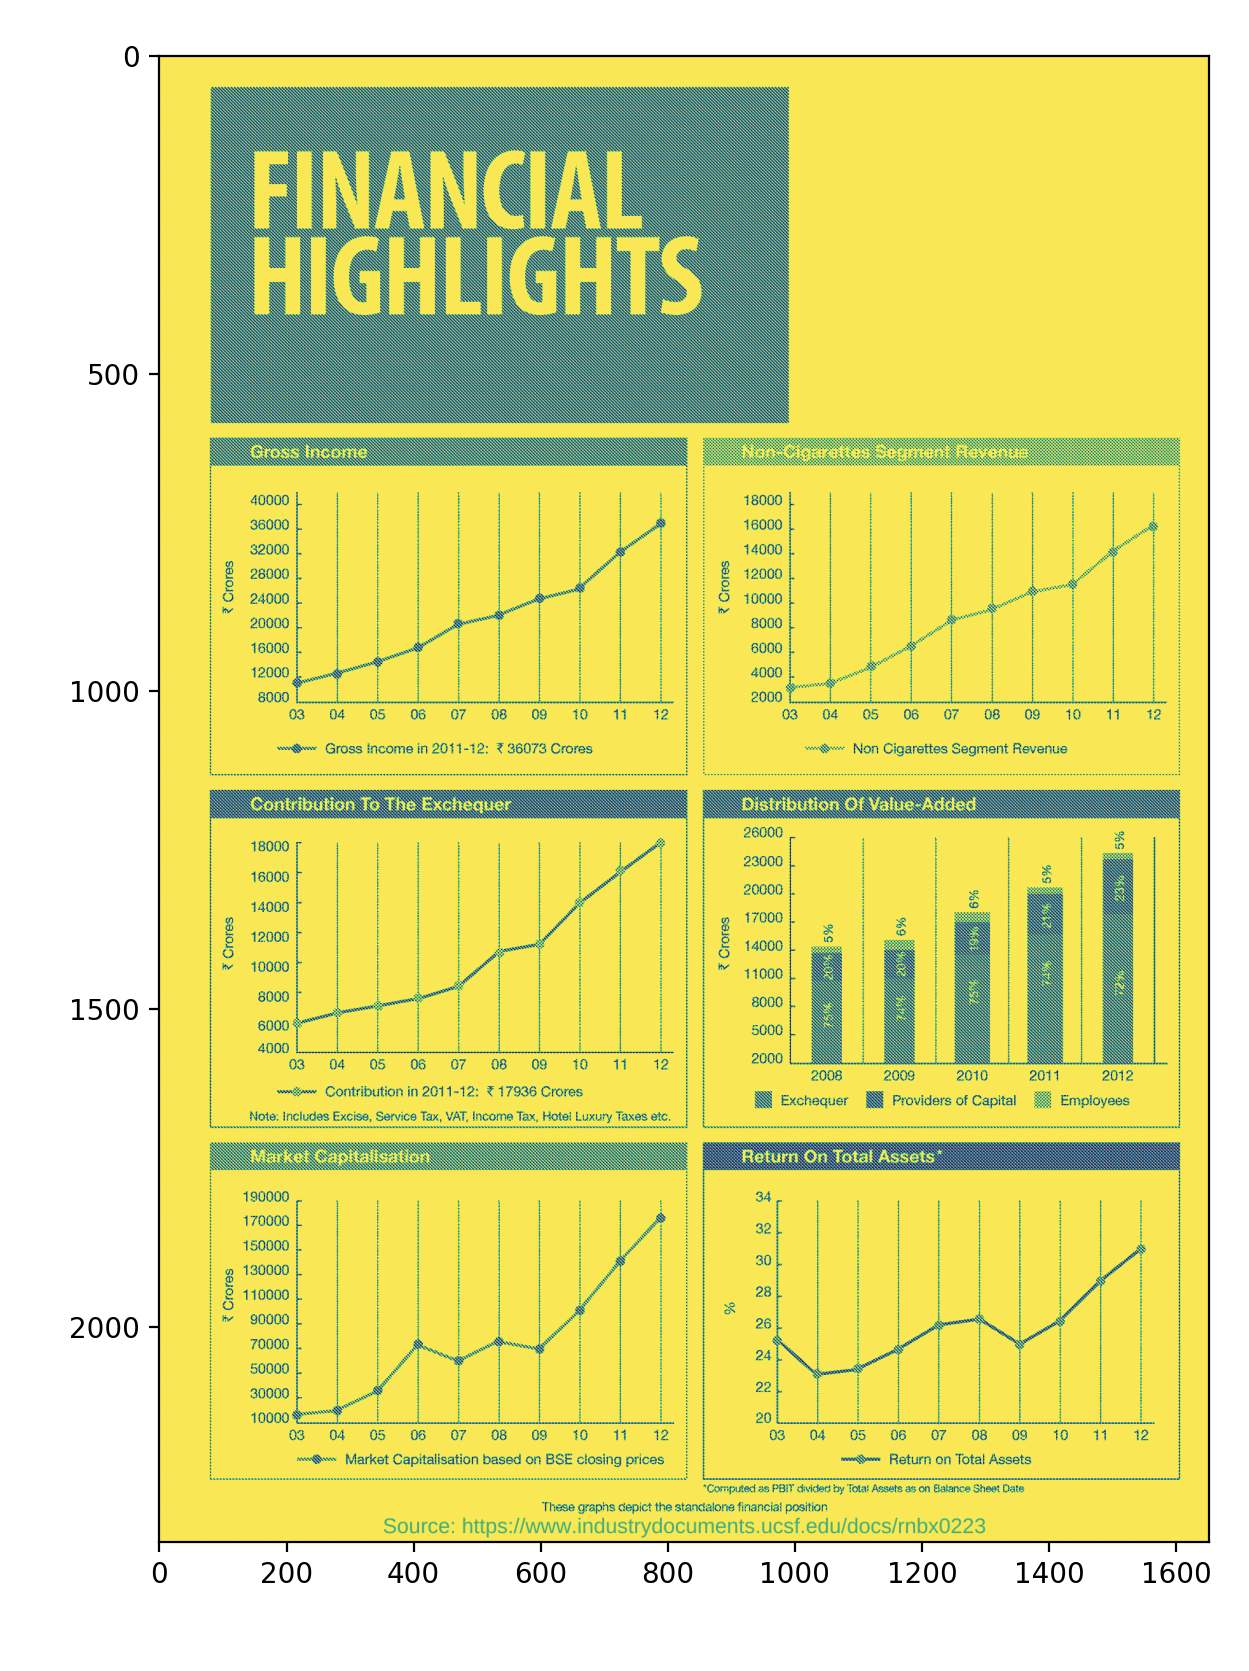
  • 將 VQA 擴展為在影像中偵測圖表、表格與文字(OCR
from datasets import load_dataset
from transformers import pipeline

dataset = load_dataset("lmms-lab/DocVQA")


import matplotlib.pyplot as plt plt.imshow(dataset["test"][2]["image"]) plt.show()

含曲線與長條圖的文件影像

使用 Hugging Face 的多模態模型

文件 VQA

Google Tessearact 標誌

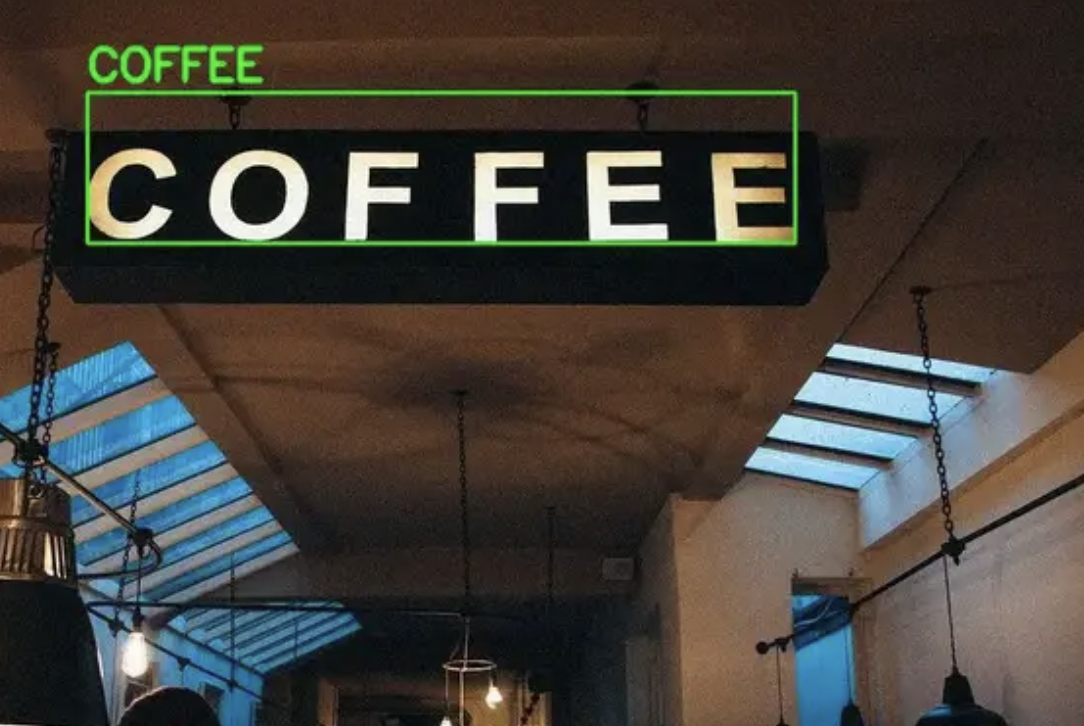
  • 執行 OCR 需要額外相依套件
  • 透過 pip 安裝 pytesseract
  • 透過套件安裝程式安裝 Tesseract OCR(例如 apt-getexehomebrewmacports

帶有 OCR 的咖啡招牌照片

使用 Hugging Face 的多模態模型

文件 VQA

from transformers import pipeline
pipe = pipeline("document-question-answering", "impira/layoutlm-document-qa")

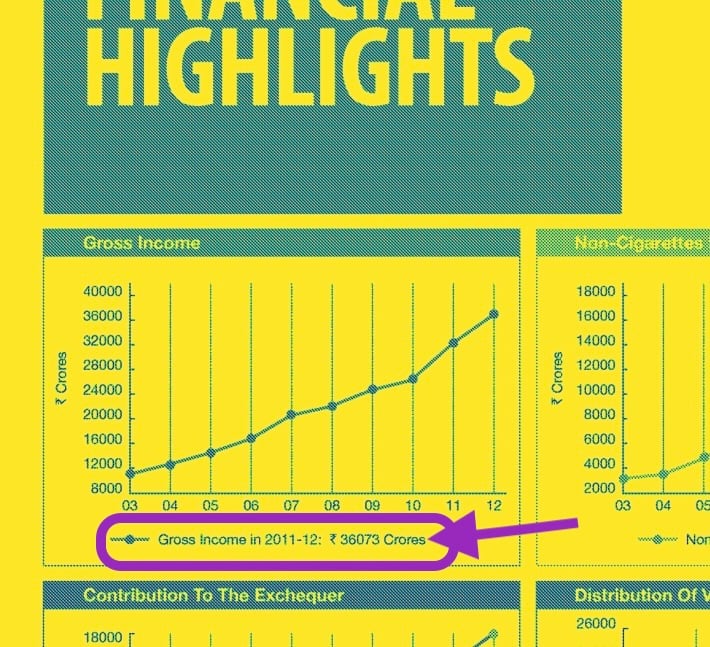
result = pipe( dataset["test"][2]["image"], "What was the gross income in 2011-2012?" )
使用 Hugging Face 的多模態模型

文件 VQA

print(result)
[{'score': 0.05149758607149124,
  'answer': '3 36073 Crores', ...}]

含曲線與長條圖的文件影像

使用 Hugging Face 的多模態模型

一起來練習吧!

使用 Hugging Face 的多模態模型

Preparing Video For Download...