資料品質檢查與摘要統計

在 Python 中監控 Machine Learning

Hakim Elakhrass

Co-founder and CEO of NannyML

什麼是資料品質檢查與摘要統計?
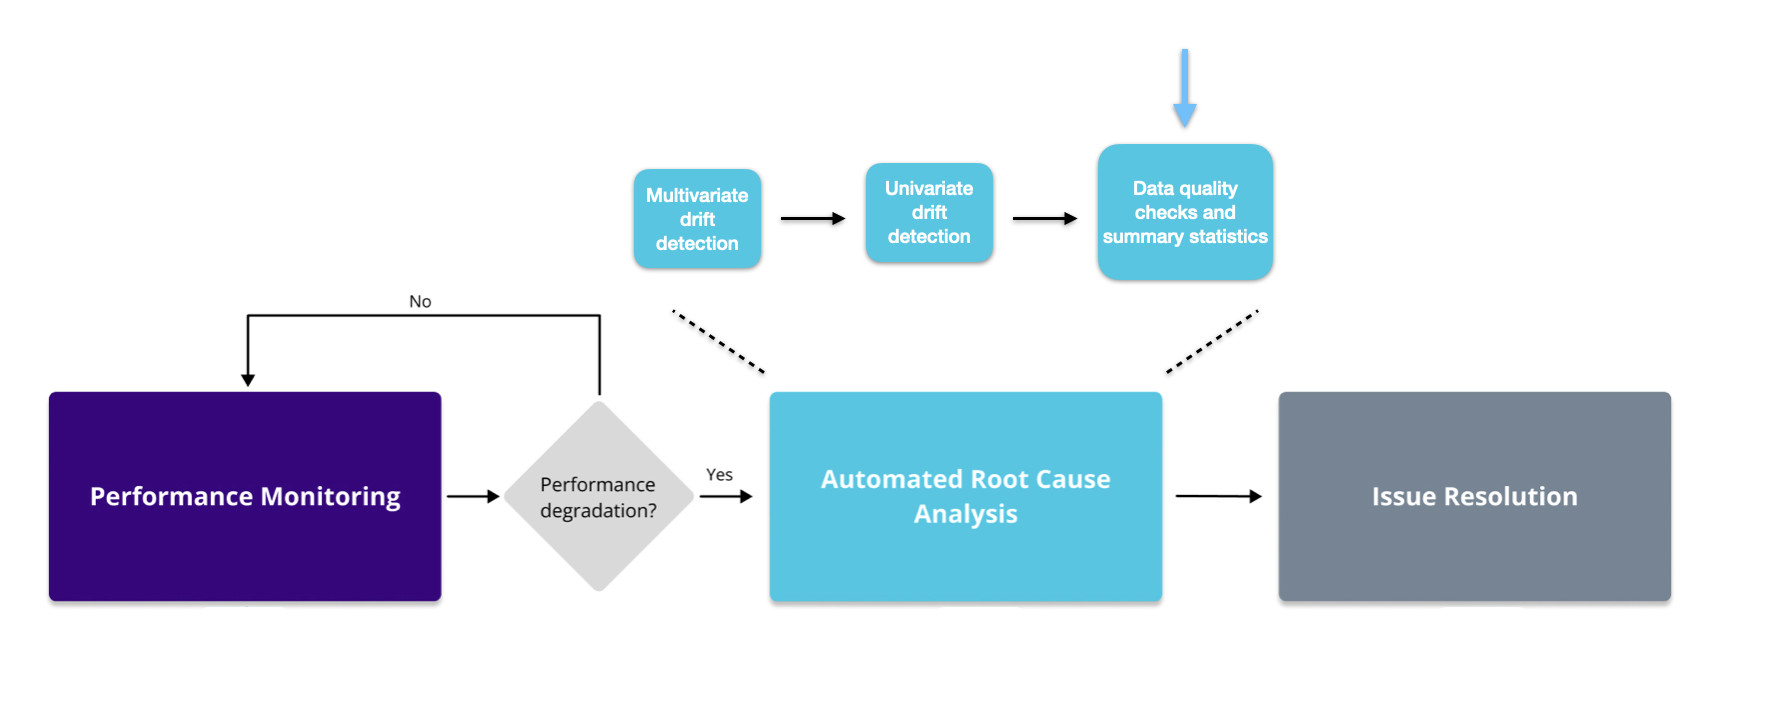
圖片顯示監控流程,其中在自動化根因分析步驟中強調資料品質檢查與摘要統計。

  • 偵測遺漏值
  • 偵測未見值
  • 加總、平均、標準差、中位數與列數
在 Python 中監控 Machine Learning

遺漏值偵測

  • 區塊中的觀測數減少
  • 有價值資訊流失
  • 解讀與決策可能錯誤
# Instantiate the missing values calculator module
ms_calc = nannyml.MissingValuesCalculator(column_names=["Age"], normalize=True)

# Fit the calculator on the reference set
ms_calc.fit(reference)

# Calculate the rate of the missing values on the analysis set
ms_results = ms_calc.calculate(analysis)
ms_results.plot()
在 Python 中監控 Machine Learning

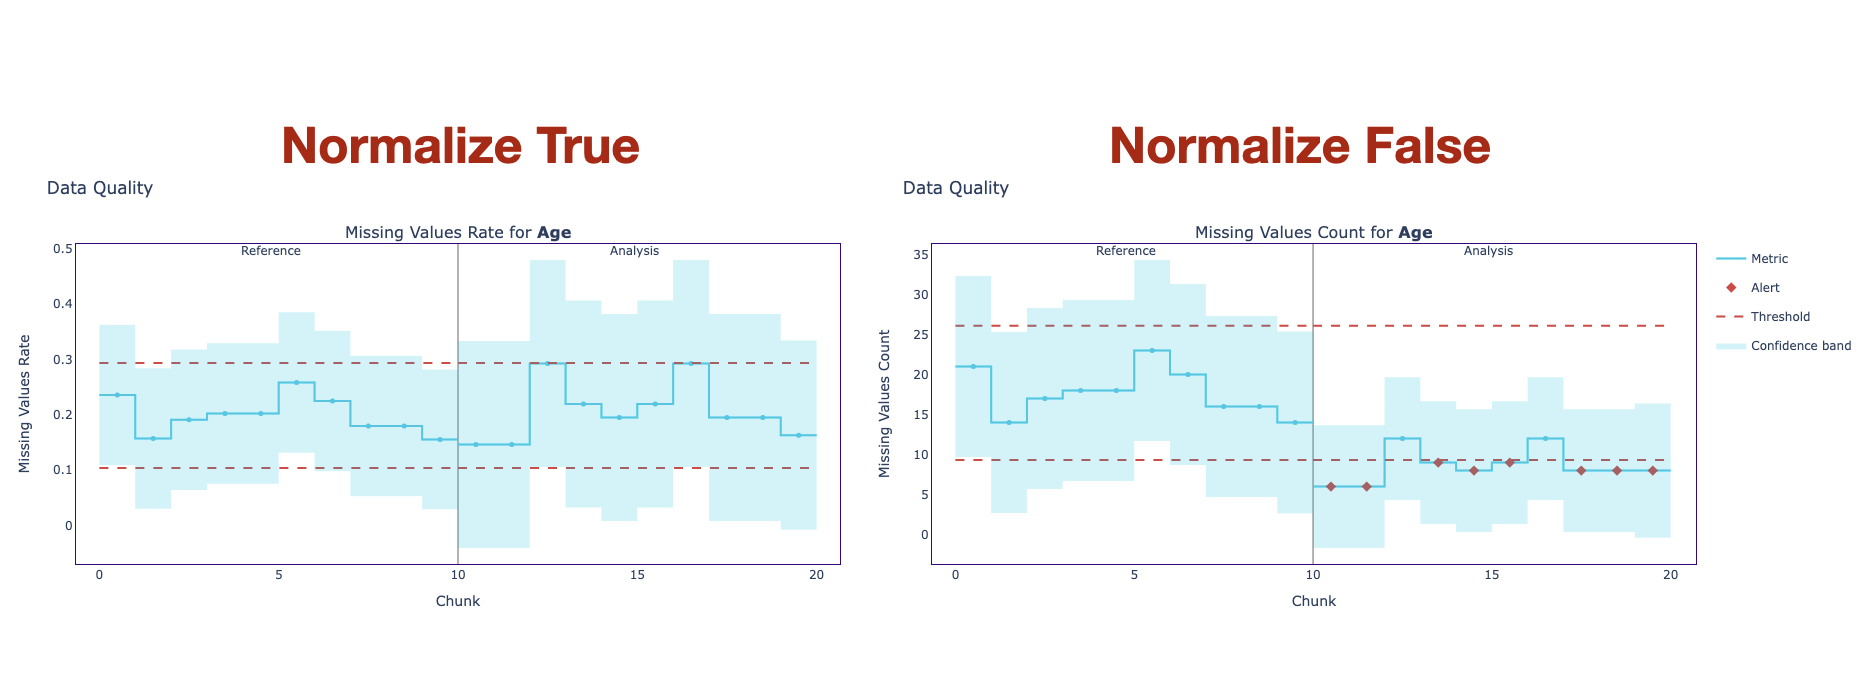
遺漏值圖

此圖顯示在 normalize 參數為 True 與 False 時的遺漏值結果。

在 Python 中監控 Machine Learning

未見值偵測

  • 在參考期間中「不存在」的分類特徵值
  • 未見值增加會使模型在部分區域信心下降
# Instantiate the unseen values calculator module
us_calc = nannyml.UnseenValuesCalculator(column_names=["Cabin"], normalize=False)
# Fit, calculate and plot the rate of the unseen values
us_calc.fit(reference)
us_results = us_calc.calculate(analysis)
us_results.plot()
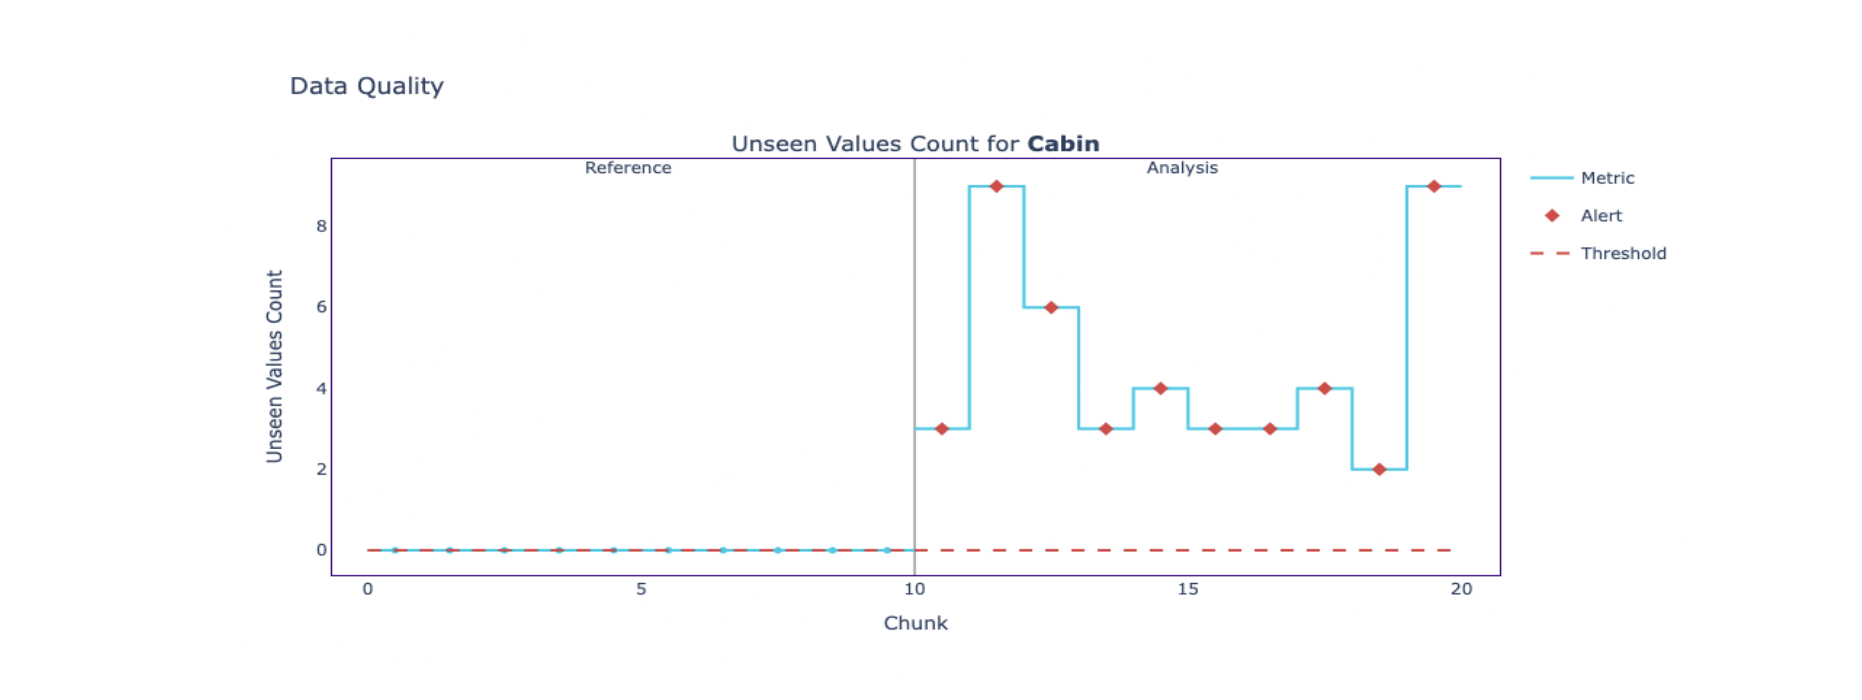
此圖顯示未見值的變化趨勢圖與未見值數量的變動。

在 Python 中監控 Machine Learning

摘要統計

  • 「加總」:用於財務資料計算特定期間的營收或獲利。
  • 「平均」與「標準差」:有助於資料漂移檢查與可解釋性。
  • 「中位數」:對離群值具抗性,適合含許多極端值的特徵。
  • 「列數」:判斷每個區塊是否有足夠資料。
sum_calc = nannyml.SummaryStatsSumCalculator(column_names=selected_columns)
avg_calc = nannyml.SummaryStatsAvgCalculator(column_names=selected_columns)
std_calc = nannyml.SummaryStatsStdCalculator(column_names=selected_columns)
med_calc = nannyml.SummaryStatsMedianCalculator(column_names=selected_columns)
rows_calc = nannyml.SummaryStatsRowCountCalculator(column_names=selected_columns)
在 Python 中監控 Machine Learning

一起來練習吧!

在 Python 中監控 Machine Learning

Preparing Video For Download...