購買預測的資料前處理

Python 的行銷機器學習

Karolis Urbonas

Head of Analytics & Science, Amazon

迴歸:預測連續變數

  • 迴歸:一種監督式學習
  • 目標變數:連續或計數變數
  • 最簡模型:線性迴歸
  • 計數資料(如活躍天數)有時用 Poisson 或 Negative Binomial 迴歸更佳
Python 的行銷機器學習

RFM(Recency、Frequency、Monetary)特徵

  • RFM:許多特徵工程方法的基礎
  • Recency:距離上次交易的時間
  • Frequency:觀察期內的購買次數
  • Monetary 數值:觀察期內的總消費金額
Python 的行銷機器學習

按月檢視銷售分佈

# Explore monthly distribution of observations
online.groupby(['InvoiceMonth']).size()
InvoiceMonth
2010-12    4893
2011-01    3580
2011-02    3648
2011-03    4764
2011-04    4148
2011-05    5018
2011-06    4669
2011-07    4610
2011-08    4744
2011-09    7189
2011-10    8808
2011-11    9513
dtype: int64
Python 的行銷機器學習

分離特徵資料

# Exclude target variable
online_X = online[online['InvoiceMonth']!='2011-11']

# Define snapshot date NOW = dt.datetime(2011,11,1)
# Build the features features = online_X.groupby('CustomerID').agg({ 'InvoiceDate': lambda x: (NOW - x.max()).days, 'InvoiceNo': pd.Series.nunique, 'TotalSum': np.sum, 'Quantity': ['mean', 'sum'] }).reset_index()
features.columns = ['CustomerID', 'recency', 'frequency', 'monetary', 'quantity_avg', 'quantity_total']
Python 的行銷機器學習

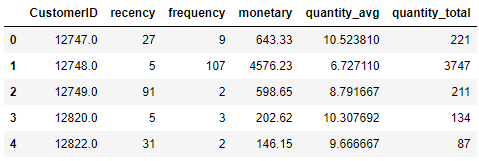
檢視特徵

print(features.head())

Features header

Python 的行銷機器學習

計算目標變數

# Build pivot table with monthly transactions per customer
cust_month_tx = pd.pivot_table(data=online, index=['CustomerID'], 
                               values='InvoiceNo',
                               columns=['InvoiceMonth'],
                               aggfunc=pd.Series.nunique, fill_value=0)
print(cust_month_tx.head())
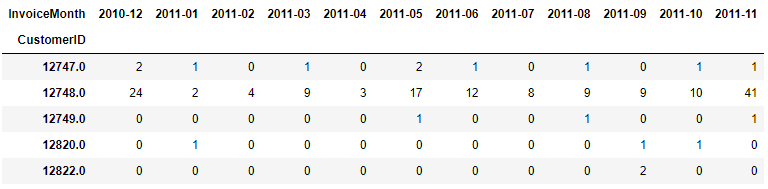
Customer monthly pivot table

Python 的行銷機器學習

完成資料準備並切分訓練/測試

# Store identifier and target variable column names
custid = ['CustomerID']
target = ['2011-11']

# Extract target variable Y = cust_month_tx[target]
# Extract feature column names cols = [col for col in features.columns if col not in custid]
# Store features X = features[cols]
Python 的行銷機器學習

切分訓練集與測試集

# Randomly split 25% of the data to testing
from sklearn.model_selection import train_test_split
train_X, test_X, train_Y, test_Y = train_test_split(X, Y, 
                                                    test_size=0.25, 
                                                    random_state=99)

# Print shapes of the datasets print(train_X.shape, train_Y.shape, test_X.shape, test_Y.shape)
(2529, 5) (2529, 1) (843, 5) (843, 1)
Python 的行銷機器學習

一起來練習吧!

Python 的行銷機器學習

Preparing Video For Download...