在 Python 設計機器學習工作流程
Dr. Chris Anagnostopoulos
Honorary Associate Professor
kdd.iloc[0]
kdd.iloc[0]
duration                         51
protocol_type                   tcp
service                        smtp
flag                             SF
src_bytes                      1169
dst_bytes                       332
land                              0
...
dst_host_rerror_rate              0
dst_host_srv_rerror_rate          0
label                          good
二值化標籤:
kdd['label'] = kdd['label'] == 'bad'
訓練 Gaussian Naive Bayes 分類器:
clf = GaussianNB().fit(X_train, y_train)
predictions = clf.predict(X_test)
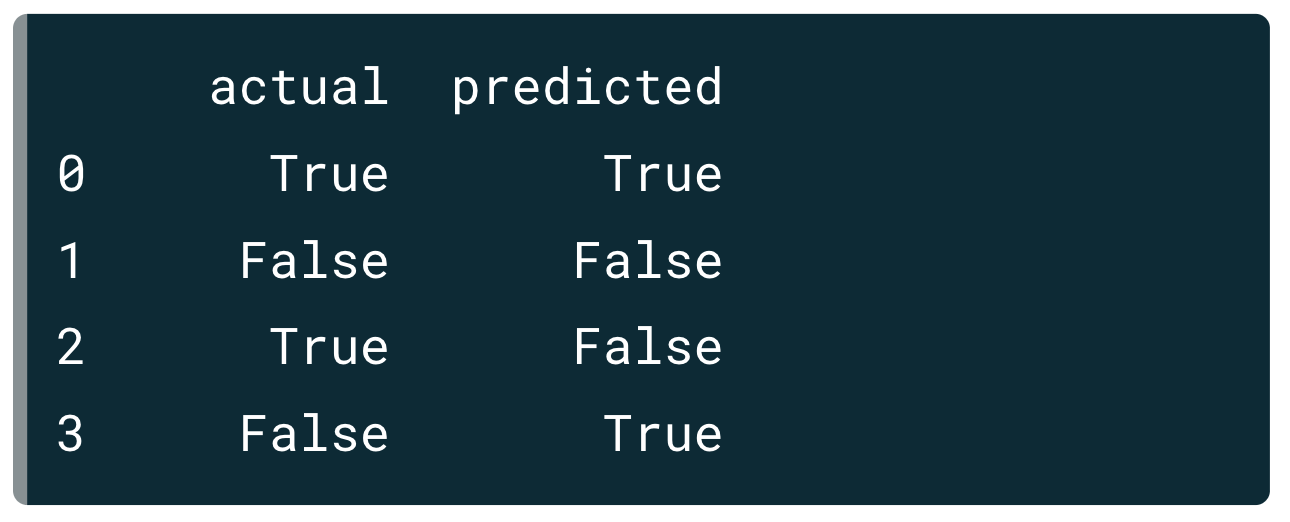
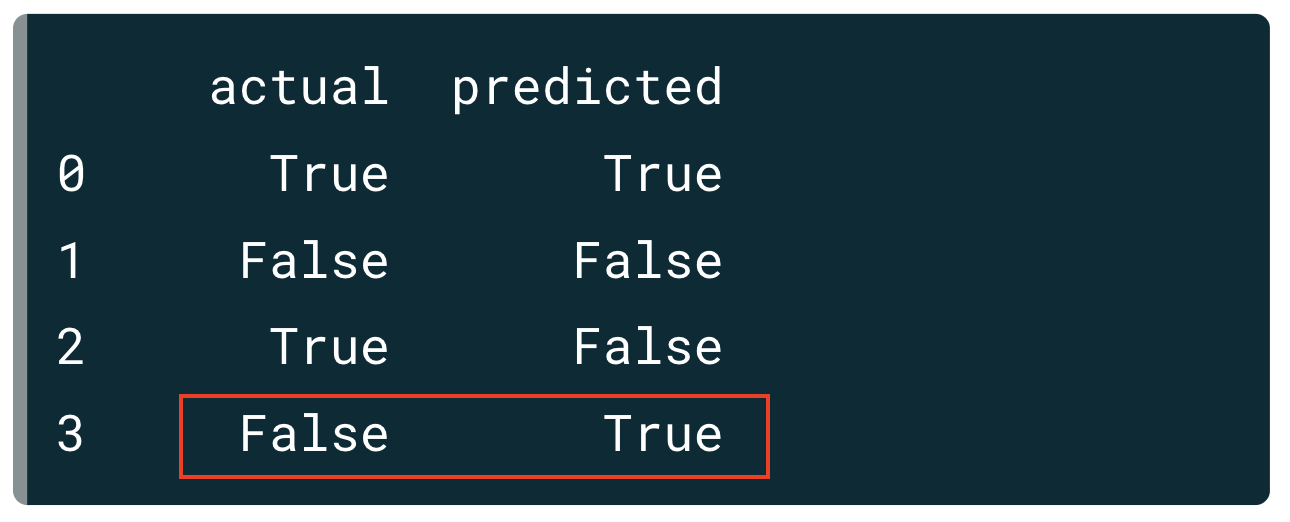
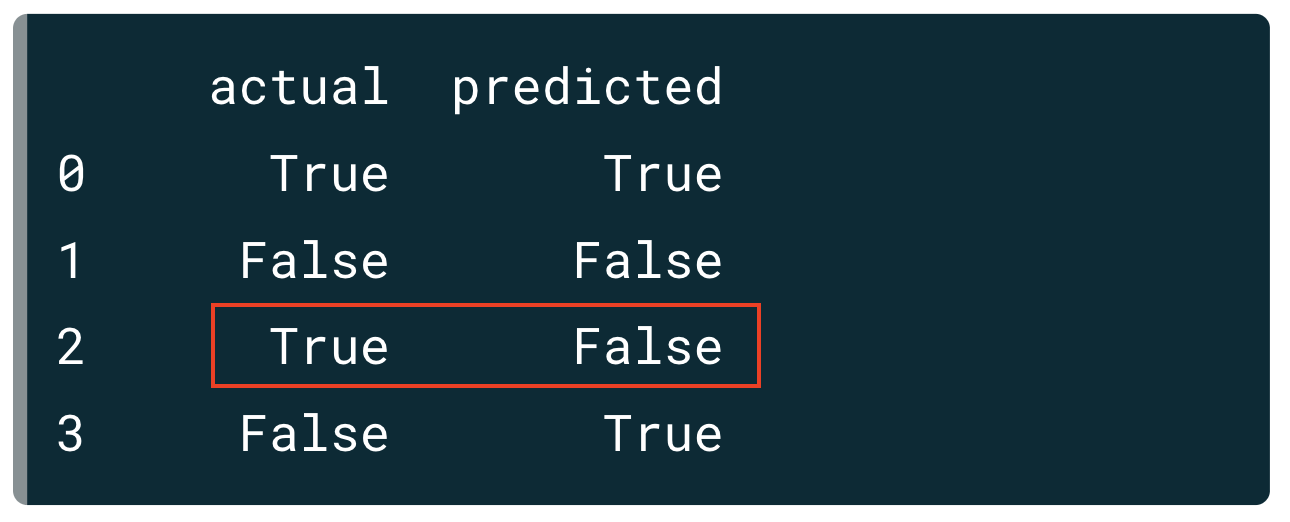
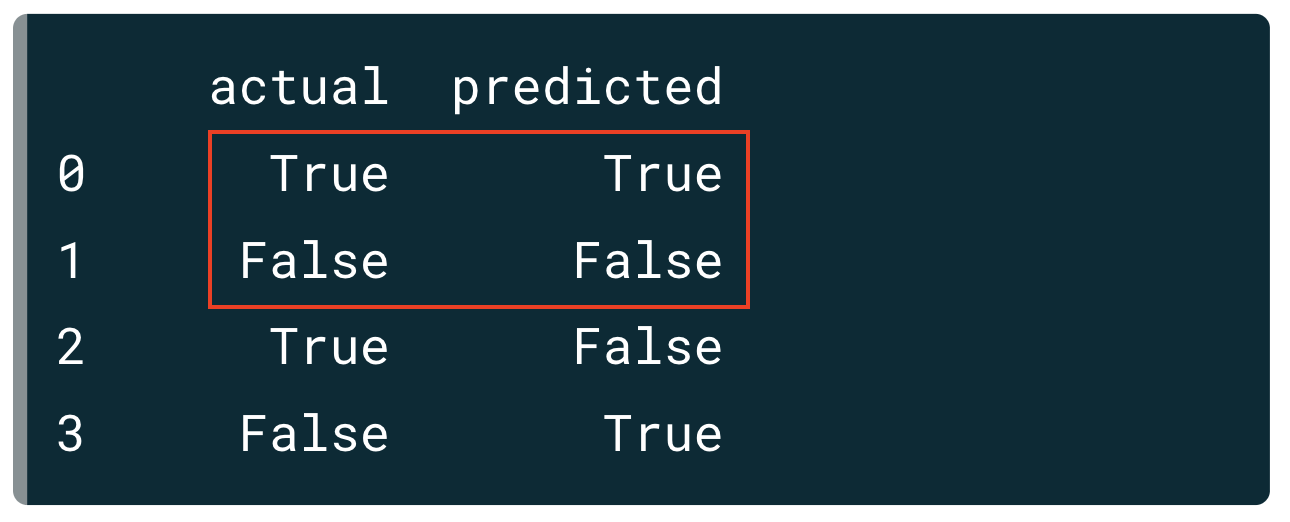
results = pd.DataFrame({
    'actual': y_test,
    'predicted': predictions
})
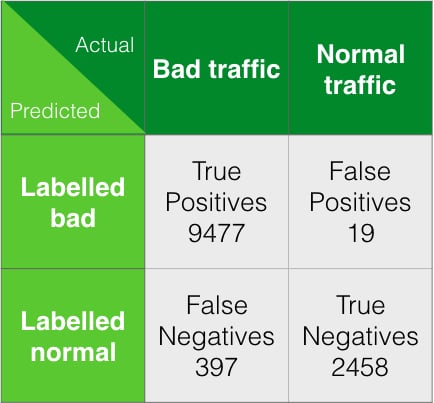
conf_mat = confusion_matrix(
    ground_truth, predictions)
array([[9477,   19],
       [ 397, 2458]])
tn, fp, fn, tp = conf_mat.ravel()
(fp, fn)
(19, 397)
accuracy = 1-(fp + fn)/len(ground_truth)

recall = tp/(tp+fn)

fpr = fp/(tn+fp)

precision = tp/(tp+fp)

f1 = 2*(precision*recall)/(precision+recall)
accuracy = 1-(fp + fn)/len(ground_truth)
recall = tp/(tp+fn)
fpr = fp/(tn+fp)
precision = tp/(tp+fp)
f1 = 2*(precision*recall)/(precision+recall)
accuracy_score(ground_truth, predictions)
recall_score(ground_truth, predictions)
precision_score(ground_truth, predictions)
f1_score(ground_truth, predictions)
分類器 A:
tn, fp, fn, tp = confusion_matrix(
    ground_truth, predictions_A).ravel()
(fp,fn)
(3, 3)
cost = 10 * fp + fn
33
分類器 B:
tn, fp, fn, tp = confusion_matrix(
    ground_truth, predictions_B).ravel()
(fp,fn)
(0, 26)
26