在 Python 設計機器學習工作流程
Dr. Chris Anagnostopoulos
Honorary Associate Professor
from sklearn.ensemble import RandomForestClassifier as rf
X_train, X_test, y_train, y_test = train_test_split(X, y)
grid_search = GridSearchCV(rf(), param_grid={'max_depth': [2, 5, 10]})
grid_search.fit(X_train, y_train)
depth = grid_search.best_params_['max_depth']
vt = SelectKBest(f_classif, k=3).fit(X_train, y_train)
clf = rf(max_depth=best_value).fit(vt.transform(X_train), y_train)
accuracy_score(clf.predict(vt.transform(X_test), y_test))
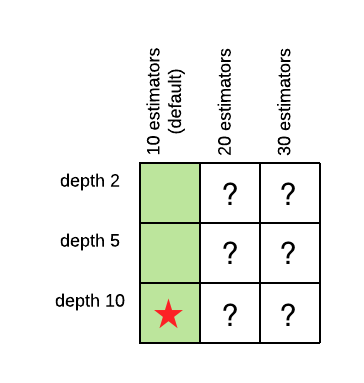
最佳化 max_depth:
max_depth
pg = {'max_depth': [2,5,10]}
gs = GridSearchCV(rf(),
   param_grid=pg)
gs.fit(X_train, y_train)
depth = gs.best_params_['max_depth']
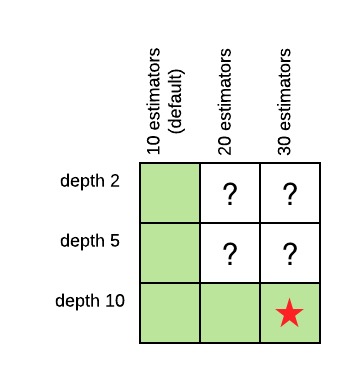
接著最佳化 n_estimators:
n_estimators
pg = {'n_estimators': [10,20,30]}
gs = GridSearchCV(
   rf(max_depth=depth),
   param_grid=pg)
gs.fit(X_train, y_train)
n_est = gs.best_params_[
    'n_estimators']
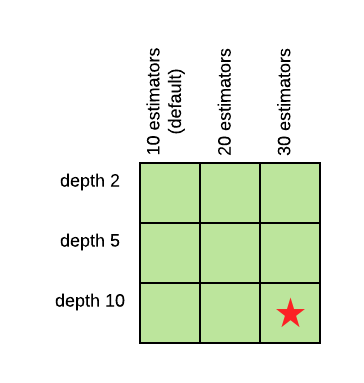
同時調 max_depth 與 n_estimators:
pg = {
   'max_depth': [2,5,10],
   'n_estimators': [10,20,30]
}
gs = GridSearchCV(rf(),
   param_grid=pg)
gs.fit(X_train, y_train)
print(gs.best_params_)

{'max_depth': 10, 'n_estimators': 20}
pg = { 'max_depth': [2,5,10], 'n_estimators': [10,20,30] } gs = GridSearchCV(rf(), param_grid=pg) gs.fit(X_train, y_train) print(gs.best_params_)
{'max_depth': 10, 'n_estimators': 20}
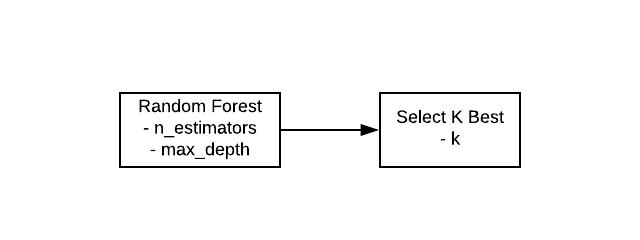
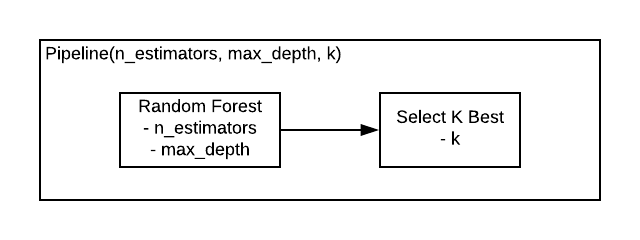
from sklearn.pipeline import Pipeline
pipe = Pipeline([
    ('feature_selection', SelectKBest(f_classif)),
    ('classifier', RandomForestClassifier())
])

params = dict(
    feature_selection__k=[2, 3, 4],
    classifier__max_depth=[5, 10, 20]
)

grid_search = GridSearchCV(pipe, param_grid=params)
gs = grid_search.fit(X_train, y_train).best_params_
from sklearn.pipeline import Pipeline pipe = Pipeline([ ('feature_selection', SelectKBest(f_classif)), ('classifier', RandomForestClassifier()) ])
params = dict( feature_selection__k=[2, 3, 4], classifier__max_depth=[5, 10, 20] )
grid_search = GridSearchCV(pipe, param_grid=params) gs = grid_search.fit(X_train, y_train).best_params_
{'classifier__max_depth': 20, 'feature_selection__k': 4}
from sklearn.metrics import roc_auc_score, make_scorer
auc_scorer = make_scorer(roc_auc_score)

grid_search = GridSearchCV(pipe, param_grid=params, scoring=auc_scorer)
from sklearn.metrics import roc_auc_score, make_scorer auc_scorer = make_scorer(roc_auc_score)
grid_search = GridSearchCV(pipe, param_grid=params, scoring=auc_scorer)
params = dict(
    feature_selection__k=[2, 3, 4],
    clf__max_depth=[5, 10, 20],
    clf__n_estimators=[10, 20, 30]
)
grid_search = GridSearchCV(pipe, params, cv=10)
3 x 3 x 3 x 10 = 270 次分類器擬合!