建立並調校隨機森林模型

Tidyverse 的 Machine Learning

Dmitriy (Dima) Gorenshteyn

Lead Data Scientist, Memorial Sloan Kettering Cancer Center

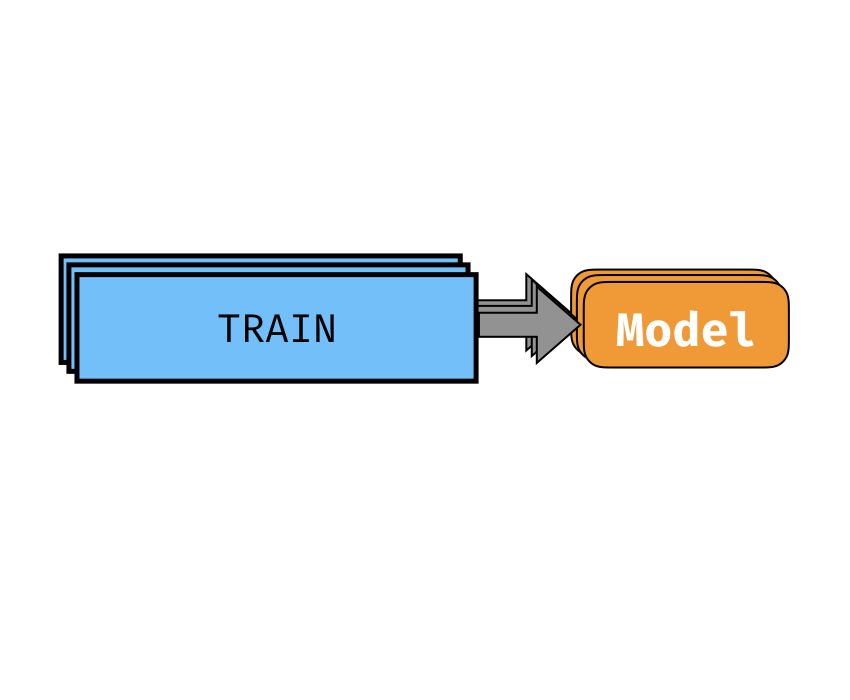
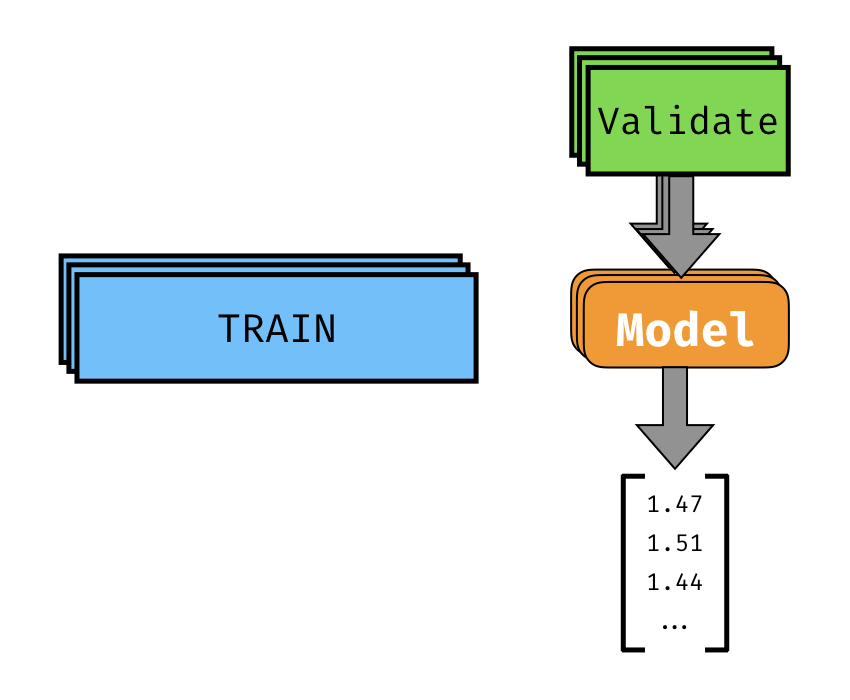
交叉驗證效能

Tidyverse 的 Machine Learning

交叉驗證效能

Tidyverse 的 Machine Learning

交叉驗證效能

Tidyverse 的 Machine Learning

交叉驗證效能

Tidyverse 的 Machine Learning

線性迴歸模型


驗證 MAE:

1.5 年

Tidyverse 的 Machine Learning

另一個模型

Tidyverse 的 Machine Learning

隨機森林優點

  • 可處理非線性關係
  • 可處理交互作用
Tidyverse 的 Machine Learning

隨機森林基本工具

模型
rf_model <- ranger(formula = ___, data = ___, seed = ___)


預測
prediction <- predict(rf_model, new_data)$predictions
Tidyverse 的 Machine Learning

建立基本隨機森林模型

library(ranger)
cv_models_rf <- cv_data %>% 
 mutate(model = map(train, ~ranger(formula = life_expectancy~., 
                                    data = .x, seed = 42)))
cv_prep_rf <- cv_models_rf %>% 
 mutate(validate_predicted = map2(model, validate, 
                                  ~predict(.x, .y)$predictions))
Tidyverse 的 Machine Learning

ranger 超參數

模型
rf_model <- ranger(formula, data, seed, mtry, num.trees)
超參數
name range default
mtry $1:number\ of\ features$ $\sqrt{number\ of\ feat}$
num.trees $1:\infty$ $500$
Tidyverse 的 Machine Learning

調整超參數

cv_tune <- cv_data %>% 
  crossing(mtry = 1:5)

cv_tune
# A tibble: 25 x 5
   splits       id    train                validate            mtry
   <list>       <chr> <list>               <list>             <int>
 1 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [601 × 7]>     1
 2 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [601 × 7]>     2
 3 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [601 × 7]>     3
 4 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [601 × 7]>     4
 5 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [601 × 7]>     5
 6 <S3: rsplit> Fold2 <tibble [2,402 × 7]> <tibble [601 × 7]>     1
 7 <S3: rsplit> Fold2 <tibble [2,402 × 7]> <tibble [601 × 7]>     2
Tidyverse 的 Machine Learning

調整超參數

cv_model_tunerf <- cv_tune %>% 
  mutate(model = map2(train, mtry, ~ranger(formula = life_expectancy~., 
                                           data = .x, mtry = .y)))

cv_model_tunerf
# A tibble: 25 x 6
   splits       id    train                validate      mtry  model       
 * <list>       <chr> <list>               <list>        <int> <list>      
 1 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [60…   1    <S3: ranger>
 2 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [60…   2    <S3: ranger>
 3 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [60…   3    <S3: ranger>
 4 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [60…   4    <S3: ranger>
 5 <S3: rsplit> Fold1 <tibble [2,402 × 7]> <tibble [60…   5    <S3: ranger>
 6 <S3: rsplit> Fold2 <tibble [2,402 × 7]> <tibble [60…   1    <S3: ranger>
 7 <S3: rsplit> Fold2 <tibble [2,402 × 7]> <tibble [60…   2    <S3: ranger>
Tidyverse 的 Machine Learning

一起來練習吧!

Tidyverse 的 Machine Learning

Preparing Video For Download...