K-匿名性簡介

Data Privacy and Anonymization in Python

Rebeca Gonzalez

Data engineer

為何 k-匿名性重要?

左側為麻薩諸塞州州長,文字為「辨識麻薩諸塞州州長」,右側為哈佛教授 Latanya Sweeney 的圖片

Data Privacy and Anonymization in Python

為什麼重要?

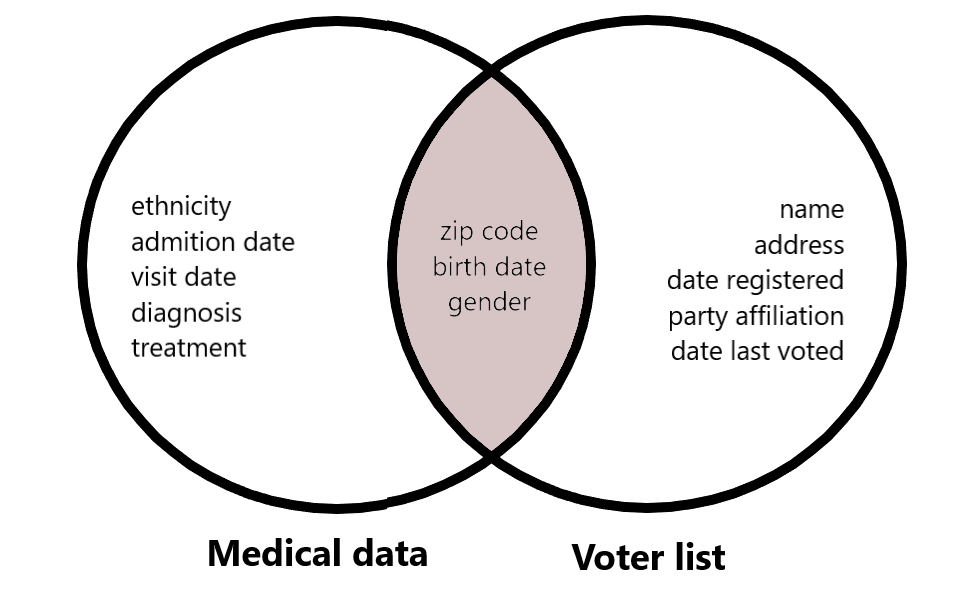
  • 有 6 人與他同一天出生
  • 其中僅 3 人為男性
  • 他的 ZIP code 只有他一人

圖示顯示兩個資料集的交集:醫療資料與選民名單,其交集為 zip code、出生日期與性別

Data Privacy and Anonymization in Python

如何防止此類攻擊?

只有一筆紀錄符合州長的人口統計值。

若刪除所有人口統計資訊,資料將無法分析。

是否有折衷作法,讓資料集中這些人口統計值不再是唯一?

Data Privacy and Anonymization in Python

k-匿名性的定義

$$ $$ $$ $$ $$ $$ 資料集中至少有 k 個人 共享對每位個體可能具辨識性的屬性組合。

Data Privacy and Anonymization in Python

k-匿名性的定義

大量行人穿越馬路

Data Privacy and Anonymization in Python

K-匿名資料集

2-匿名:

     ZIP code    Age
0    4217        34
1    4217        34
2    1742        77
3    1742        77

資料集中每種識別欄位的值組合,至少出現於 k 筆不同紀錄。

非 2-匿名:

     ZIP code    Age
0    4217        34
1    4217        34
2    1742        77
3    1743        77
Data Privacy and Anonymization in Python

K-匿名性:術語

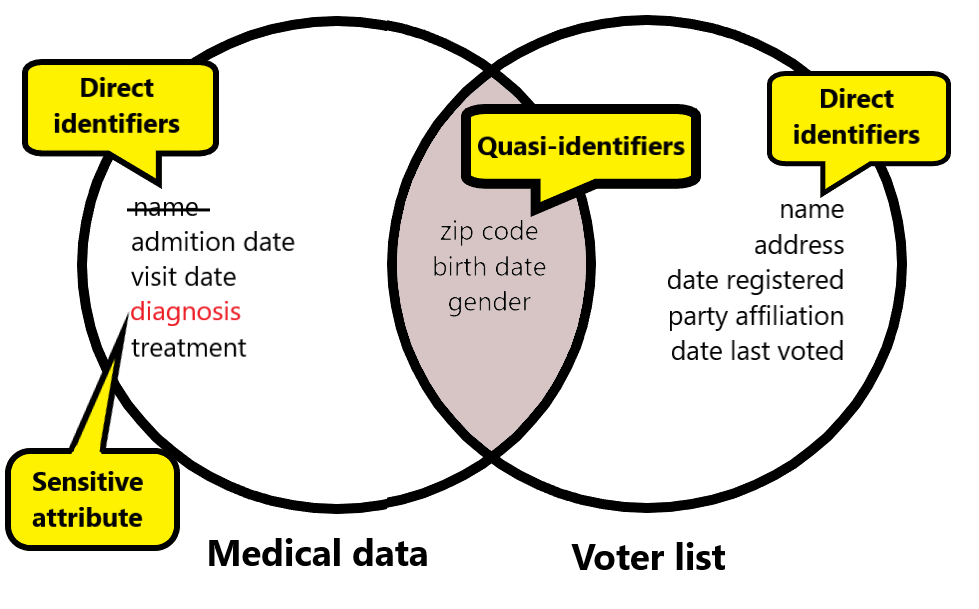
圖示顯示 direct identifiers、quasi-identifiers 與 sensitive attributes 等術語

Data Privacy and Anonymization in Python

醫療資料資料集

# Explore DataFrame 
medical_df.head()
    Age    Department   Condition
0    34    Marketing    Anxiety disorders
1    46    Finance      Flu
2    41    Finance      Flu
3    62    Marketing    Anxiety disorders
4    44    Marketing    Anxiety disorders
Data Privacy and Anonymization in Python

隱私屬性

隱私屬性:

  • 識別性:可能是 SSN 與 ID 編號。
  • 準識別:本資料集的 Age 與 Department
  • 敏感性:本資料集的 Medical condition
Data Privacy and Anonymization in Python

探索準識別的唯一組合

# Calculate how many unique combinations are for Age and Department
medical_df.groupby(['Age','Department']).size().reset_index(name='Count')
    Age    Department    Count
0    30    Production    2
1    31    Marketing     1
2    32    Marketing     1
3    32    Production    1
4    33    Production    1
5    34    Finance       1
6    34    Marketing     1
7    34    Production    1
8    35    Marketing     1
9    36    Finance       2
10    38    Finance      1
11    38    Production   1
Data Privacy and Anonymization in Python

方法:一般化

# Generalize Age by creating 4 groups of intervals
medical_df['Age_group'] = pd.cut(medical_df['Age'], bins=4)


# Explore the dataset with intervals medical_df.head()
    Age    Department    Condition            Age_group
0    34    Marketing     Anxiety disorders    (29.964, 39.0]
1    46    Finance       Flu                  (39.0, 48.0]
2    41    Finance       Flu                  (39.0, 48.0]
3    62    Marketing     Anxiety disorders    (57.0, 66.0]
4    44    Marketing     Anxiety disorders    (39.0, 48.0]
Data Privacy and Anonymization in Python

方法:一般化

# Calculate how many unique combinations are for Age and Department
medical_df.groupby(['Age_group','Department']).size().reset_index(name='Count')
     Age_group         Department    Count
0    (29.964, 39.0]    Finance       4
1    (29.964, 39.0]    Marketing     4
2    (29.964, 39.0]    Production    6
3    (39.0, 48.0]      Finance       8
4    (39.0, 48.0]      Marketing     5
5    (39.0, 48.0]      Production    4
6    (48.0, 57.0]      Finance       3
7    (48.0, 57.0]      Marketing     2
8    (48.0, 57.0]      Production    4
Data Privacy and Anonymization in Python

方法:一般化

# Set k to be 2, for a 2-anonymous dataset
k = 2


# Calculate how many unique combinations are for Age and Department df_count = medical_df.groupby(['Age_group','Department']).size().reset_index(name='Count')
# Filter the rows that have count less than k df_count[df_count['Count'] < k]
    Age_group    Department    Count
Data Privacy and Anonymization in Python

開始做 k-匿名化!

Data Privacy and Anonymization in Python

Preparing Video For Download...