不同的頻率準則

R 的 Bag-of-Words 文本探勘

Ted Kwartler

Instructor

詞權重
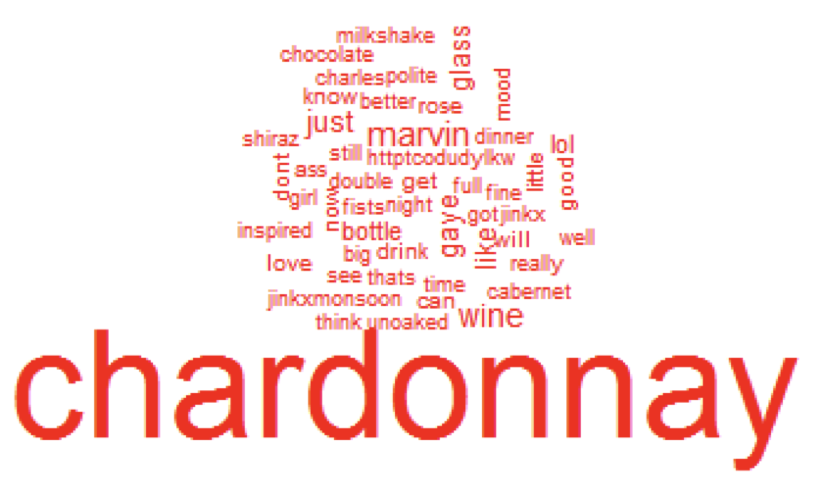
  • 預設詞頻=單純詞數
  • 高頻詞可能掩蓋洞見
  • 透過 TfIdf 調整詞權重
  • 出現在許多文件的詞會被降低權重

文字雲

R 的 Bag-of-Words 文本探勘

詞權重

# 標準詞權重
tf_tdm <- TermDocumentMatrix(text_corp)
tf_tdm_m <- as.matrix(tf_dtm)
tf_tdm_m[505:510, 5:10]
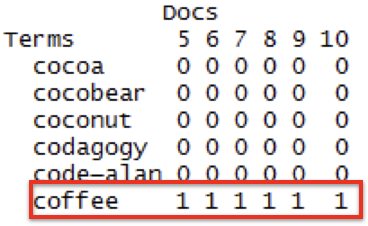
tdf.png

# TfIdf 權重
tf_idf_tdm <- TermDocumentMatrix(text_corp, 
    control = list(weighting = weightTfIdf))
tf_idf_tdm_m <- as.matrix(tf_idf_dtm)
tf_tdm_m <- as.matrix(tf_dtm)
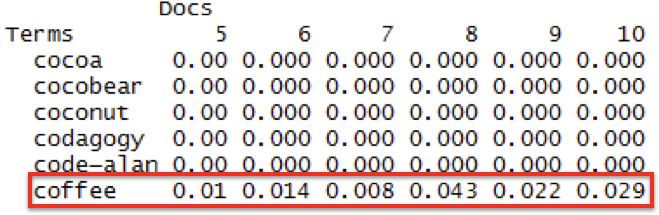
tfidf.png

R 的 Bag-of-Words 文本探勘

保留文件中繼資料

# 確保前 2 欄為 doc_id 與 text
names(tweets)[1:2] <- c('doc_id','text')

# 建立含中繼資料的 VCorpus
test_corpus <- VCorpus(DataframeSource(tweets))
# 清理並檢視結果
text_corpus <- clean_corpus(text_corpus)
content(text_corpus[[1]])
$content
[1] "ayyytylerb true drink lots coffee"
meta(text_corpus[[1]])
$meta
  id      : 1
  author  : thejennagibson
  date    : 8/9/2013 2:43
  language: en
R 的 Bag-of-Words 文本探勘

一起來練習吧!

R 的 Bag-of-Words 文本探勘

Preparing Video For Download...