從資料集到偵測模型

R 的詐欺偵測

Sebastiaan Höppner

PhD researcher in Data Science at KU Leuven

路線圖

  • (1) 將資料集分成 training settest set
  • (2) 選擇 機器學習 模型
  • (3) 在 training set 上 套用 SMOTE 平衡類別分佈
  • (4) 在重平衡後的 training set 上 訓練模型
  • (5) 在(原始的)test set 上 測試效能
R 的詐欺偵測

將資料集分成 training 與 test

  • 將資料集切成 training settest set(例如 50/50、75/25…)
  • 一開始先確保兩者的類別分佈相同
  • 範例:50% training set、50% test set
prop.table(table(train$Class))
   0    1 
0.98 0.02
prop.table(table(test$Class))
   0    1 
0.98 0.02
R 的詐欺偵測

選擇並訓練機器學習模型

  • 決策樹、人工神經網路、支援向量機、羅吉斯迴歸、隨機森林、Naive Bayes、k-Nearest Neighbors…
  • 例: Classification And Regression Tree(CART)演算法
  • rpart 套件中的 rpart 函式
library(rpart)

model1 = rpart(Class ~ ., data = train)
R 的詐欺偵測
library(partykit)
plot(as.party(model1))
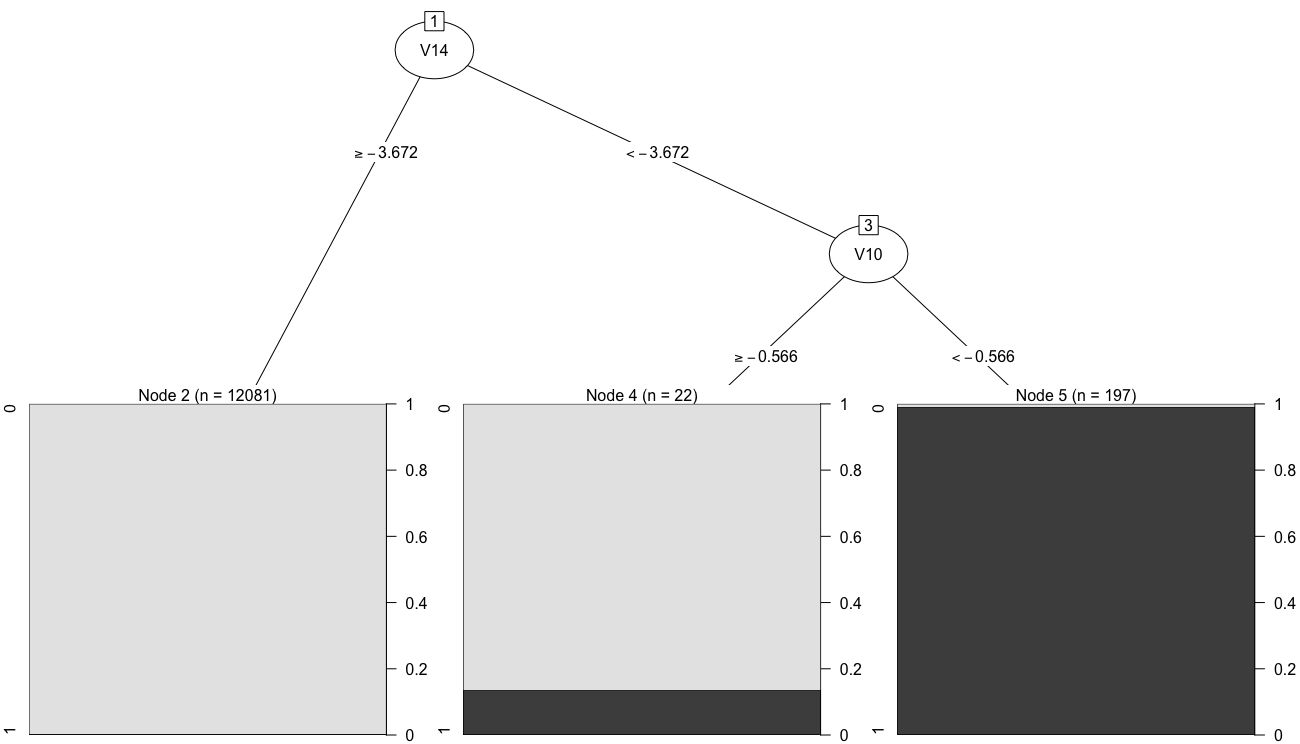
tree1

R 的詐欺偵測
## 預測 test set 的詐欺機率
scores1 = predict(model1, newdata = test, type = "prob")[, 2]

## 預測 test set 的類別(是否詐欺) predicted_class1 = factor(ifelse(scores1 > 0.5, 1, 0))
## 混淆矩陣與準確率 library(caret) CM1 = confusionMatrix(data = predicted_class1, reference = test$Class)
          Reference         
Prediction     0     1
         0 12046    55
         1     8   191       Accuracy : 0.994878
library(pROC)
auc(roc(response = test$Class, predictor = scores1)) ## Area Under ROC Curve (AUC)
Area under the ROC curve: 0.8938
R 的詐欺偵測

在 training set 上套用 SMOTE

library(smotefamily)
set.seed(123)

smote_result = SMOTE(X = train[, -17],
                     target = train$Class,
                     K = 5,
                     dup_size = 10)

train_oversampled = smote_result$data colnames(train_oversampled)[17] = "Class"
prop.table(table(train_oversampled$Class))
        0         1 
0.8166667 0.1833333
R 的詐欺偵測
library(rpart)
model2 = rpart(Class ~ ., data = train_oversampled)
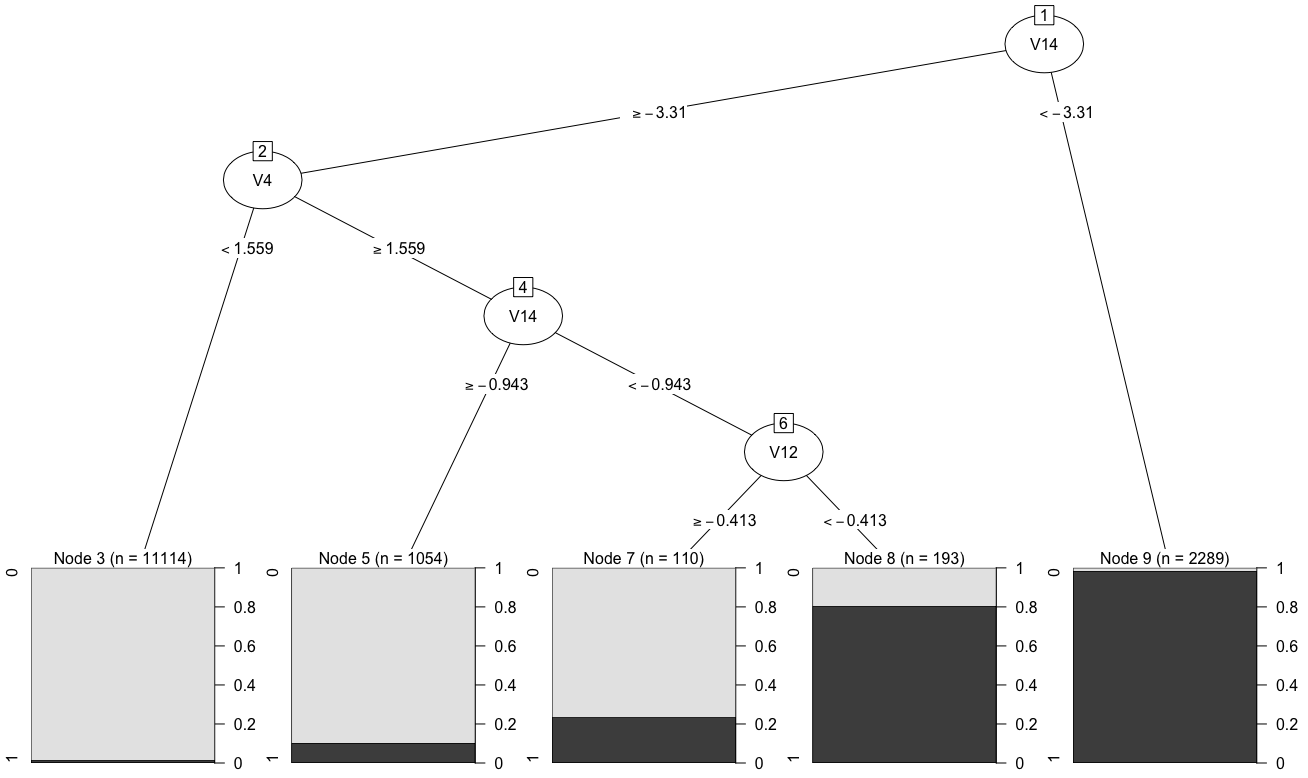
tree2

R 的詐欺偵測
## 預測 test set 的詐欺機率
scores2 = predict(model2, newdata = test, type = "prob")[, 2]

## 預測 test set 的類別(是否詐欺) predicted_class2 = factor(ifelse(scores2 > 0.5, 1, 0))
## 混淆矩陣與準確率 library(caret) CM2 = confusionMatrix(data = predicted_class2, reference = test$Class)
          Reference
Prediction     0     1
         0 11967    34
         1    87   212       Accuracy : 0.9901626                                
library(pROC)
auc(roc(response = test$Class, predictor = scores2)) ## Area Under ROC Curve (AUC)
Area under the curve: 0.9538
R 的詐欺偵測

部署偵測模型的成本

  • 在評估演算法時,納入 詐欺偵測的不同成本
  • 成本來自:
    • 錯分錯誤(偽陽性與偽陰性),以及
    • 正確分類(真陽性與真陰性)。
R 的詐欺偵測

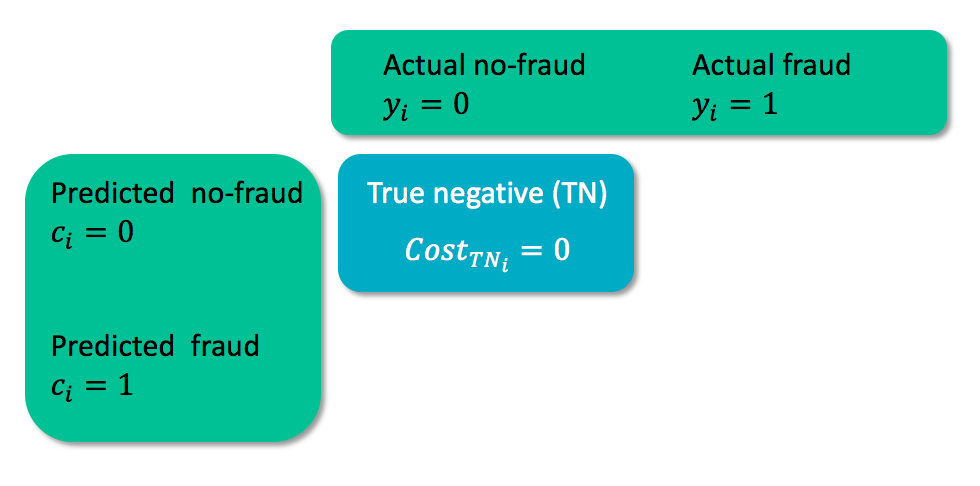
成本矩陣

cost_matrix_1

  • $y_i$ = 第 $i$ 筆個案的真實類別
  • $c_i$ = 第 $i$ 筆個案的預測類別
R 的詐欺偵測

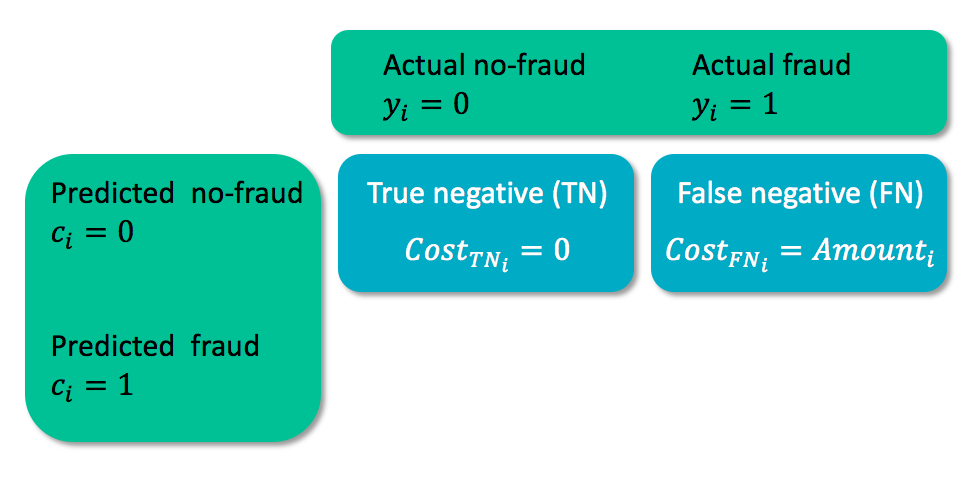
成本矩陣

cost_matrix_2

  • $y_i$ = 第 $i$ 筆個案的真實類別
  • $c_i$ = 第 $i$ 筆個案的預測類別
R 的詐欺偵測

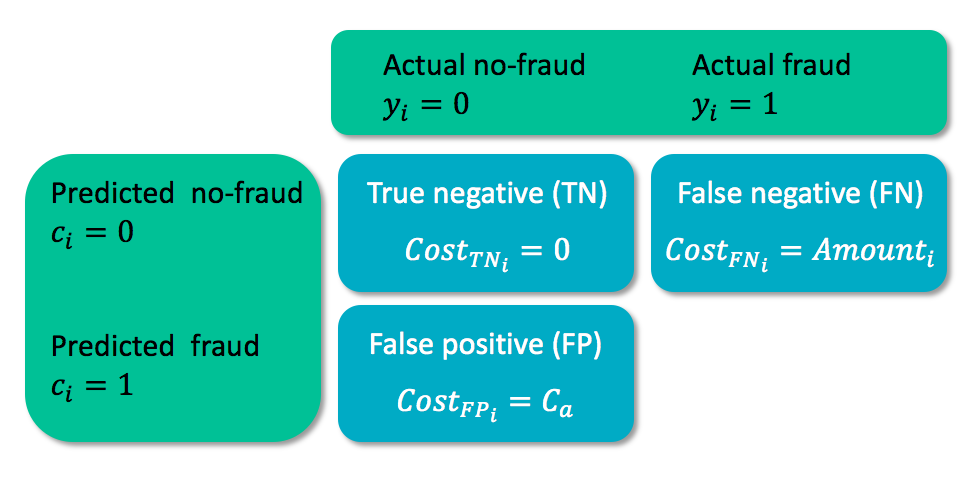
成本矩陣

cost_matrix_3

  • $C_a$ = 個案分析成本
R 的詐欺偵測

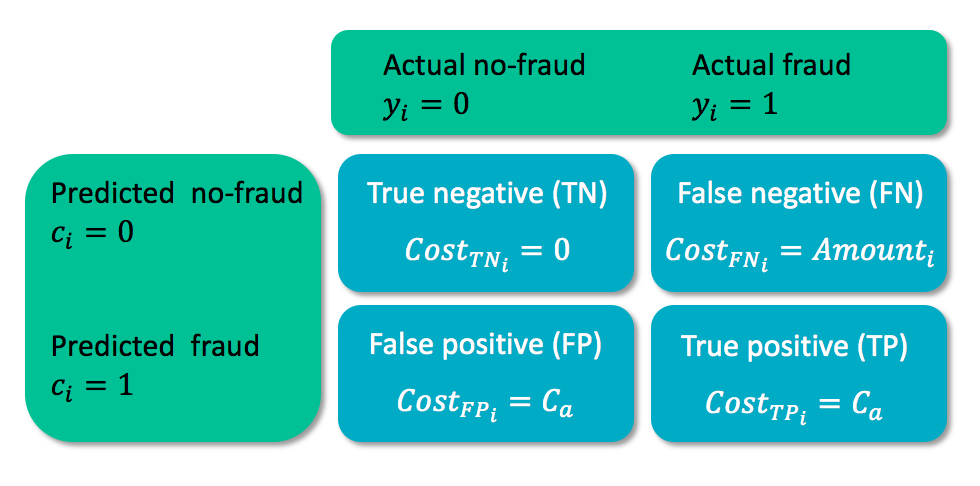
成本矩陣

cost_matrix_4

  • $C_a$ = 個案分析成本
R 的詐欺偵測

偵測模型的成本衡量

  • 納入每筆個案的實際成本: $$Cost(model)=\sum_{i=1}^{N}y_i(1-c_i)Amount_i + c_iC_a$$
    • $y_i$ = 第 $i$ 筆個案的真實類別
    • $c_i$ = 第 $i$ 筆個案的預測類別
cost_model = function(predicted.classes, true.classes, amounts, fixedcost) {

    cost = sum(true.classes * (1 - predicted.classes) * amounts +
               predicted.classes * fixedcost)

    return(cost)
}
R 的詐欺偵測

詐欺偵測的真實成本

## 不使用 SMOTE 的總成本:
cost_model(predicted_class1, test$Class, test$Amount, fixedcost = 10)
10061.8
## 使用 SMOTE 的總成本:
cost_model(predicted_class2, test$Class, test$Amount, fixedcost = 10)
7431.93
  • 損失降低 26%!
R 的詐欺偵測

一起來練習吧!

R 的詐欺偵測

Preparing Video For Download...