評估效益
R 平行程式設計

Nabeel Imam
Data Scientist
玩具範例
numbers <- 1:1000000# Sequential sqroots <- lapply(numbers, sqrt)# Parallel cl <- makeCluster(4) sqroots <- parLapply(cl, numbers, sqrt) stopCluster(my_cluster)
哪個表現更好?
效能評測
重複執行以估計平均執行時間
library(microbenchmark)microbenchmark( "Sequential" = lapply(numbers, sqrt),"Parallel" = { cl <- makeCluster(4) parLapply(cl, numbers, sqrt) stopCluster(my_cluster) },times = 10 )
Unit: milliseconds
      expr     min    mean     max neval
Sequential  633.96  838.09  993.59    10
  Parallel 1136.95 1247.29 1557.58    10
- 簡單數值運算很少因平行化而受益
- Profiling 提供逐行報告,Benchmarking 提供整體執行時間
顯而易見的問題
sqroots <- sqrt(numbers)
向量化
sqroots <- sqrt(numbers)
- Base R 函式(如
sqrt())具向量化特性。 - 將單一函式套用到多個輸入
- 很快,但只適用於簡單操作
microbenchmark(
  "Vectorized" = sqrt(numbers),
  "Sequential" = lapply(numbers, sqrt),
  "Parallel" = {
    cl <- makeCluster(4)
    parLapply(cl, numbers, sqrt)
    stopCluster(my_cluster)
  },
  times = 10)
Unit: milliseconds
      expr       min      mean      max neval
Vectorized    2.3904    9.2071   66.303    10
Sequential  352.1166  771.7491 1004.753    10
  Parallel 1191.3176 1377.6926 1700.316    10
自助法(Bootstrap)
對現有資料進行可重複抽樣(有放回)
print(ls_df)
$`2001`
   Country             Life_expectancy  Year
 1 Afghanistan                    56.3  2001
 2 Albania                        74.3  2001
 3 Algeria                        71.1  2001
...
$`2002`
   Country             Life_expectancy  Year
 1 Afghanistan                    56.8  2002
 2 Albania                        74.6  2002
 3 Algeria                        71.6  2002
...
經典做法
df <- ls_df$`2001`estimates <- rep(0, 10000)for (i in 1:10000) { b <- sample(df$Life_expectancy, replace = T)estimates[i] <- mean(b) }
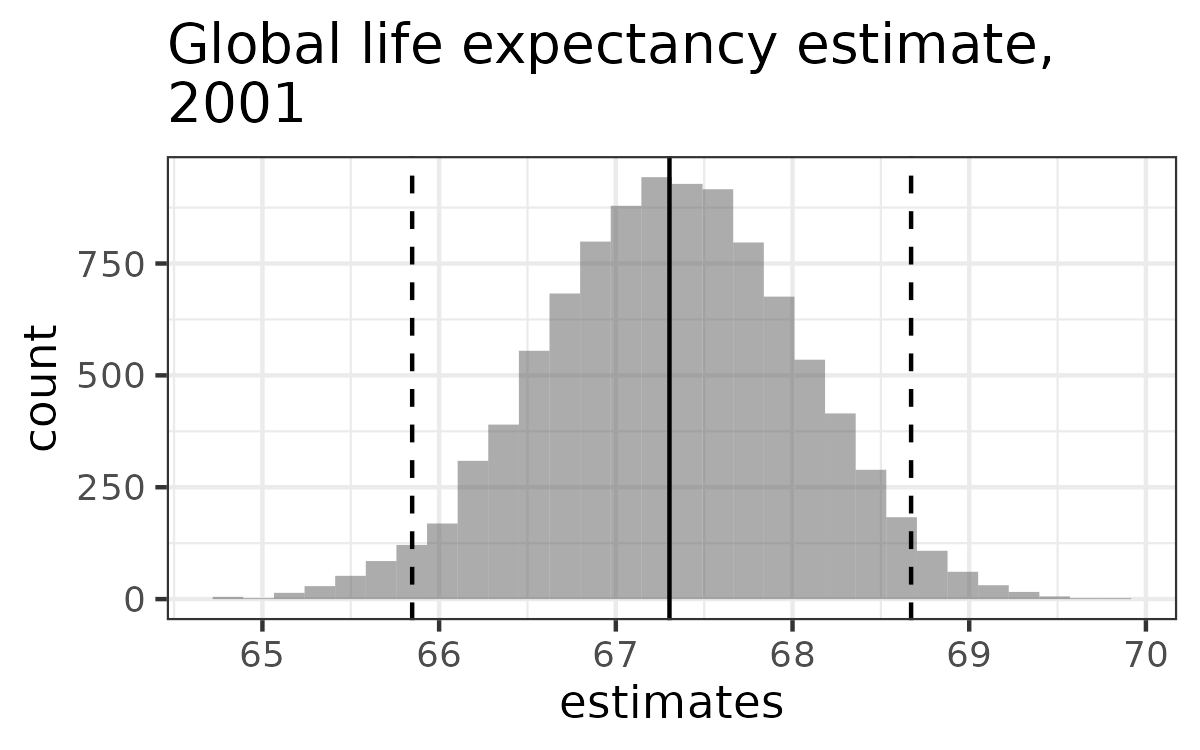
- 用分位數求信賴區間:
quantile(estimates, c(0.025, 0.975))
好消息
自助抽樣可平行化
estimates <- rep(0, 10000)

for (i in 1:10000) {

  b <- sample(df$Life_expectancy,
              replace = T)

  estimates[i] <- mean(b)
  }
boot_dist <- function (df) { estimates <- rep(0, 10000) for (i in 1:10000) { b <- sample(df$Life_expectancy, replace = T) estimates[i] <- mean(b) } return(estimates) }cl <- makeCluster(4) ls_dists <- parLapply(cl, ls_df, boot_dist) stopCluster(cl)
帶來的效益
microbenchmark(
  "lapply" = lapply(ls_df, boot_dist),
  "parLapply" = {
    cl <- makeCluster(4)
    parLapply(cl, ls_df, boot_dist)
    stopCluster(cl)
  },
  times = 10
)
Unit: seconds
     expr    min   mean    max neval
   lapply 3.6938 4.2184 4.5267    10
parLapply 1.9006 2.5166 2.7292    10
如何達成:
- 先剖析既有程式碼,找出最慢步驟
- 對該步驟做平行化/最佳化
- 進行效能比較(Benchmark)
一起來練習吧!
R 平行程式設計

