R 的降維
Matt Pickard
Owner, Pickard Predictives, LLC
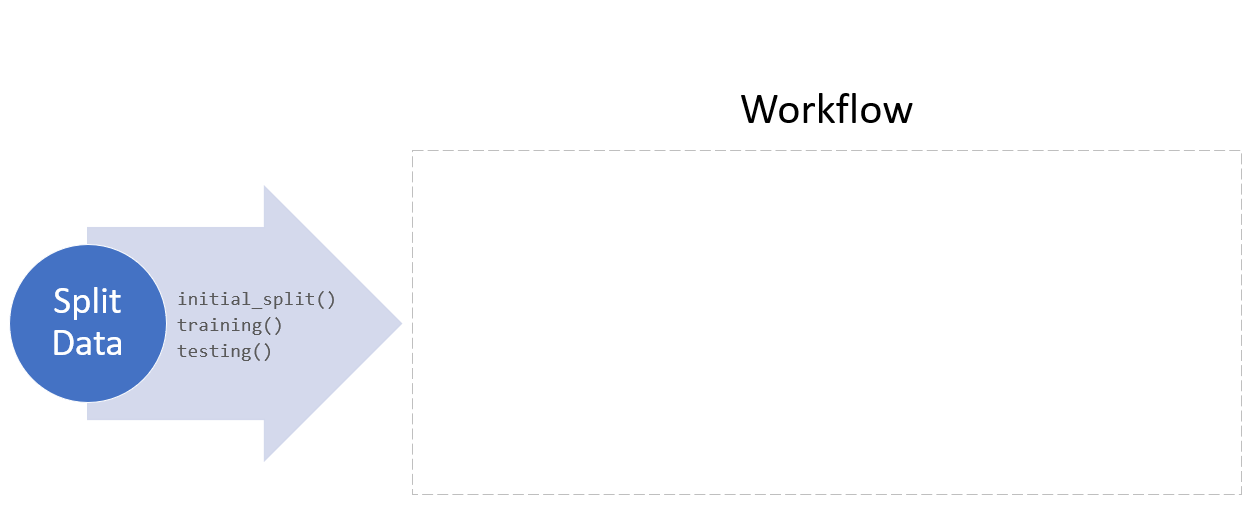
split <- initial_split(credit_df, prop = 0.8, strata = credit_score)


train <- split %>% training()


test <-  split %>% testing()
split <- initial_split(credit_df, prop = 0.8, strata = credit_score)
train <- split %>% training()
test <- split %>% testing()
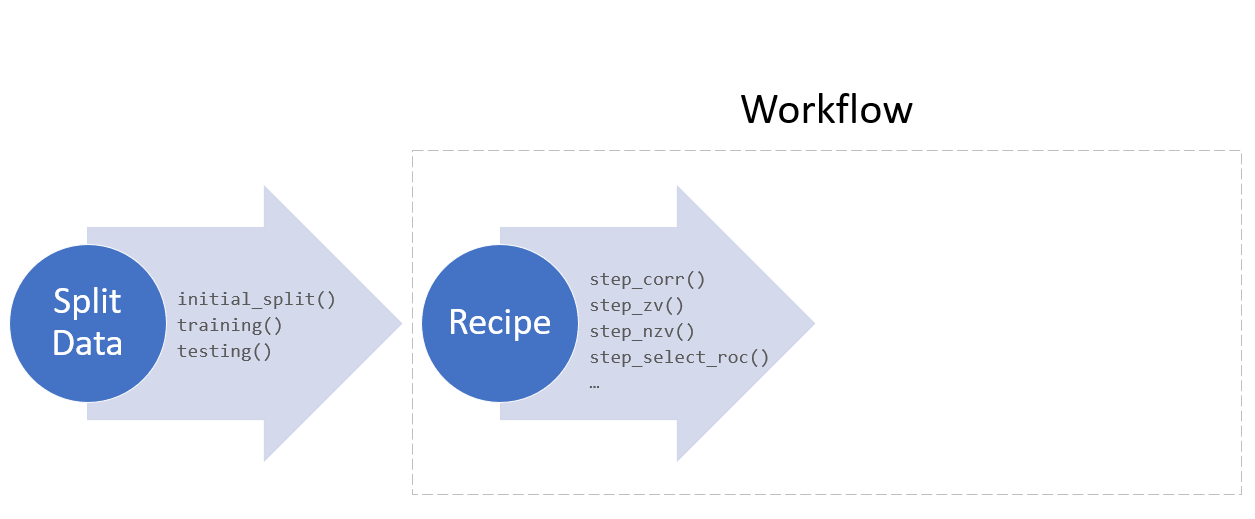
feature_selection_recipe <-
  recipe(credit_score ~ ., data = train) %>%

  step_filter_missing(all_predictors(), threshold = 0.5) %>%

  step_scale(all_numeric_predictors()) %>%

  step_nzv(all_predictors()) %>%

  prep()
feature_selection_recipe <- recipe(credit_score ~ ., data = train) %>%
step_filter_missing(all_predictors(), threshold = 0.5) %>%
step_scale(all_numeric_predictors()) %>%
step_nzv(all_predictors()) %>%
prep()
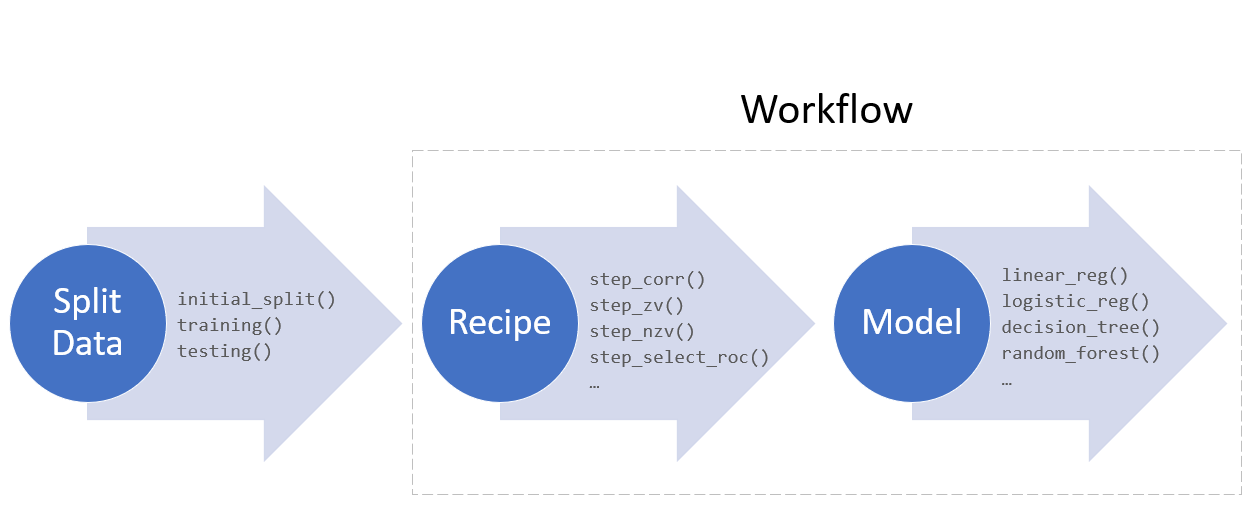
lr_model <- logistic_reg() %>%

  set_engine("glm")
lr_model <- logistic_reg() %>%
set_engine("glm")
credit_wflow <- workflow() %>%

  add_recipe(feature_selection_recipe) %>%

  add_model(lr_model)


credit_fit <-
  credit_wflow %>% fit(data = train)
credit_wflow <- workflow() %>%
add_recipe(feature_selection_recipe) %>%
add_model(lr_model)
credit_fit <- credit_wflow %>% fit(data = train)
# 預測測試資料
credit_pred_df <- predict(credit_fit, test) %>%
  bind_cols(test %>% select(credit_score))


# 評估 F 分數
f_meas(credit_pred_df, credit_score, .pred_class)
# 預測測試資料 credit_pred_df <- predict(credit_fit, test) %>% bind_cols(test %>% select(credit_score))
# 評估 F 分數 f_meas(credit_pred_df, credit_score, .pred_class)
# A tibble: 1 × 3
  .metric .estimator .estimate
  <chr>   <chr>          <dbl>
1 f_meas  macro          0.519
tidy(feature_selection_recipe, number = 1)
# A tibble: 2 × 2
  terms            id
  <chr>            <chr>
1 age              filter_missing_gVVfc
2 outstanding_debt filter_missing_gVVfc
# 顯示模型估計值
tidy(credit_fit)
# A tibble: 44 × 5
   term                estimate std.error statistic p.value
   <chr>                  <dbl>     <dbl>     <dbl>   <dbl>
 1 (Intercept)           2.88       0.918    3.13   0.00173
 2 monthAugust          -0.449      0.236   -1.91   0.0565
 3 monthFebruary        17.7      677.       0.0262 0.979
 4 monthJanuary         17.7      661.       0.0268 0.979
 ...                    ...       ...        ...    ...