R 的降維
Matt Pickard
Owner, Pickard Predictives, LLC
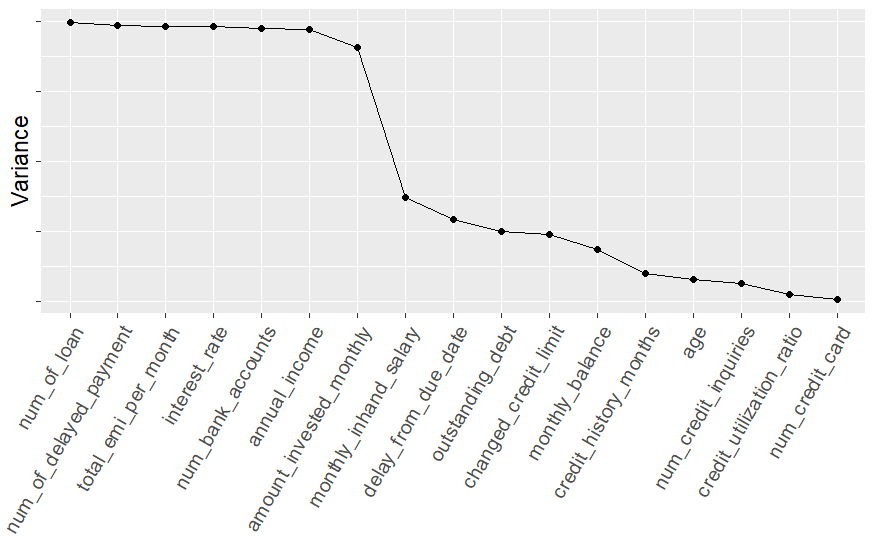
credit_variances <- credit_df %>%
  summarize(across(everything(), ~ var(scale(., center = FALSE)), na.rm = TRUE)) %>%

  pivot_longer(everything(), names_to = "feature", values_to = "variance") %>%

  arrange(desc(variance))

credit_variances
credit_variances <- credit_df %>% summarize(across(everything(), ~ var(scale(., center = FALSE)), na.rm = TRUE)) %>%
pivot_longer(everything(), names_to = "feature", values_to = "variance") %>%
arrange(desc(variance)) credit_variances
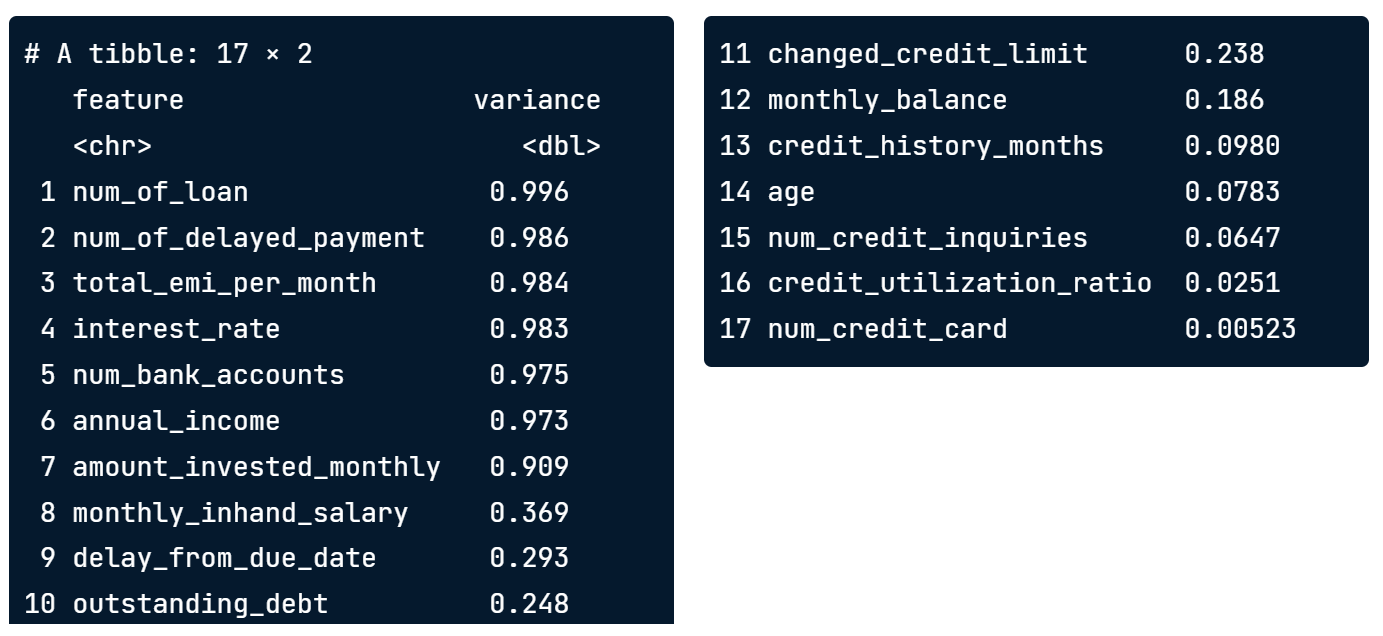
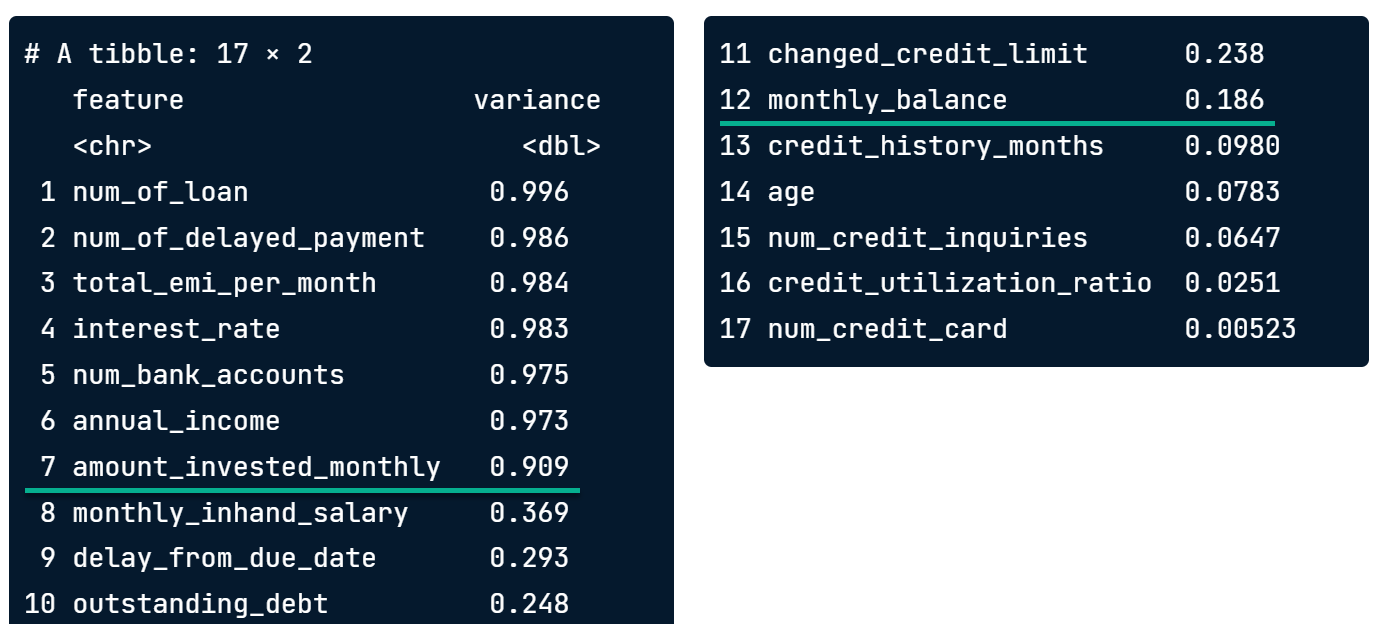
# A tibble: 17 × 2
   feature                  variance
   <chr>                       <dbl>
 1 num_of_loan               0.996
 2 num_of_delayed_payment    0.986
 ...
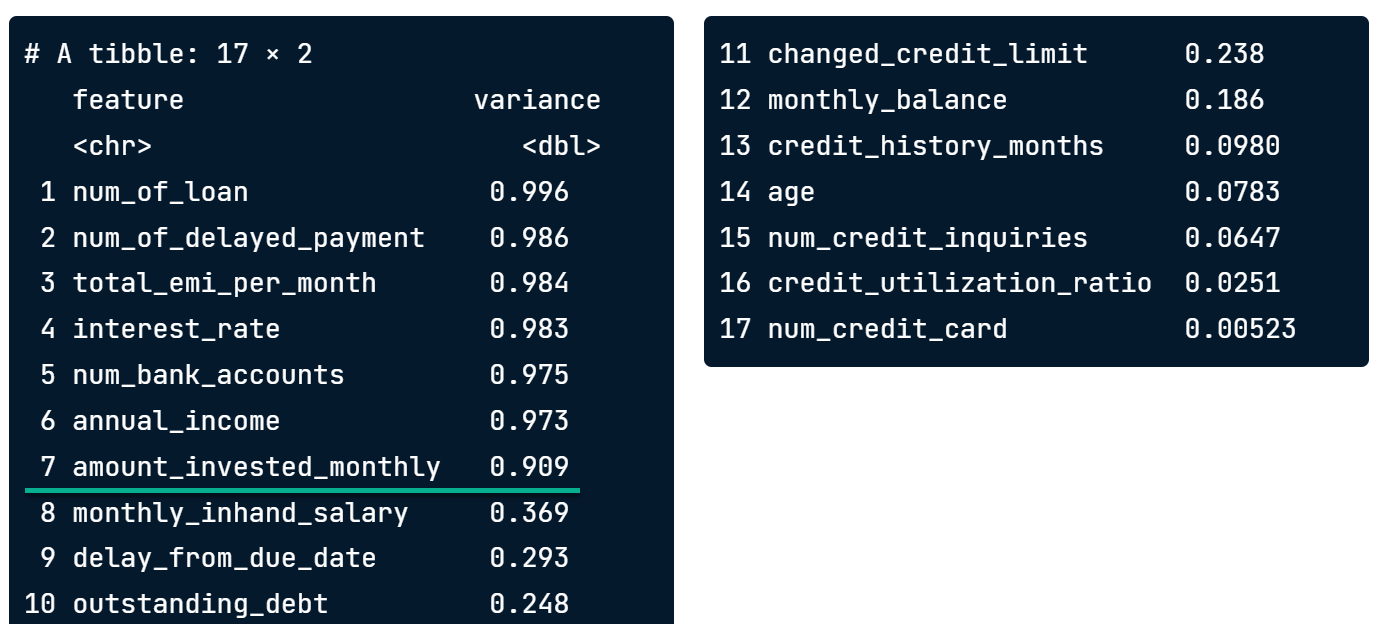
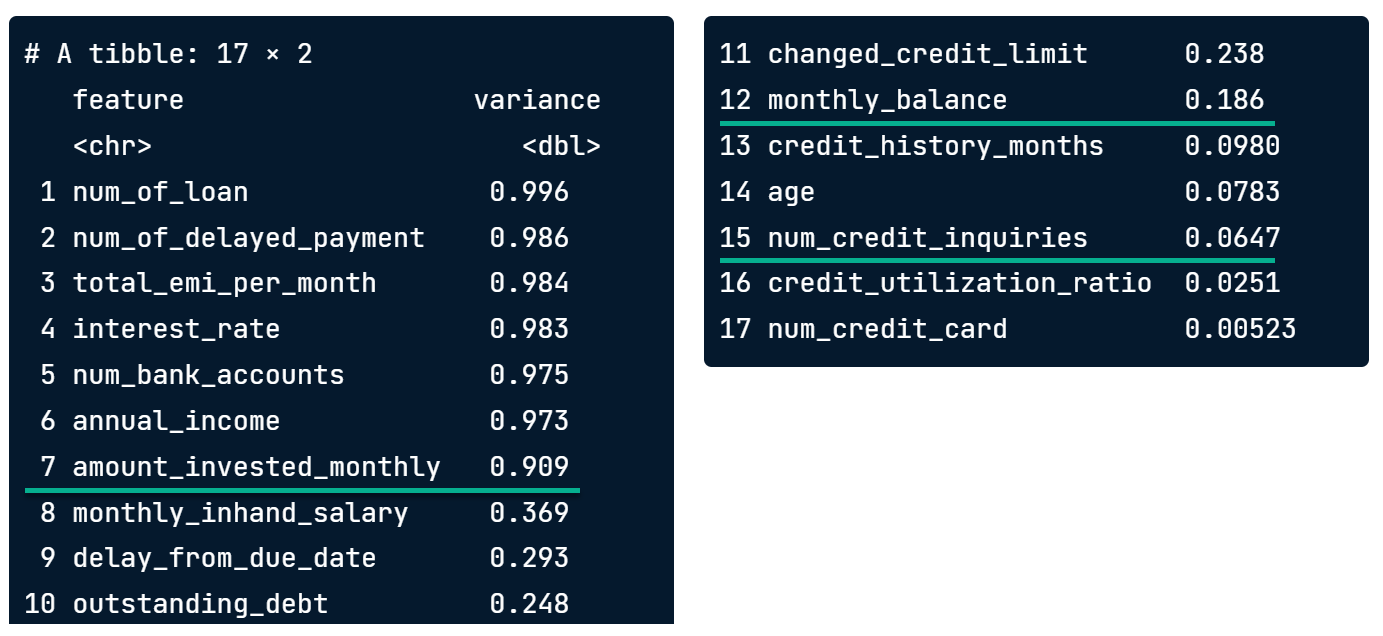
low_var_filter <- credit_variances %>%
  filter(variance < 0.1) %>%
  pull(feature)

low_var_filter
[1] "credit_history_months"    "age"
[3] "num_credit_inquiries"     "credit_utilization_ratio"
[5] "num_credit_card"
low_variance_recipe <- recipe(credit_score ~ ., data = credit_df) %>%

  step_zv(all_predictors()) %>%

  step_scale(all_numeric_predictors()) %>%

  step_nzv(all_predictors()) %>%

  prep()
low_variance_recipe <- recipe(credit_score ~ ., data = credit_df) %>%
step_zv(all_predictors()) %>%
step_scale(all_numeric_predictors()) %>%
step_nzv(all_predictors()) %>%
prep()
filtered_credit_df <- bake(low_variance_recipe, new_data = NULL)
low_variance_recipe <- recipe(credit_score ~ ., data = credit_df) %>%
  step_zv(all_predictors()) %>%
  step_scale(all_numeric_predictors()) %>%
  step_nzv(all_predictors()) %>%
  prep()


tidy(low_variance_recipe, number = 3)
tidy(low_variance_recipe, number = 3)
  terms                id
  <chr>                <chr>
1 num_credit_card      nzv_ni8L7
2 num_credit_inquiries nzv_ni8L7